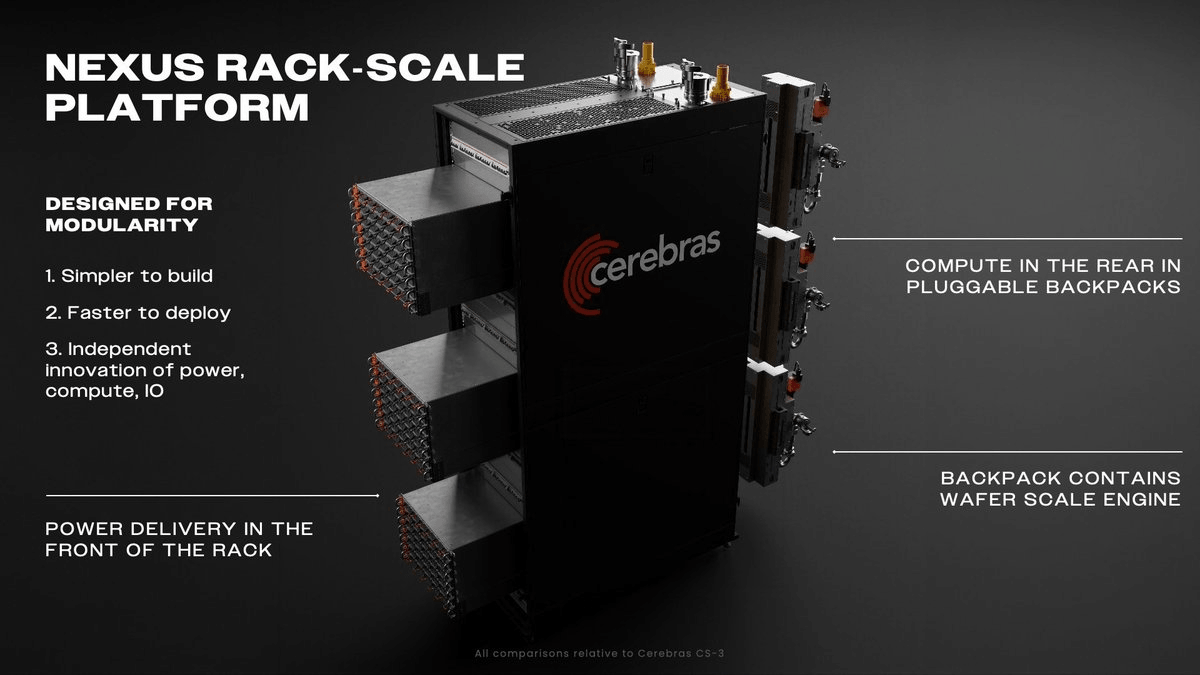
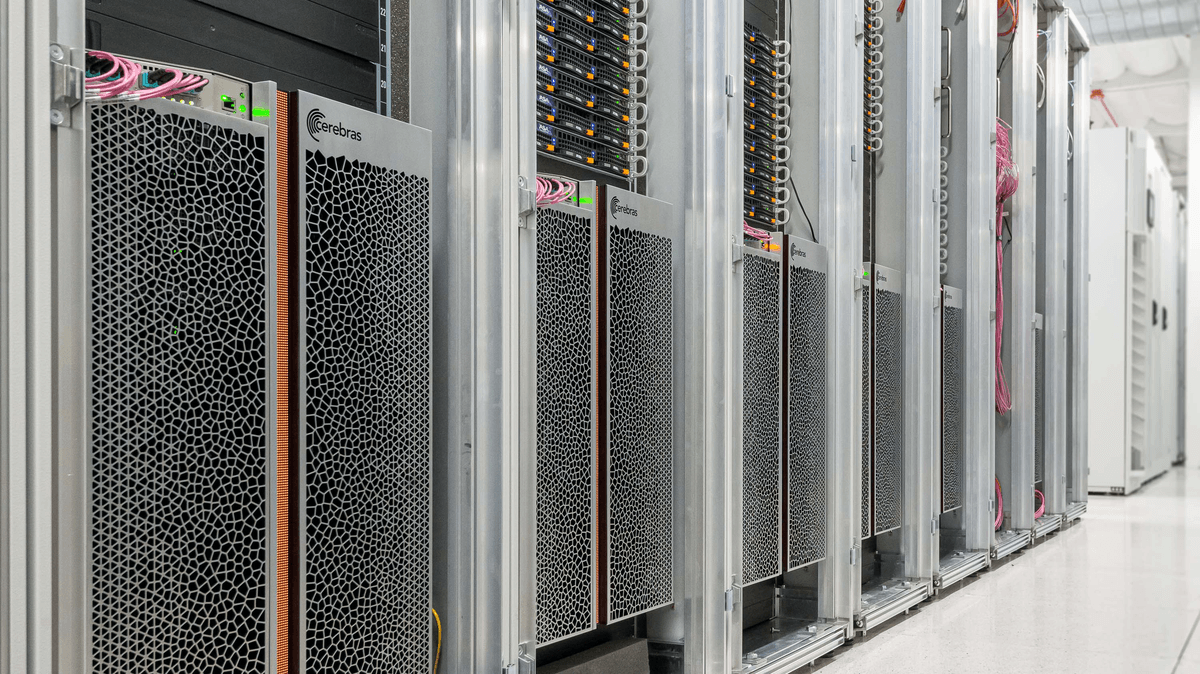
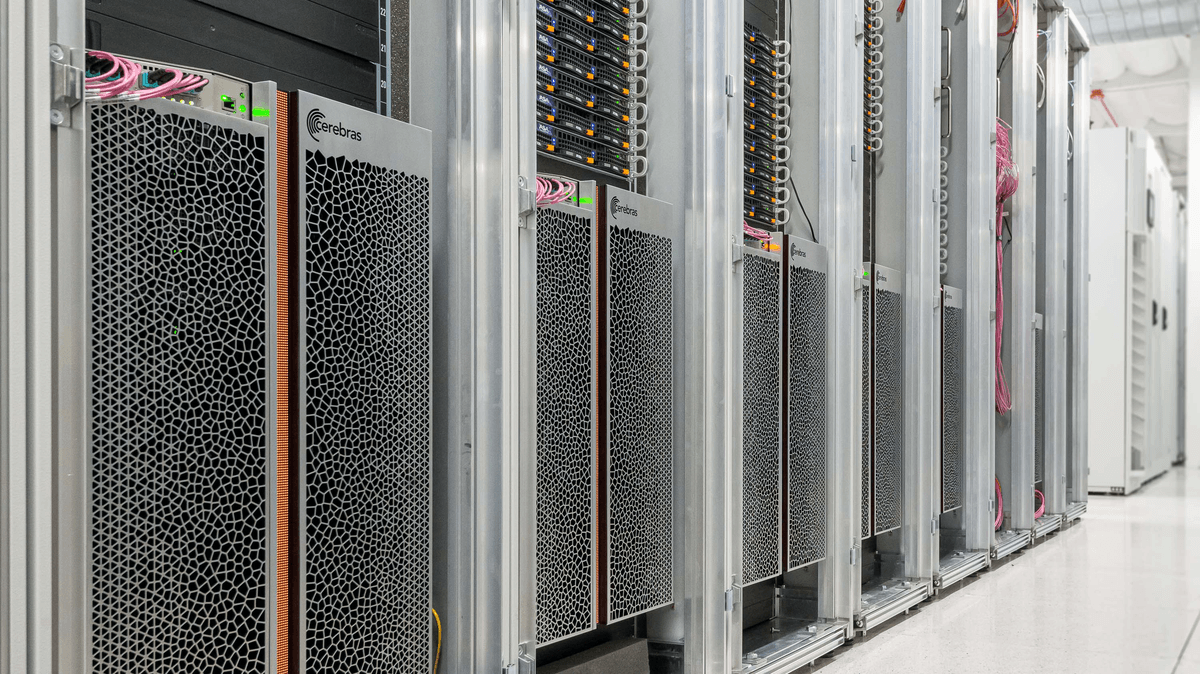
Builds the WSE-3, a wafer-scale processor with 900,000 AI-optimized cores and 44 GB on-chip SRAM on a single die, eliminating GPU cluster interconnect overhead. Powers the CS-3 system and a cloud inference API serving open models like Llama, DeepSeek R1, and Qwen3 at thousands of tokens per second with OpenAI-compatible endpoints.
Alibaba's 27B dense multimodal model lands on Cerebras at roughly 1,800 tokens per second, with reasoning on by default and a 128K context on paid tiers.
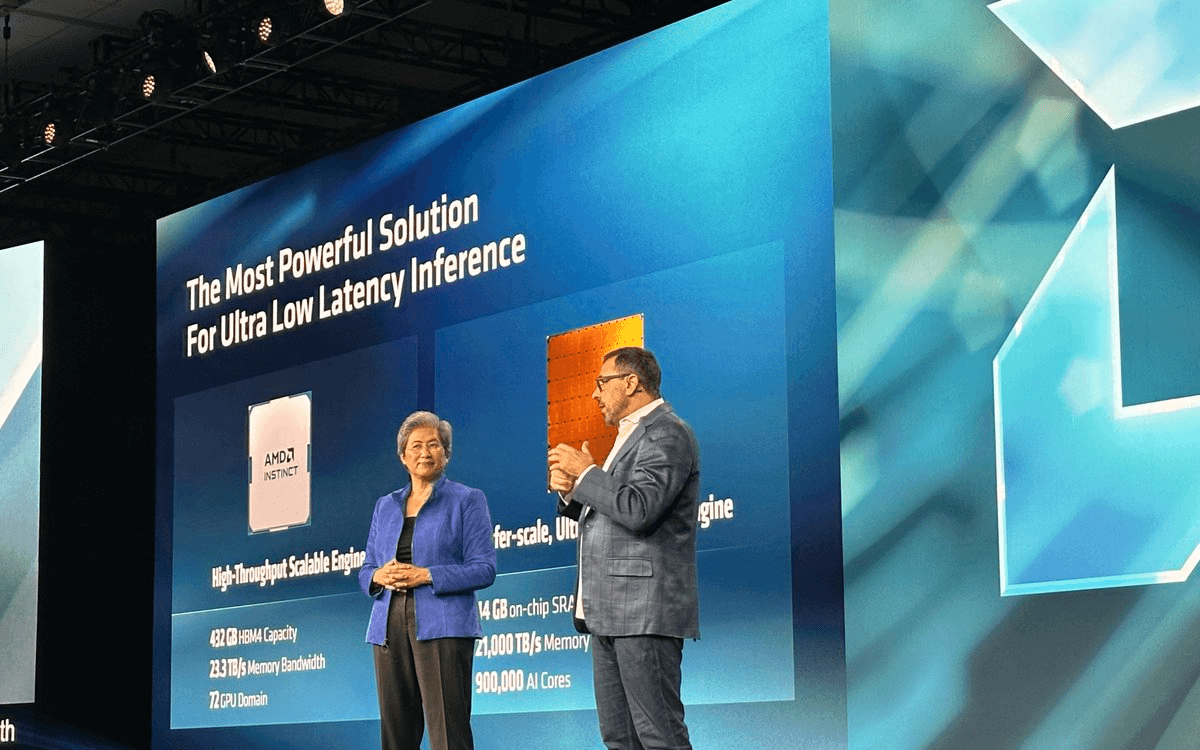
AMD and Cerebras pair Helios rack-scale GPUs with the Wafer-Scale Engine to deliver the fastest production inference on trillion-parameter models at 5x greater efficiency
CrowdStrike's Falcon AIDR will run on Cerebras wafer-scale inference, pairing the world's fastest AI hardware with the leading AI-native security platform to stop attacks in real time.
Upstage's Solar 31B now runs at up to 2,000 tokens/sec on Cerebras hardware, making deep research queries across hundreds of sources feel nearly instant.
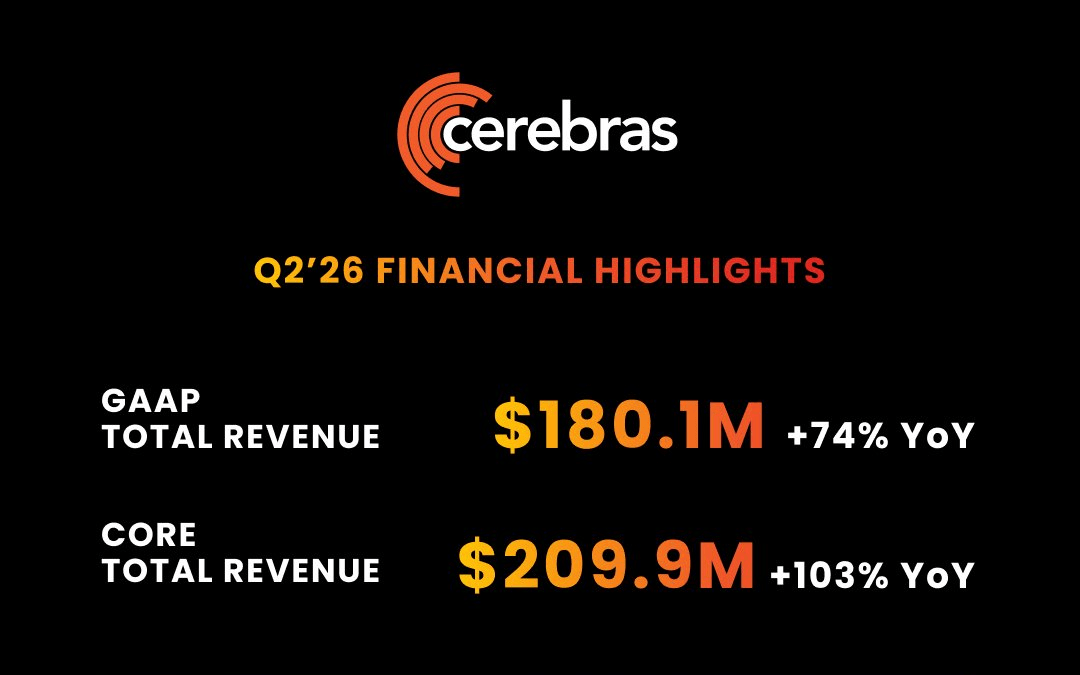
Cerebras launches a global Ambassador Program to seed grassroots AI communities around its record-breaking inference platform, fresh off a blockbuster IPO.
Cerebras brings Google DeepMind's Gemma 4 to its wafer-scale hardware, hitting 1,500+ tokens per second — 15x faster than Claude Haiku — and launches a $5,000 hackathon to celebrate.
Cerebras runs Kimi K2.6 at 981 tokens/sec — 5.4x faster than Google's new speed-first Gemini 3.5 Flash, and fast enough for real-time voice with a trillion-parameter model.
Cerebras lets dedicated inference users swap LoRA adapters per request with zero reload overhead, unlocking cheap multi-tenant model specialization at wafer-scale speed