Post-training data vendor for coding LLMs, competing with Scale AI and Surge. Sources expert-written datasets through Shipd, a bounty marketplace with 1,400+ engineers paid per task. Ships DeepSWE, a long-horizon agentic coding benchmark, and delivers RL environments as dockerized repos with pytest harnesses ready for training pipelines.
Kimi K3 debuts at #3 on DeepSWE, matching Claude Fable and GPT-5.6 Sol as the first open-weights model to reach frontier-level coding performance at 2.8 trillion parameters.
Datacurve's DeepSWE leaderboard now shows GPT-5.6 Sol, Terra, and Luna results — Sol tops all 13 models at 73%, with striking cost-performance gaps across the family.
Claude Fable 5 takes the top spot on DeepSWE's contamination-free, long-horizon coding benchmark, dethroning GPT-5.5 with a 70% pass@1 score on harder, more realistic tasks.
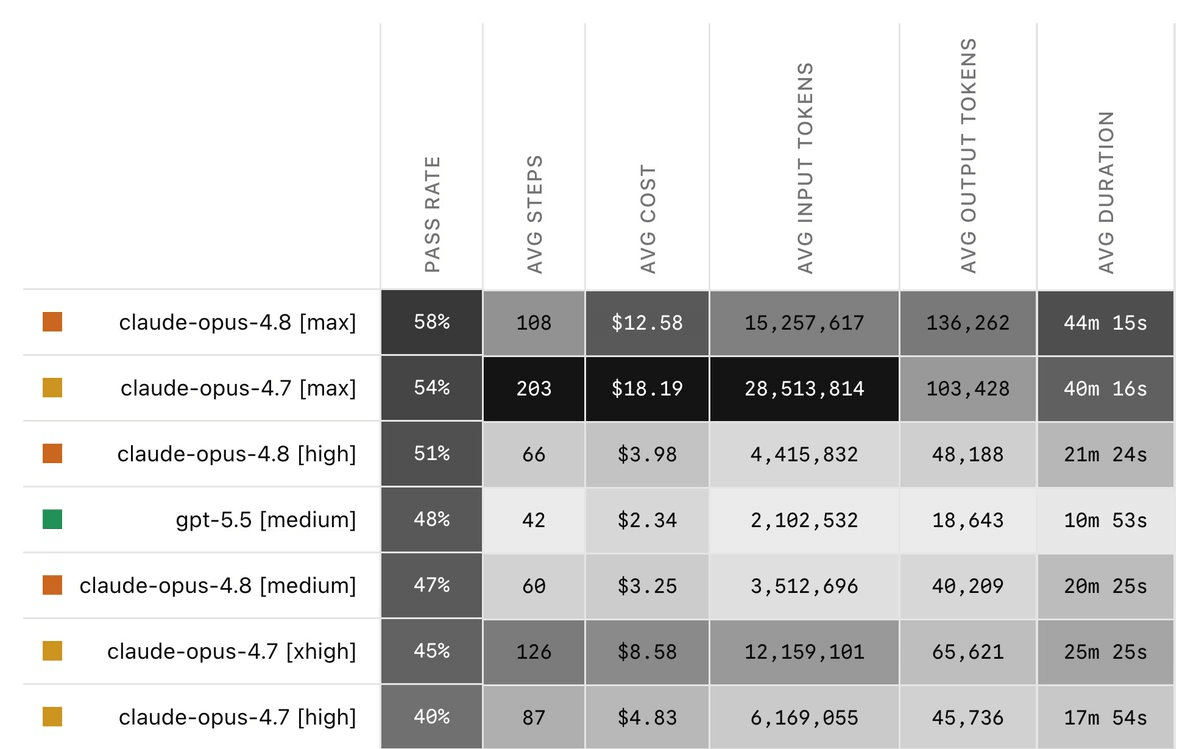
Datacurve adds Claude Opus 4.8 to DeepSWE, revealing a 6% accuracy gain over Opus 4.7 at lower cost — but GPT-5.5 still leads the leaderboard by 12 points