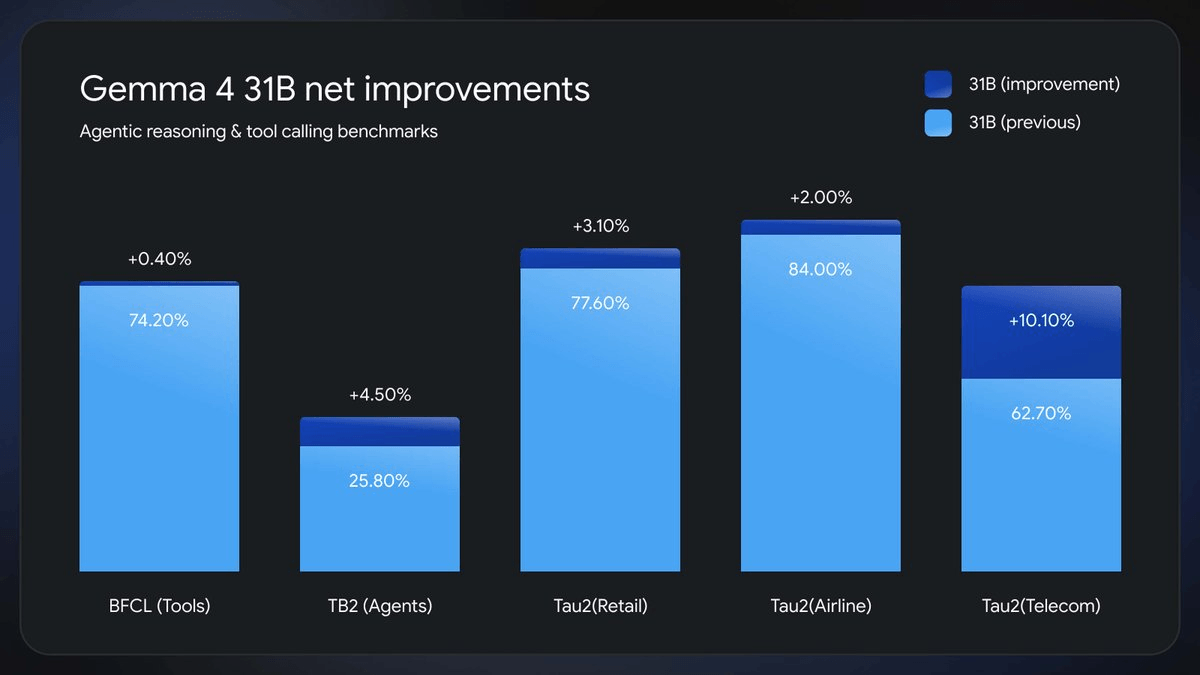
Google's open-weight model family for developers who need to self-host or fine-tune. Distilled from Gemini research, Gemma 4 ships in four sizes (E2B to 31B Dense), uses a hybrid local/global attention architecture with up to 256K context, and the 31B model ranks #3 on Arena AI's open-model leaderboard under a fully commercial Apache 2.0 license.
Google DeepMind's 740M-parameter multimodal embedder unifies text, code, images, video, and audio in one 768-dim space, beating models up to 12x larger.
Google's Antigravity SDK now runs agentic workflows entirely offline using Gemma 4 26B and LiteRT, with hybrid cloud-local orchestration for privacy-sensitive code.
Google DeepMind's Gemma 4 technical report reveals how a 31B open-weight model rivals frontier giants through encoder-free multimodality, MoE efficiency, and speculative decoding.
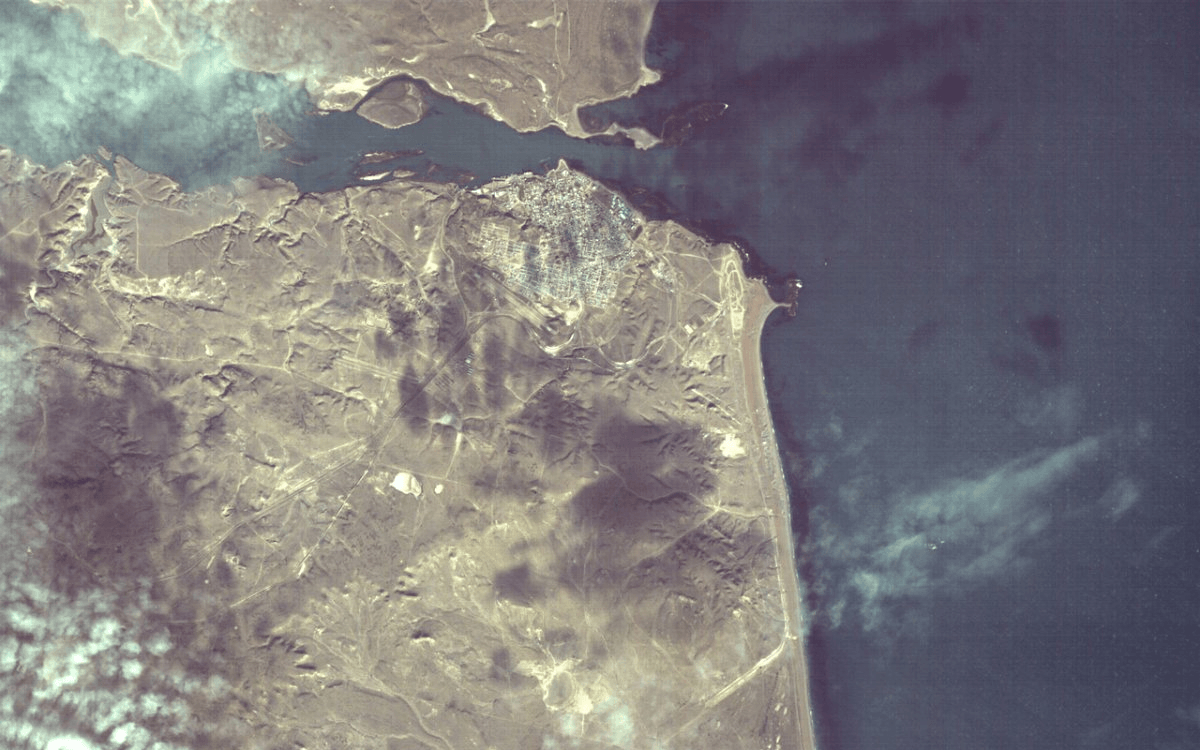
NASA's JPL ran Google's Gemma 3 vision-language model aboard a Loft Orbital satellite, marking the first time a VLM has ever analyzed imagery autonomously in space.
Google and Hugging Face launch a live, multi-agent competition to push Gemma 4 E4B inference speed as high as possible on a single A10G GPU — with results updating in real time.