Paris-based voice AI startup for developers. Offers STT, TTS, and voice cloning via API, targeting under-200ms end-to-end latency. Founded by ex-Kyutai researchers who built Moshi, a speech-native model that skips text conversion entirely. Competes with ElevenLabs and OpenAI in the voice infrastructure layer.
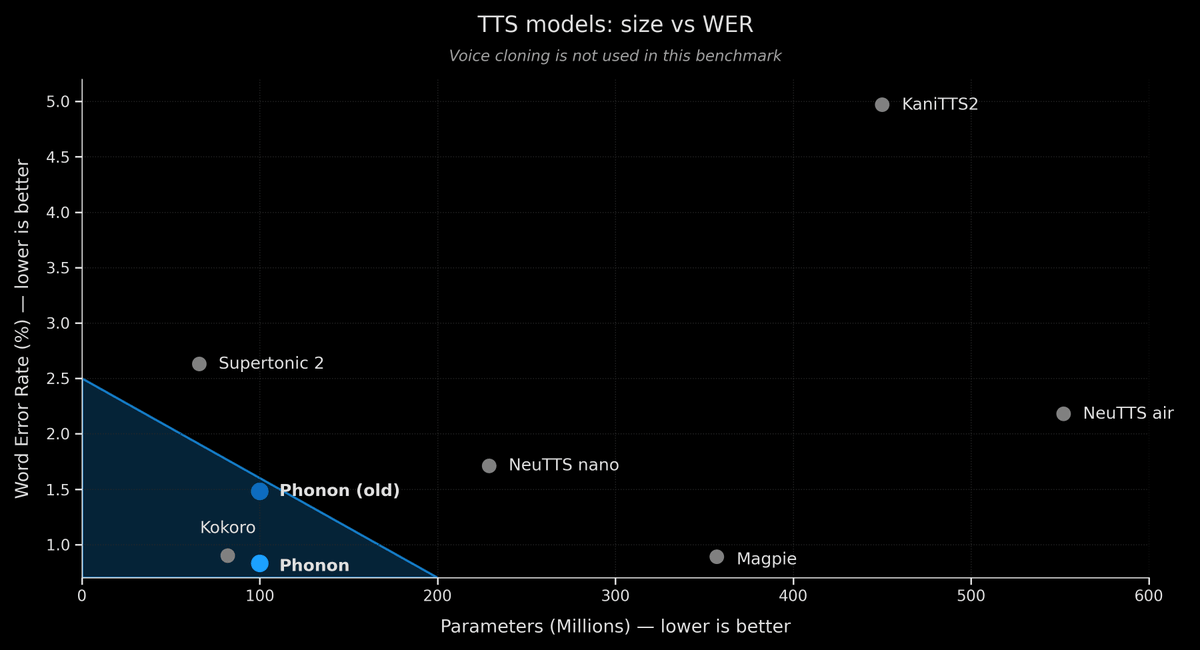
Gradium's 100M-parameter on-device TTS model hits 1.00% WER on Seed-TTS, beating models up to 5x its size while adding int8 quantization and removing latency-killing input padding.