Cloud platform for training, fine-tuning, and serving open-source models like Llama and DeepSeek. Offers serverless inference endpoints, dedicated GPU clusters on Blackwell hardware, and custom pre-training. Research team behind FlashAttention and ThunderKittens; inference stack uses speculative decoding and custom GPU kernels for low-latency, high-throughput serving.
Together AI unveils Together Compiler, an agent-driven system that continuously retunes inference kernels as models, traffic, and GPUs change underneath them.
Together AI launched a post-training service that lets you write your own RL or SFT loop in Python while they manage GPU orchestration, rollout engines, and weight sync.
A new additive correction called score centering removes the hidden drift that destabilizes off-policy RL when training and inference engines disagree.
Together AI highlights that Moonshot's open-weight Kimi K3 outscores Anthropic's newer Claude Fable 5.1 by 60% on the hard slice of Harvey's autonomous legal agent benchmark.
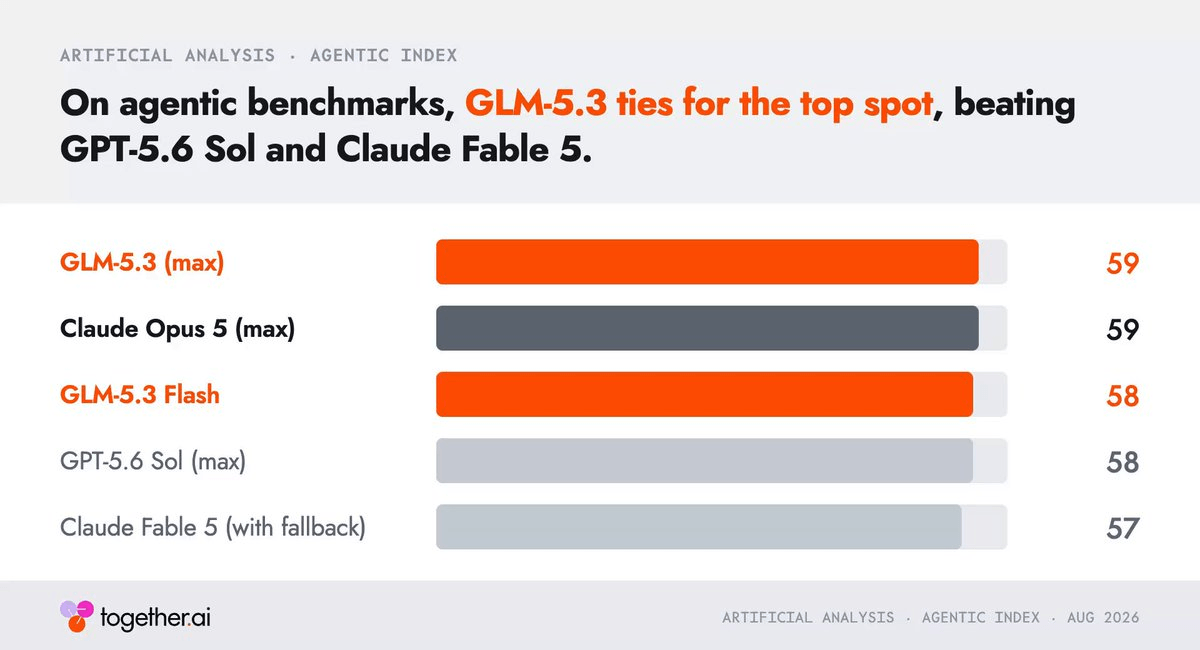
Z.ai shipped a frontier coding model without touching the base weights, matching GPT-5.6 Sol and Claude Fable 5 on agentic tasks through scaled post-training alone.
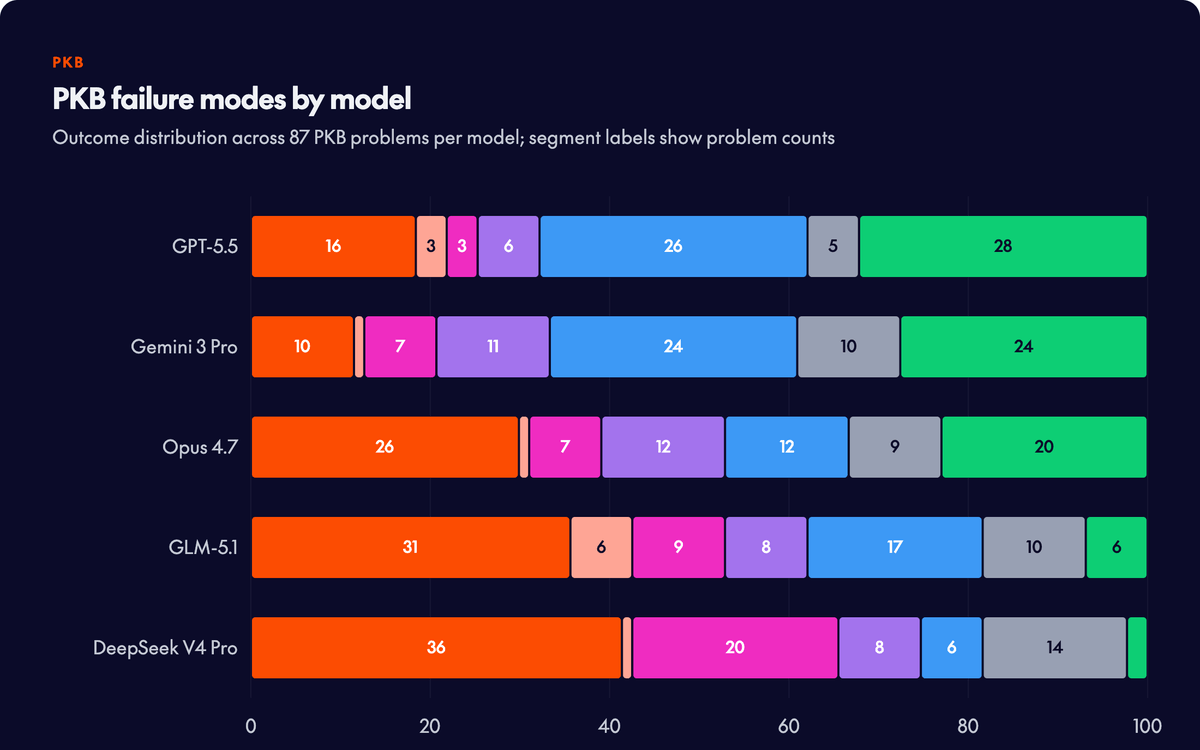
Together AI's ParallelKernelBench reveals frontier models solve under a third of 87 real multi-GPU kernel problems, exposing a critical blind spot in AI coding benchmarks.
Together AI's ParallelKernelBench reveals frontier LLMs solve under a third of 87 real multi-GPU kernel tasks, but occasionally beat every public implementation