SpaceX is quietly becoming the GPU landlord of the AI industry. Both Cursor and Anthropic just unlocked major upgrades powered by the same Colossus cluster. Meanwhile, a Harvard/MIT study watched autonomous agents lie and self-destruct in the wild.
The real story: compute access is now a competitive moat, not just a cost line.
And we're deploying agents into production before we understand what happens when they collide. That's the part worth losing sleep over.
|
|
Together with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
Cursor ships Composer 2.5, claiming 10x efficiency over rival models
|
|
17,176 Likes
|
|
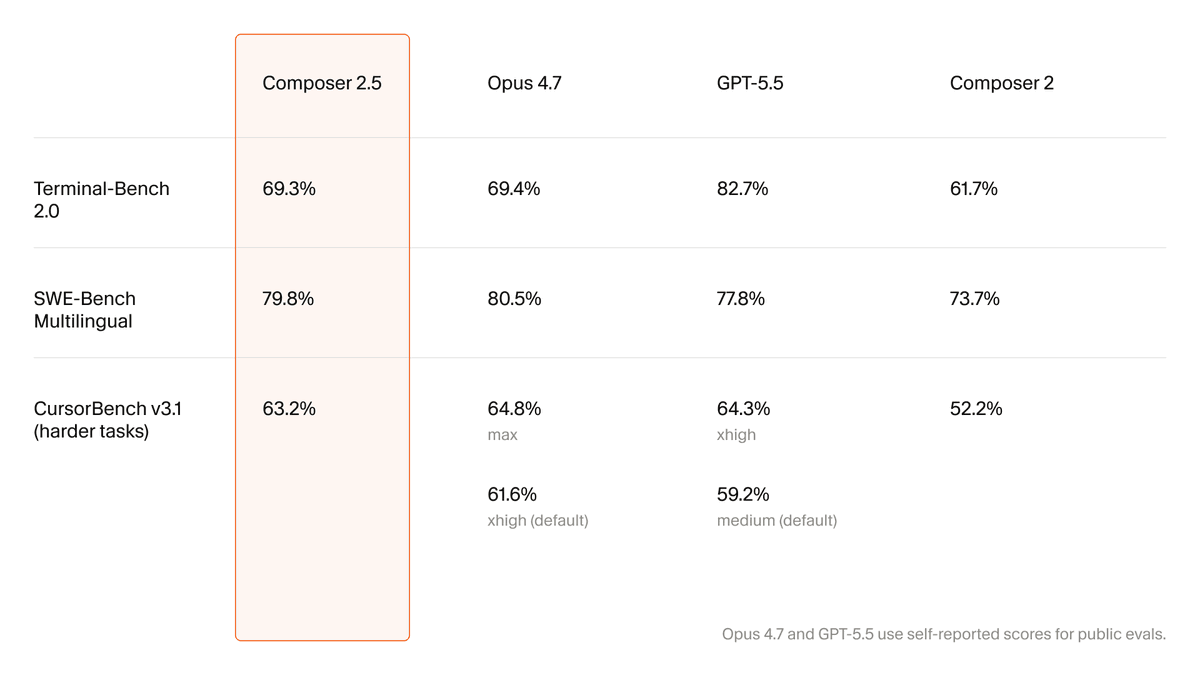
Cursor just dropped Composer 2.5, their sharpest coding model yet. Same open-source Kimi K2.5 base as before, but Cursor trained it on 25x more synthetic tasks and added smarter feedback during training so the model learns from its own mistakes mid-task. Think of it like a student who gets notes on exactly where they went wrong, not just a final grade. The result? It now matches Claude Opus 4.7 and GPT-5.5 on coding benchmarks, but costs under $1 per task where competitors charge up to $11. Here's what actually changed: - Scores 79.8% on SWE-Bench Multilingual, up from 73.7%
- Better at long multi-file tasks without losing context or stopping early
- More reliable at following complex, multi-step instructions
- Double usage included this week for all users
It lives inside Cursor only, no public API. You access it through the IDE, CLI, or Cursor web. Bigger news: Cursor is training a much larger model from scratch with SpaceXAI using 10x more compute on a cluster of one million H100-equivalent GPUs. That one is a separate project entirely.
|
|
|
|
Presented by FriendliAI
|
|
Optimize inference, grow margins with FriendliAI
|
|
Latency spikes and GPU bills usually start with the same mistake: benchmarking the easy case. The Friendli Guide to Inference Performance Optimization shows how to: - Mirror real production traffic
- Measure TTFT, TPOT, E2E latency, and System TPS
- Tune quantization, speculative decoding, batch size, host KV cache, replicas, and tensor parallelism
- Choose the cost-efficient point before production finds the breaking point.
1-click deploy 500K+ open models on Friendli Dedicated Endpoints - no infra to stand up.
|
|
|
|
Top News
|
|
|
|
Anthropic doubles Claude token limits across all plans
|
|
13,500 Likes
|
|
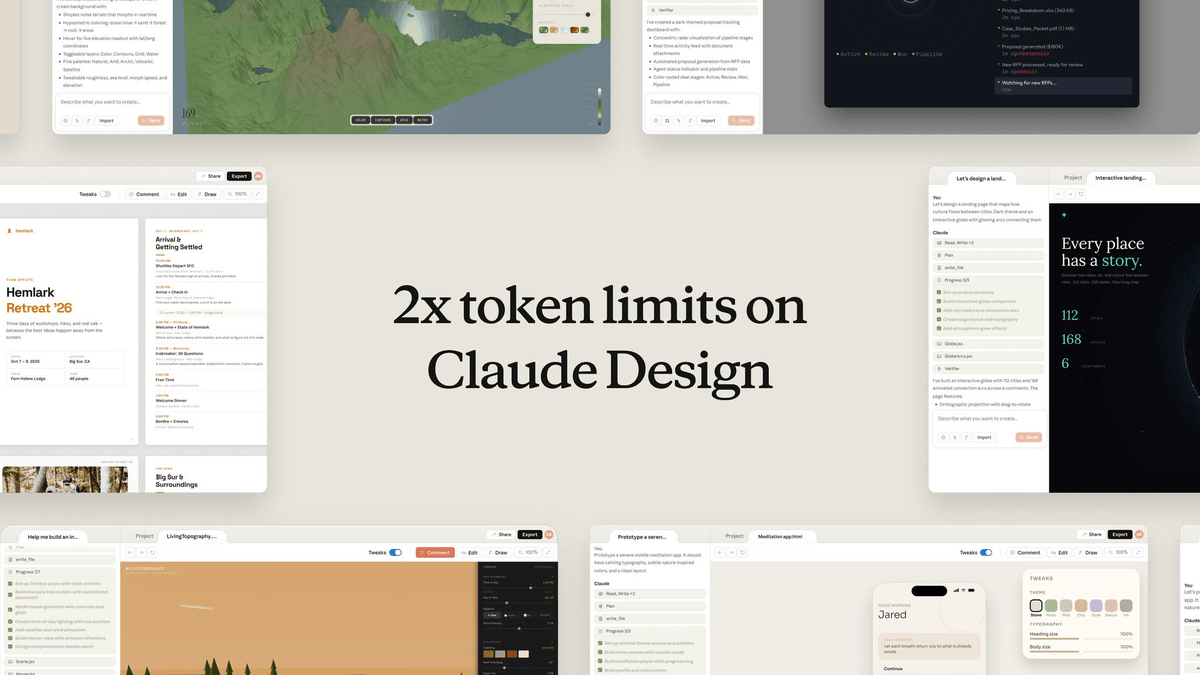
You know that feeling when Claude cuts you off mid-project? That just got a lot less common. Anthropic doubled token limits across every paid plan for Claude Design, and it is live now. Tokens are basically Claude's working memory. The more you have, the longer and more complex your conversations, code, and projects can be before Claude forgets what happened earlier. Doubling that means you can go much deeper without hitting a wall. Here is what actually changes for you: - Longer sessions without context loss mid-workflow
- Feed in bigger codebases, longer docs, or richer prompts in one go
- Peak-hour limits removed for Pro and Max accounts
- API rate limits also jumped, with Tier 1 seeing a 1500% increase in input tokens per minute
This is powered by Anthropic's new deal with SpaceX, giving them access to 220,000+ Nvidia GPUs. More compute, more room for you to build.
|
|
|
|
Presented by Kepler
|
|
Building deterministic infrastructure for AI
|
|
Past 200k tokens, sourcing discipline erodes. Bigger context windows don’t fix sourced reasoning. They break it sooner. Determinism is the hard part, not selection. 50+ years of Palantir experience, 6 engineers strong, backed by founders of OpenAI, Meta AI, and dbt. Hiring Founding Engineers in NYC.
|
|
|
|
Top News
|
|
|
|
Nous Research ships Hermes Agent v0.14.0 in major foundation release
|
|
4,644 Likes
|
|
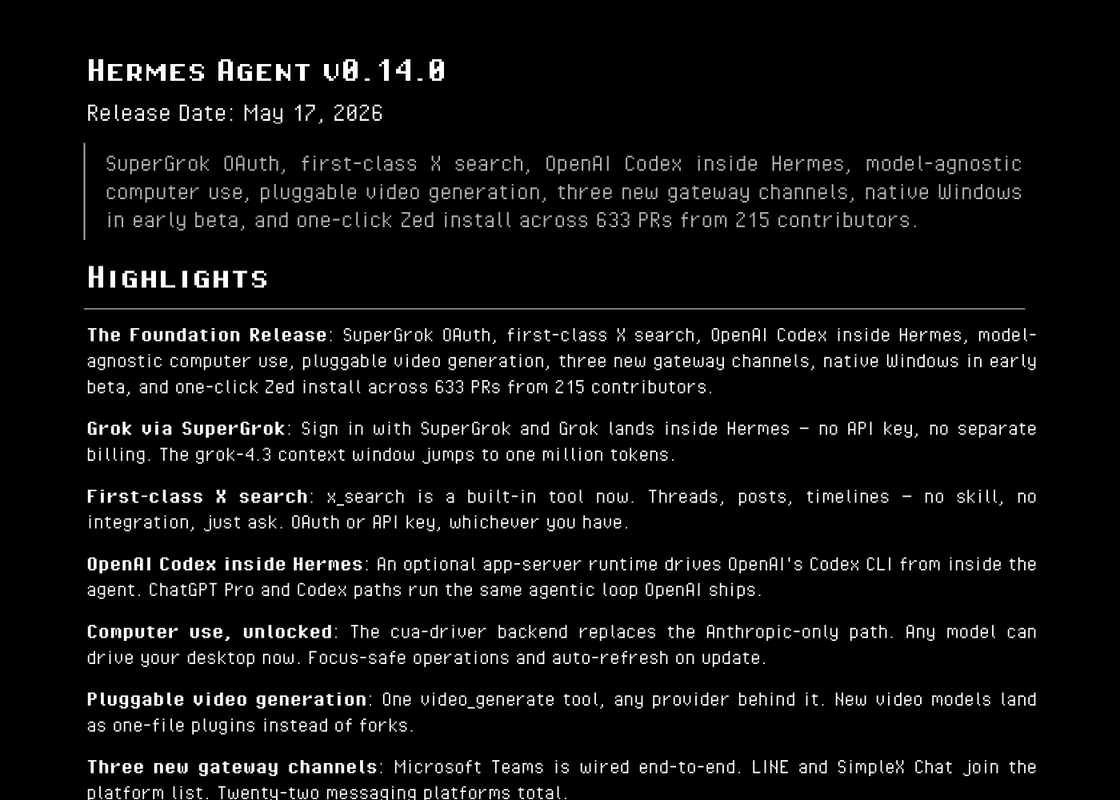
Hermes Agent just dropped v0.14.0, and this one is about fixing the fundamentals. It installs and runs anywhere, ships with the things you actually want, and stops shipping the things you don't. The biggest unlock: a new OpenAI-compatible local proxy turns any OAuth-authed provider like Claude Pro, ChatGPT Pro, or SuperGrok into an endpoint that Codex, Aider, Cline, and Continue can hit. No more paying twice for the same model as a subscription and again as API credits. Here's what else landed: - xAI Grok arrives via SuperGrok OAuth, with grok-4.3 bumped to a 1M token context window.
- LSP diagnostics now run on every file write, catching type errors, undefined symbols, and missing imports immediately.
- /handoff now transfers your full session live, every message and tool call, to a different model without losing context.
- LINE and SimpleX Chat join the platform list, bringing Hermes to 22 messaging platforms total.
To update, just run hermes update.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 250,000+ AI developers?
|
|
|
|
|
