| Hey, | Welcome to AlphaSignal – the most read newsletter by AI developers.
We bring you the top 1% of news, papers, models, and repos, all summarized to keep you updated on the latest in AI. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 6 min 06 sec | 🎖️ Top News
⚡️ Trending Signals
📝 Top Papers
Gemma 3 enhances multimodal, long-context, and multilingual capabilities, outperforming previous models in various benchmarks.
VACE unifies video creation and editing tasks, enabling flexible, efficient, and creative video synthesis.
YOLOE enhances real-time object detection with multiple prompt mechanisms, achieving high efficiency and performance.
🧠 Python Tip |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
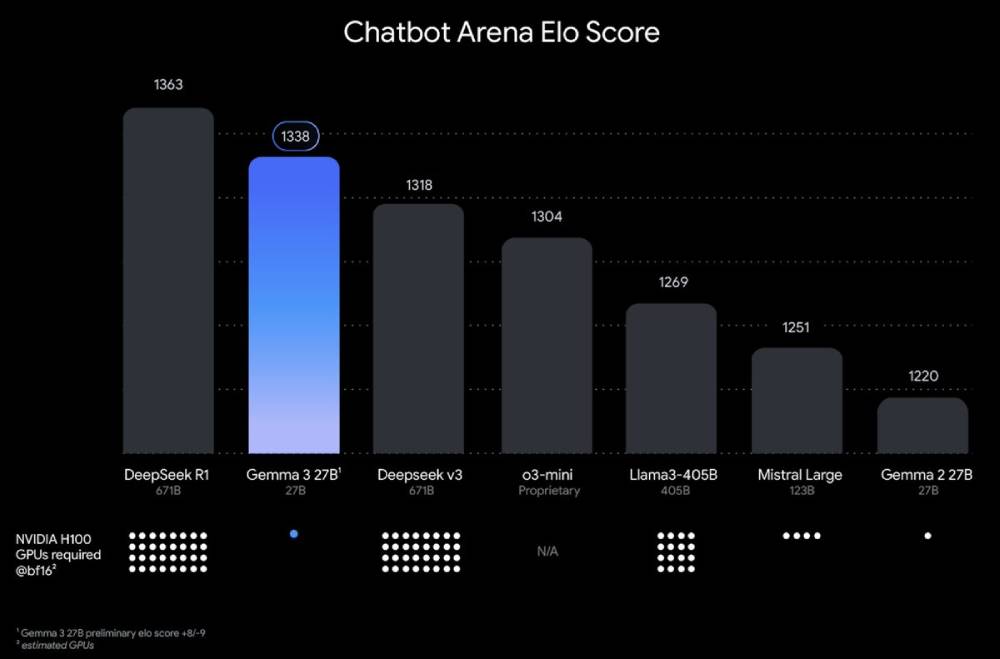
| LLM | Google unveils Gemma 3, an open-weight model family, ranking #2 on Elo score, just behind DeepSeek-R1
| ⇧ 23,482 Likes |
| What's New |
Google introduces Gemma 3, a new open-weight model family ranging from 1B to 27B parameters. The 27B model ranks second on LMArena, just behind DeepSeek-R1, making it one of the strongest open models available.
Key Features Gemma 3 introduces multimodal support, long-context handling, and optimized task performance.
- Supports 128K token context window for long-form processing.
- Multimodal with text, image, and video input using a SigLIP-based vision encoder.
- Understands 140+ languages with an improved tokenizer.
- Handles image-text interleaving, improving captioning and object recognition.
- Generates structured outputs in JSON, XML, and markdown formats.
Performance Benchmarks
Gemma 3-27B ranks among the top open-weight models in multiple benchmarks. - LMArena score: 1338, second only to DeepSeek-R1.
- MMLU: 82.3, outperforming previous Gemma models.
- GSM8K (math reasoning): 88.4, close to LLaMA 3-70B, despite having only 27B parameters.
- HumanEval (code generation): 67.1, ahead of Mixtral and Yi models.
Model Sizes Gemma 3 comes in four sizes:
- 1B, 4B, 12B, and 27B parameters for different deployment needs.
- 2T, 4T, 12T, and 14T training tokens, depending on model size.
- New tokenizer improves multilingual support for 140+ languages.
- JAX framework and Google TPUs were used for training.
RL
Gemma 3 uses reinforcement learning techniques to improve task performance.
- RLMF (Machine Feedback): Enhances mathematical reasoning.
- RLEF (Execution Feedback): Improves coding accuracy.
- RLHF (Human Feedback): Aligns responses with human preferences.
Availability and Access Gemma 3 is available on multiple platforms with open-weight access for research and development. - Download model weights from Hugging Face and Kaggle.
- Run inference on Google AI Studio with minimal setup.
- Deploy using Vertex AI, Cloud TPU, and Cloud GPU.
- Fine-tune with Hugging Face Transformers, JAX, MaxText, LiteRT, and llama.cpp.
- Supports Ollama for local execution.
Community Feedback
Chubby
"This is huge. It shows how good small models have become."
George
"Gemma 3! The improvements in language understanding and multimodal capabilities are impressive. Looking forward to seeing how it enhances user experiences across platforms."
Teortaxes
"Mildly impressed by Gemma 3 report (claims, not content). Basically Gemini 1.5 Flash with stronger reasoning and Noam architecture. Even sloptimized 1338 Elo is impressive for 27B. Some lessons in optimization to learn. I expect it will feel very polished in vibe checks" | |
| Try now
|
|
|
|
TRENDING SIGNALS
| AI Search |
|
⇧ 1,839 Likes | |
Image Generation |
|
⇧ 2,639 Likes | |
AI Safety |
|
⇧ 6,028 Likes | |
Diffusion Models |
|
⇧ 2,538 Likes | |
API Tool |
|
⇧ 538 Like | | |
|
|
|
|
TOP PAPERS
| Foundational Models |
| ⇧ 23,482 Likes |
Problem
Gemma 3 addresses the challenge of handling long-context memory issues, particularly the KV-cache memory explosion during inference. The goal is to enhance performance across math, chat, instruction-following, and multilingual tasks while improving multimodal capabilities.
Solution
Gemma 3 introduces a SigLIP vision encoder for image processing, extends context size to 128K tokens, and optimizes memory usage by interleaving local and global attention layers. It also incorporates a novel post-training approach to enhance performance in math, reasoning, coding, and multilingual abilities. Knowledge distillation is used to improve efficiency.
Results
Gemma 3 outperforms previous models, with the 4B instruction-tuned version competing with the 27B Gemma 2 model. The 27B Gemma 3 version rivals Gemini-1.5-Pro across benchmarks. All models are released to the community for further development.
| | Video Generation |
| ⇧ 2,475 Likes |
Problem
Unifying video generation and editing tasks has been challenging due to the need for consistency across temporal and spatial dynamics.
Solution
VACE combines multiple video tasks—reference-to-video generation, video-to-video editing, and masked editing—into one framework. It uses the Video Condition Unit (VCU) to organize inputs and the Context Adapter to adapt task concepts for flexible processing. Built on Diffusion Transformers, VACE handles long video sequences and diverse input modalities.
Results
VACE performs on par with specialized models, reducing deployment costs and enhancing creativity through flexible task combinations, offering a versatile solution for video content creation and editing.
| | Object Detection |
|
⇧ 1,392 Likes | Problem
Traditional object detection models like YOLO are limited by predefined categories, affecting adaptability in open scenarios.
Solution
YOLOE integrates detection and segmentation across text, visual, and prompt-free mechanisms. It uses Re-parameterizable Region-Text Alignment (RepRTA) for text prompts, Semantic-Activated Visual Prompt Encoder (SAVPE) for visual prompts, and Lazy Region-Prompt Contrast (LRPC) for prompt-free detection, all within one efficient model.
Results
YOLOE outperforms YOLO-Worldv2-S by 3.5 AP with 3x less training cost and 1.4x faster inference. On COCO, it surpasses YOLOv8 by 0.6 APb with 4x less training time, setting a strong baseline for open-prompt vision tasks.
| | |
| |
|
|
PYTHON TIP
| Getting Started with OpenAI Agents SDK | The OpenAI Agents SDK is a lightweight yet powerful framework for building multi-agent workflows.
To get started with OpenAI's Agents SDK, create a Python virtual environment and install the openai-agents package.
|
pip install openai-agents
| Define an agent with instructions and run it using Runner: |
from agents import Agent, Runner

agent = Agent(name="Assistant", instructions=
                      "You are a helpful assistant")

result = Runner.run_sync(agent,
                    "Write a haiku about recursion in programming.")

print(result.final_output)
| In this example, the agent responds with a haiku about recursion. Use this SDK for automating workflows, building conversational agents, or integrating intelligent systems into your applications. It simplifies interaction with OpenAI’s models, enabling quick development of agentic tools.
|
| Github repo
|
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
