Today's theme is simple: memory and infrastructure are the new moat.
OpenAI built its own inference chip in nine months using its own AI. Anthropic gave Claude unified memory across chat and agents. Prime Intellect open-sourced a harness that lets models reuse context across runs. Three different bets, same conviction: the next edge isn't the model, it's the stack around it.
We're watching the industry quietly shift from "who has the best weights" to "who controls the full loop."
|
|
In Partnership with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
OpenAI's custom inference chip promises faster ChatGPT and lower costs
|
|
11,744 Likes
|
|
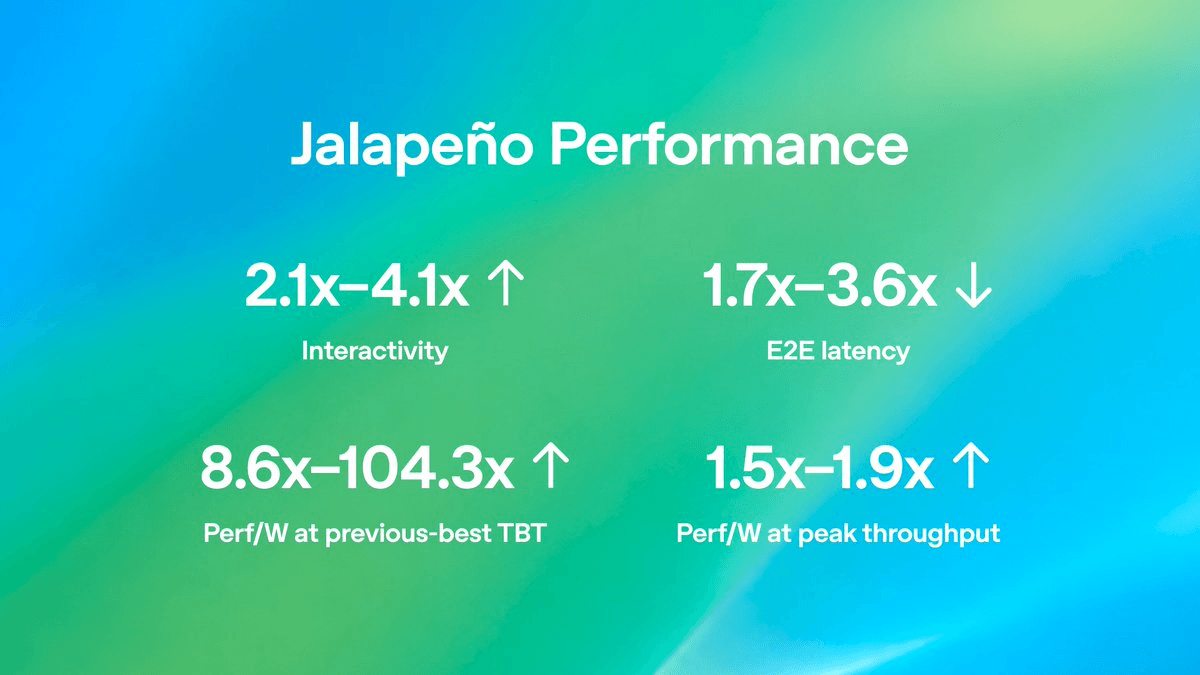
OpenAI just showed off real benchmark results for Jalapeño, its first custom chip built specifically to run AI models, not train them. Think of inference as the moment ChatGPT actually writes your reply. That is what this chip is built for. It was co-built with Broadcom and went from design to finished chip in just nine months, partly because OpenAI used its own AI models to help design it. Here is what makes it interesting: - Targets ~50% lower cost per response compared to Nvidia's current best chips
- Handles both speed and volume without trading one for the other, something most chips struggle with
- Keeps the model's short-term memory close to the processor, so less data travels around and replies come back faster
- A Gen 2 is already deep in development, Gen 3 is taking shape
For you, this means faster Codex responses, snappier ChatGPT, and fewer slowdowns as usage grows. You cannot rent or buy this chip. It runs OpenAI's infrastructure only.
|
|
|
|
Presented by Datalab
|
|
Most PDF pages don't need a vision model
|
|
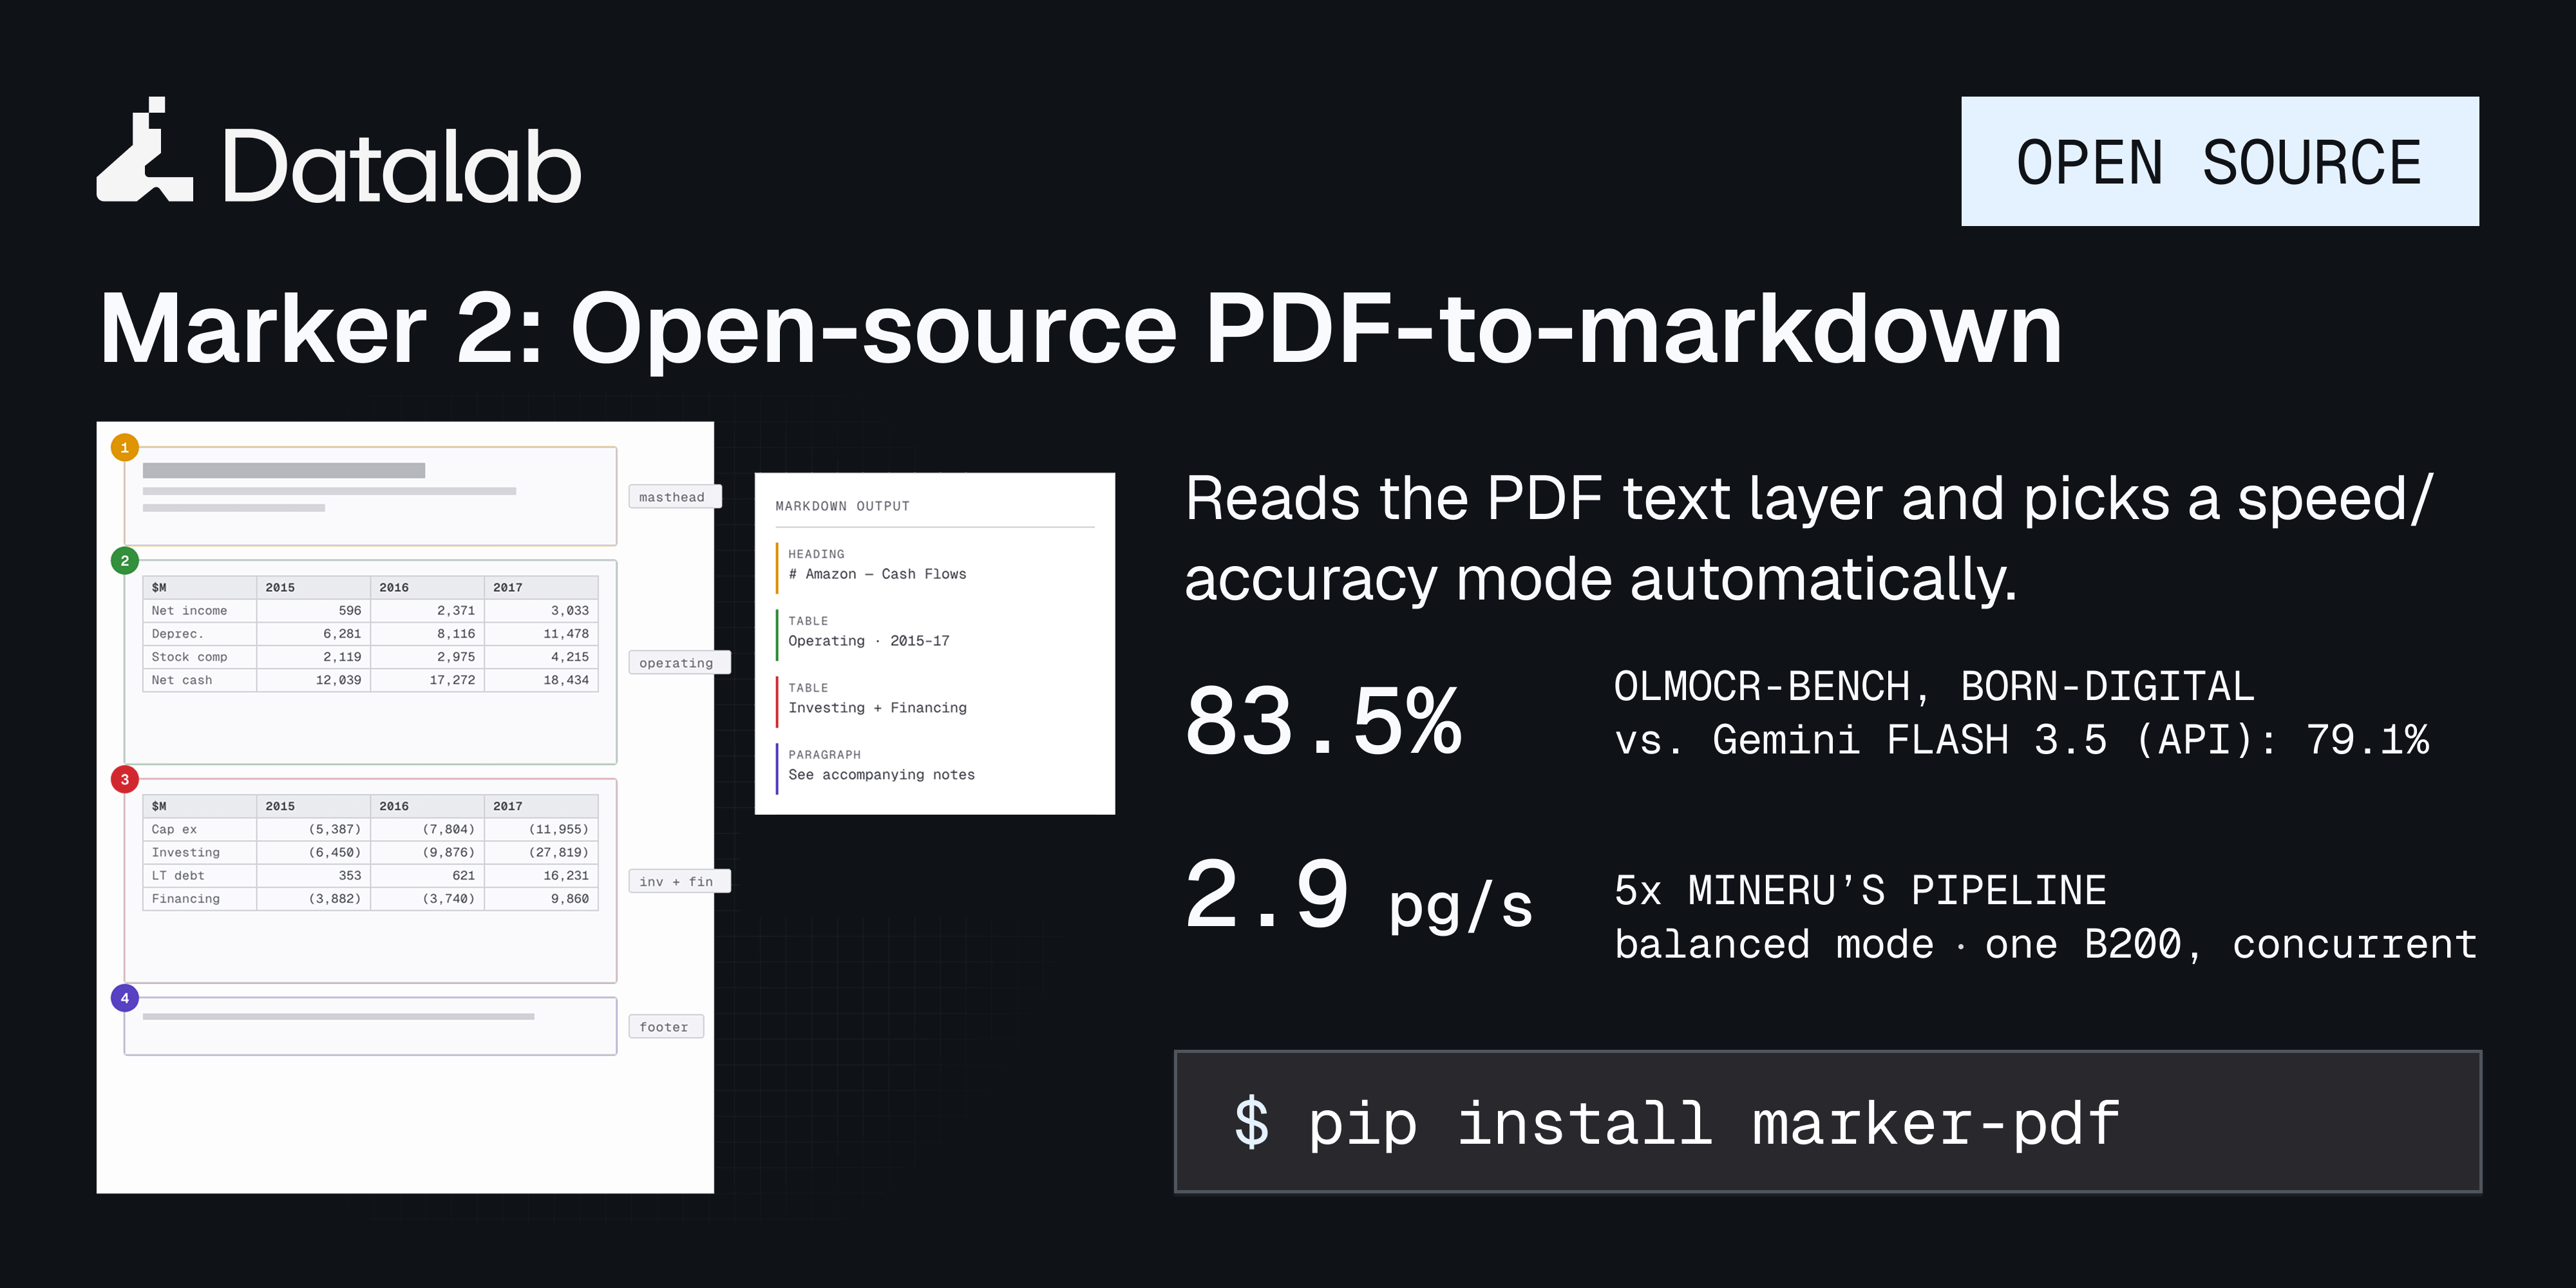
Datalab's Marker 2 turns any PDF, image, DOCX, and PPTX into clean markdown. It reads the PDF text layer and calls the vision model only where the page actually needs one. - 83.5 on born-digital PDFs — above Gemini Flash 3.5's 79.1, with no per-page API call
- 76.0 overall at 2.9 pages/sec — 5× MinerU pipeline's throughput, at higher accuracy
- Runs on CPU — 42ms/page, GPU optional. New in v2
- Apache-2.0 code, fully local — no key, no metering
- 39,000+ GitHub stars
|
|
|
|
Top News
|
|
|
|
Anthropic gives Claude persistent memory across all chats by default
|
|
7,347 Likes
|
|
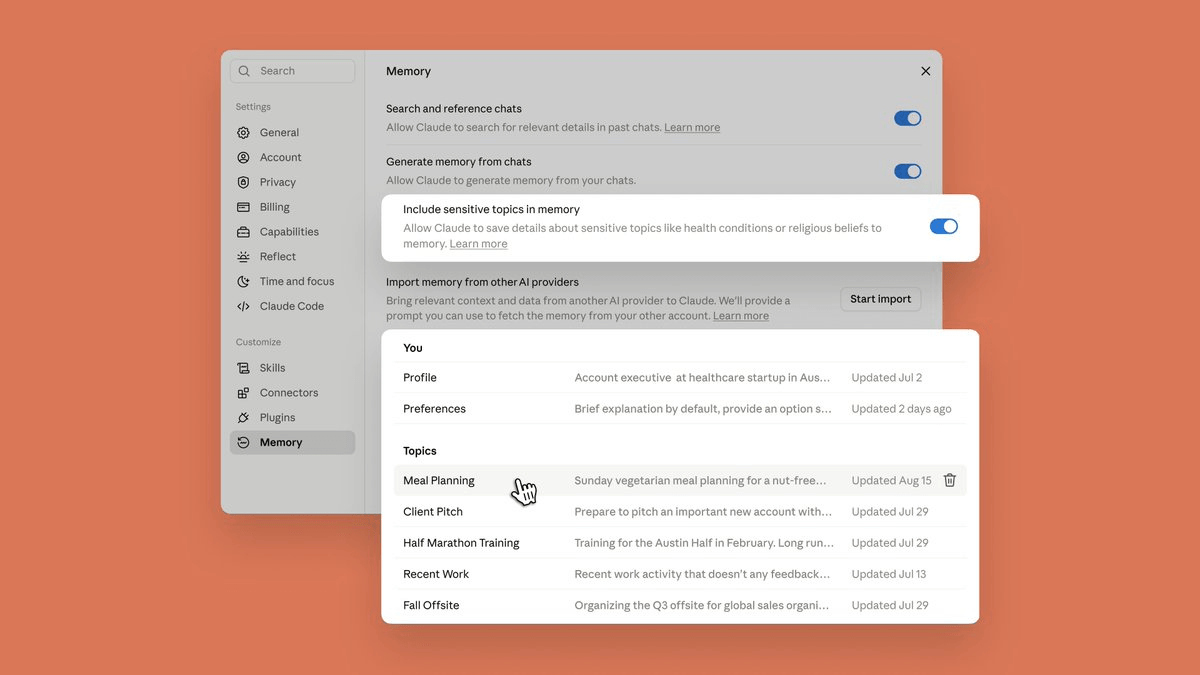
You know that annoying thing where you explain your whole project setup to Claude in chat, then switch to Claude Cowork (the AI agent that handles multi-step tasks like building docs or running code), and it has zero clue what you just said? That's fixed. Claude now shares one unified memory across both chat and Cowork. Context you built up in chat is instantly available when Cowork runs a task, and vice versa. No more rebriefing. Here's what you can actually do with it: - Say "remember this" mid-chat to save something specific
- Go to Settings > Memory to read, edit, or delete anything Claude has saved
- Enable sensitive topics (health, beliefs) manually if you want that context saved too
- Memory updates live during conversations, not just after they end
It's on by default on Free, Pro, and Max plans. You're in full control of what stays.
|
|
|
|
Presented by Datadog
|
|
Stop Guessing What OpenAI Costs You
|
|
Every OpenAI request adds up in spend, latency, and errors you can't see.
This cheatsheet shows you how to track cost estimates, sample prompts and completions, catch errors, and monitor latency across Python, Node.js, and PHP with Datadog APM.
One page, all the metrics that matter.
|
|
|
|
Top News
|
|
|
|
Perplexity ships fully local AI agent that runs on NVIDIA DGX Spark
|
|
3,840 Likes
|
|
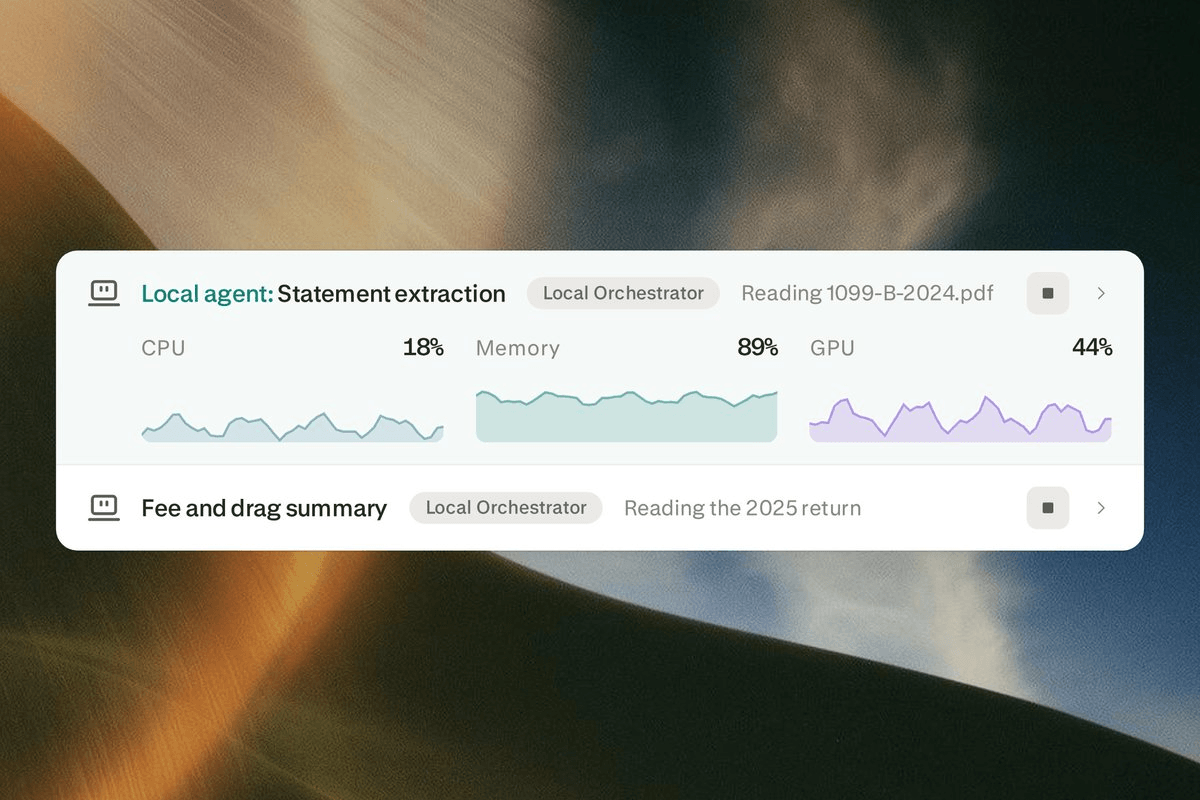
Perplexity just shipped Portable Computer, and the core idea is simple: your AI agent runs entirely on your own machine. No cloud. No data leaving your desk. Until now, every Perplexity agent ran on remote servers. Portable Computer flips that. The orchestrator (the brain that plans tasks), the subagent (the part that executes them), and the full tool harness all run locally on your hardware. Here is what that unlocks: - Zero token costs for local tasks. Long loops, big file analysis, repo-scale work, all free.
- Your sensitive files never leave your device. PII is flagged automatically.
- Cloud escalation is opt-in, per step, with your approval each time.
- Connects to Google Drive, Gmail, GitHub, and Slack.
It runs on the NVIDIA DGX Spark with either PPLX 27B or Qwen 3.8 27B. Setup is one click inside the Perplexity app. Available now for Pro and Max subscribers on Linux.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 300,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 300,000+ AI developers?
|
|
|
|
|
