| Hey, | Welcome to today's edition of AlphaSignal, a newsletter for developers by developers.
We identify and summarize the top 1% news, papers, models, and repos in the AI industry. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 5 min 41 sec | 🎖️ Top News
📌 Ori
⚡️ Trending Signals
Google made Gemini 1.5 Flash 3x faster, and also made a 2x increase in output tokens per second.
Open-Sourced tool with Github code went viral, that analyze video data of customer behavior in retail space.
OpenAI's o1-preview model ranks 1st officially on Chatbot Arena, across the board, especially in Math, Hard Prompts, and Coding.
Cognition's Devin (the world's first AI software engineer) significantly improves its code generation capability by using OpenAI's new 01 model.
New Qwen2.5-72B-Instruct is made available now on LMSys Chatbot Arena, for everybody to experiment and submit evaluations.
📌 Guidde
🛠️ Trending Repos
AutoGPT: create and run intelligent agents.
Agent Zero: General-purpose agentic assistant.
Taipy: Turns Data and AI algorithms into production-ready web app
🧠 Async Tensor Parallelism in PyTorch
|
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| Mistral | Mistral AI launched a new free tier to let developers fine-tune and build test apps with reduced API costs |
⇧ 989 Likes |
 |
What's New | Mistral AI has introduced a free tier and reduced pricing for its language models, aiming to increase accessibility for developers and researchers. Mistral also released an upgraded small model and integrated vision capabilities into its chat platform.
Key Points
La Plateforme now offers a free tier for experimentation and prototyping. Users can deploy models on various cloud providers or their own infrastructure, with options for data isolation and zero-retention. The platform allows seamless transition to commercial tiers with higher rate limits. Pricing for Mistral AI models has been significantly reduced: Mistral Nemo: $0.15/M tokens (50% reduction) Mistral Small & Codestral: $0.2/M input tokens, $0.6/M output tokens (80% reduction) Mistral Large 2: $2/M input tokens, $6/M output tokens (33% reduction) Mistral Small v24.09, a 22-billion parameter model, has been released under the Mistral Research License. The updated pricing will also reflect on our cloud platform partner offerings (Azure AI Studio, Amazon Bedrock, Google Vertex AI). This upgrade offers improved human alignment, reasoning capabilities, and code generation compared to its predecessor. Reasoning Benchmark: The new Mistral v24.09 shows improvements in both GSM8K (8-shot) and MATH (0-shot) tasks compared to v24.02, with particularly significant gains in MATH performance. Pixtral 12B updates
Pixtral 12B, an Apache 2.0 licensed vision model, is now freely available on le Chat. It can process images of any size without compromising text performance, supporting tasks such as image analysis, captioning, and understanding of visual content in personal or enterprise knowledge files. This allows for visual understanding capabilities without the need to upload sensitive information to third-party providers. Overall, this price update makes Mistral Large 2 the most cost-efficient frontier model, make our smaller models extremely cost efficient. |
|
|
Read more
|
|
|
|
| Build, deploy and scale on Ori Serverless Kubernetes | Run Kubernetes without the overhead. Scale your AI projects effortlessly with their just-released platform. Pay only for what you use, cutting GPU costs as you grow.
Autoscaling: Adjust resources automatically based on demand High-Performance GPUs: Access NVIDIA H100, L40S, or L4 GPUs - full or fractional Instant Deployment: Spin up a cluster in under a minute, no approvals needed Streamlined MLOps: Full control plane benefits, serverless simplicity Sign up to Ori and get started with $100 in free credit! |
|
Sign up
| partner with us |
|
|
|
TRENDING SIGNALS
| Google AI |
|
⇧ 1,500 Likes | |
Computer Vision |
|
⇧ 1,300 Likes | |
OpenAI |
|
⇧ 433 Likes | |
AI Code Generation |
|
⇧ 2,600 Likes | |
LLM |
|
⇧ 536 Likes | | |
|
|
|
|
|
Guidde - Create how-to video guides fast and easy with AI
| Guidde is a free GPT-powered tool that creates AI-generated, visual, and video documentation quickly and efficiently. With a simple click using its browser extension, Guidde captures tasks, generating step-by-step guides with visuals, voiceovers, and calls to action, transforming tedious documentation into engaging content. |
Check out Guidde ↗️ |
|
|
|
| TRENDING REPOS |
AI Agent | |
☆ 167,568 Stars |
Helps you build, test, and deploy AI agents using a flowchart-style interface. You can create custom blocks, run agents on a backend server, and evaluate their performance with a built-in benchmark. It supports the agent protocol for standardized communication. The toolkit includes a user-friendly frontend and CLI for easy agent management. |
| Agents |
|
| ☆ 3,971 Stars |
Helps you build a customizable AI assistant that uses your computer as a tool. It runs LLMs to execute tasks, write code, and use the terminal. The system adapts through persistent memory and multi-agent cooperation. You can modify every prompt and tool for full control. It works with small models and streams output in real-time. |
| AI web app |
| ☆ 11,824 Stars |
Helps you build Python data and AI web apps without learning new languages. It combines UI generation and scenario management. You can create complex pipelines, filter datasets, and visualize results. It supports various data types and integrates with popular ML libraries. Taipy streamlines development from prototypes to production-ready applications. |
| |
| |
|
|
PYTORCH TIP
| Learn Tensor Parallelism from PyTorch team |
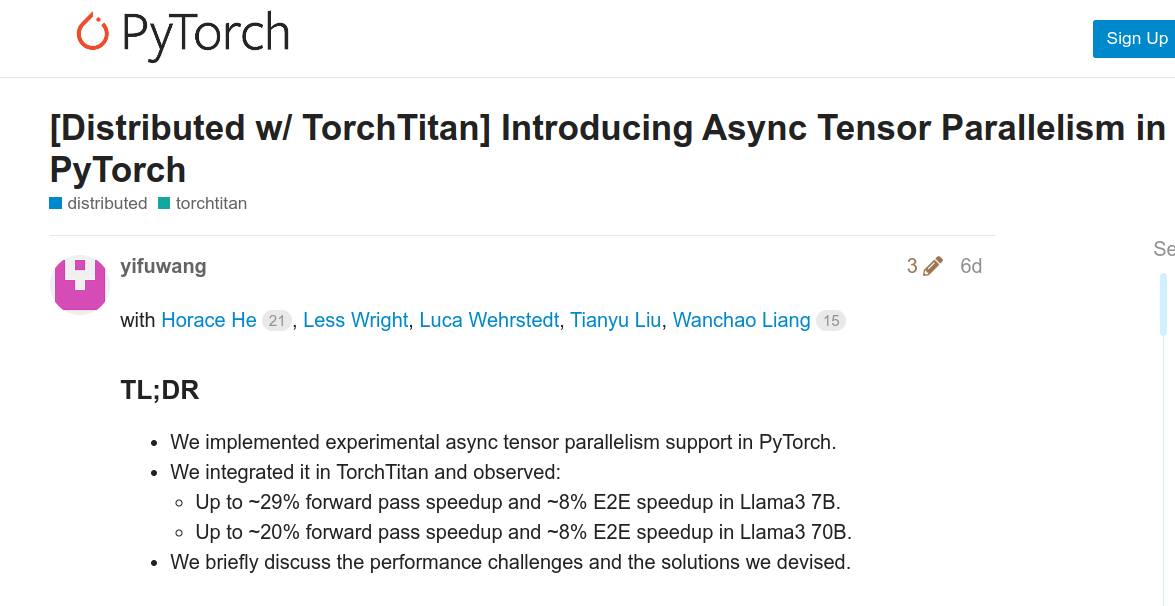 |
Tensor parallelism is central to all LLM workloads, from pretraining to inference, yet is hard to get right. This tutorial will helps you to implement it.
Performance
Llama3 70B:
Async-Tensor Parallelism concept
The feature automatically detects Tensor Parallel patterns and rewrites them into async-TP operations. Async-TP works best with large matrix multiplications. It's optimized for intra-node setups with NVSwitch. Decomposes dependent communication and computation operators Creates overlapping opportunities to hide communication latency Example: All-gather decomposed into send/recv, matmul divided into sub-matmuls Allows computing one sub-matmul while transferring data for the next Remember, async-TP is still experimental. It's available in the latest PyTorch nightly builds. You can use it with torch.compile or directly in eager mode.
|
|
Read more
|
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
|
Advertise
|
|
|
|
|
