Both Google and OpenAI dropped major models today, and the pricing is almost identical: $2 input / $10 output per 1M tokens. Coincidence? Probably not.
The real story is what these models are built to sustain. Gemini 4 Argon pushes output to 1M tokens. OpenAI bets on raw speed at 300 tokens/sec. Longer or faster, same destination: uninterrupted agentic work.
CLMs quietly prove the point: models managing their own memory beat human-designed strategies by 47%. The scaffolding era is ending.
|
|
In Partnership with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
Google DeepMind unveils Gemini 4 Argon with 1M token output for complex workflows
|
|
38,544 Likes
|
|
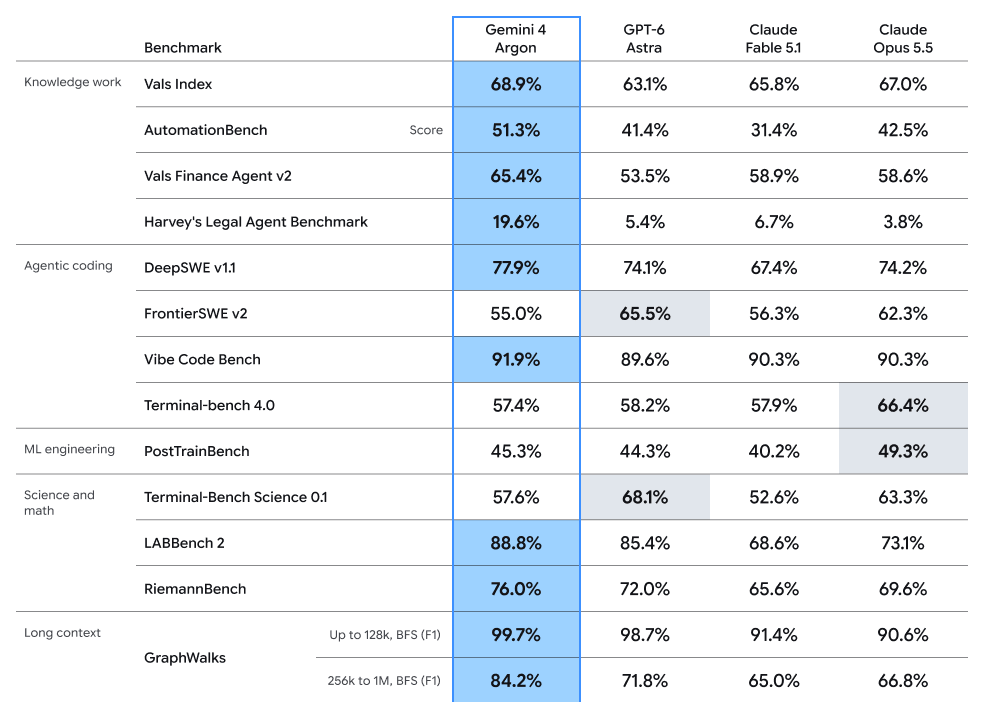
Google just dropped Gemini 4 Argon, its most powerful model yet. But here's the catch: you can't use it yet. Right now it's only available to vetted cybersecurity defenders through the Fairwind Program, a limited-access channel for governments and trusted partners. Broader access for everyone else is coming soon. So what makes it special? The biggest deal is the output limit. Previous Gemini models could write up to 64,000 tokens in one response. Argon pushes that to 1 million output tokens, meaning it can reason through massive, multi-step problems without stopping. Think full codebase migrations, long legal documents, or complex security audits in a single pass. Here's what it can do: - Autonomously find, validate, and patch critical software vulnerabilities without human help
- Handle real-world software engineering across 20 programming languages
- Work through legal, financial, and enterprise knowledge tasks end to end
Pricing starts at $2 per million input tokens and $10 per million output tokens. Sit tight for general access.
|
|
|
|
Presented by AgentField AI
|
|
CodeAF: #1 of ten coding harnesses on DeepSWE
|
|
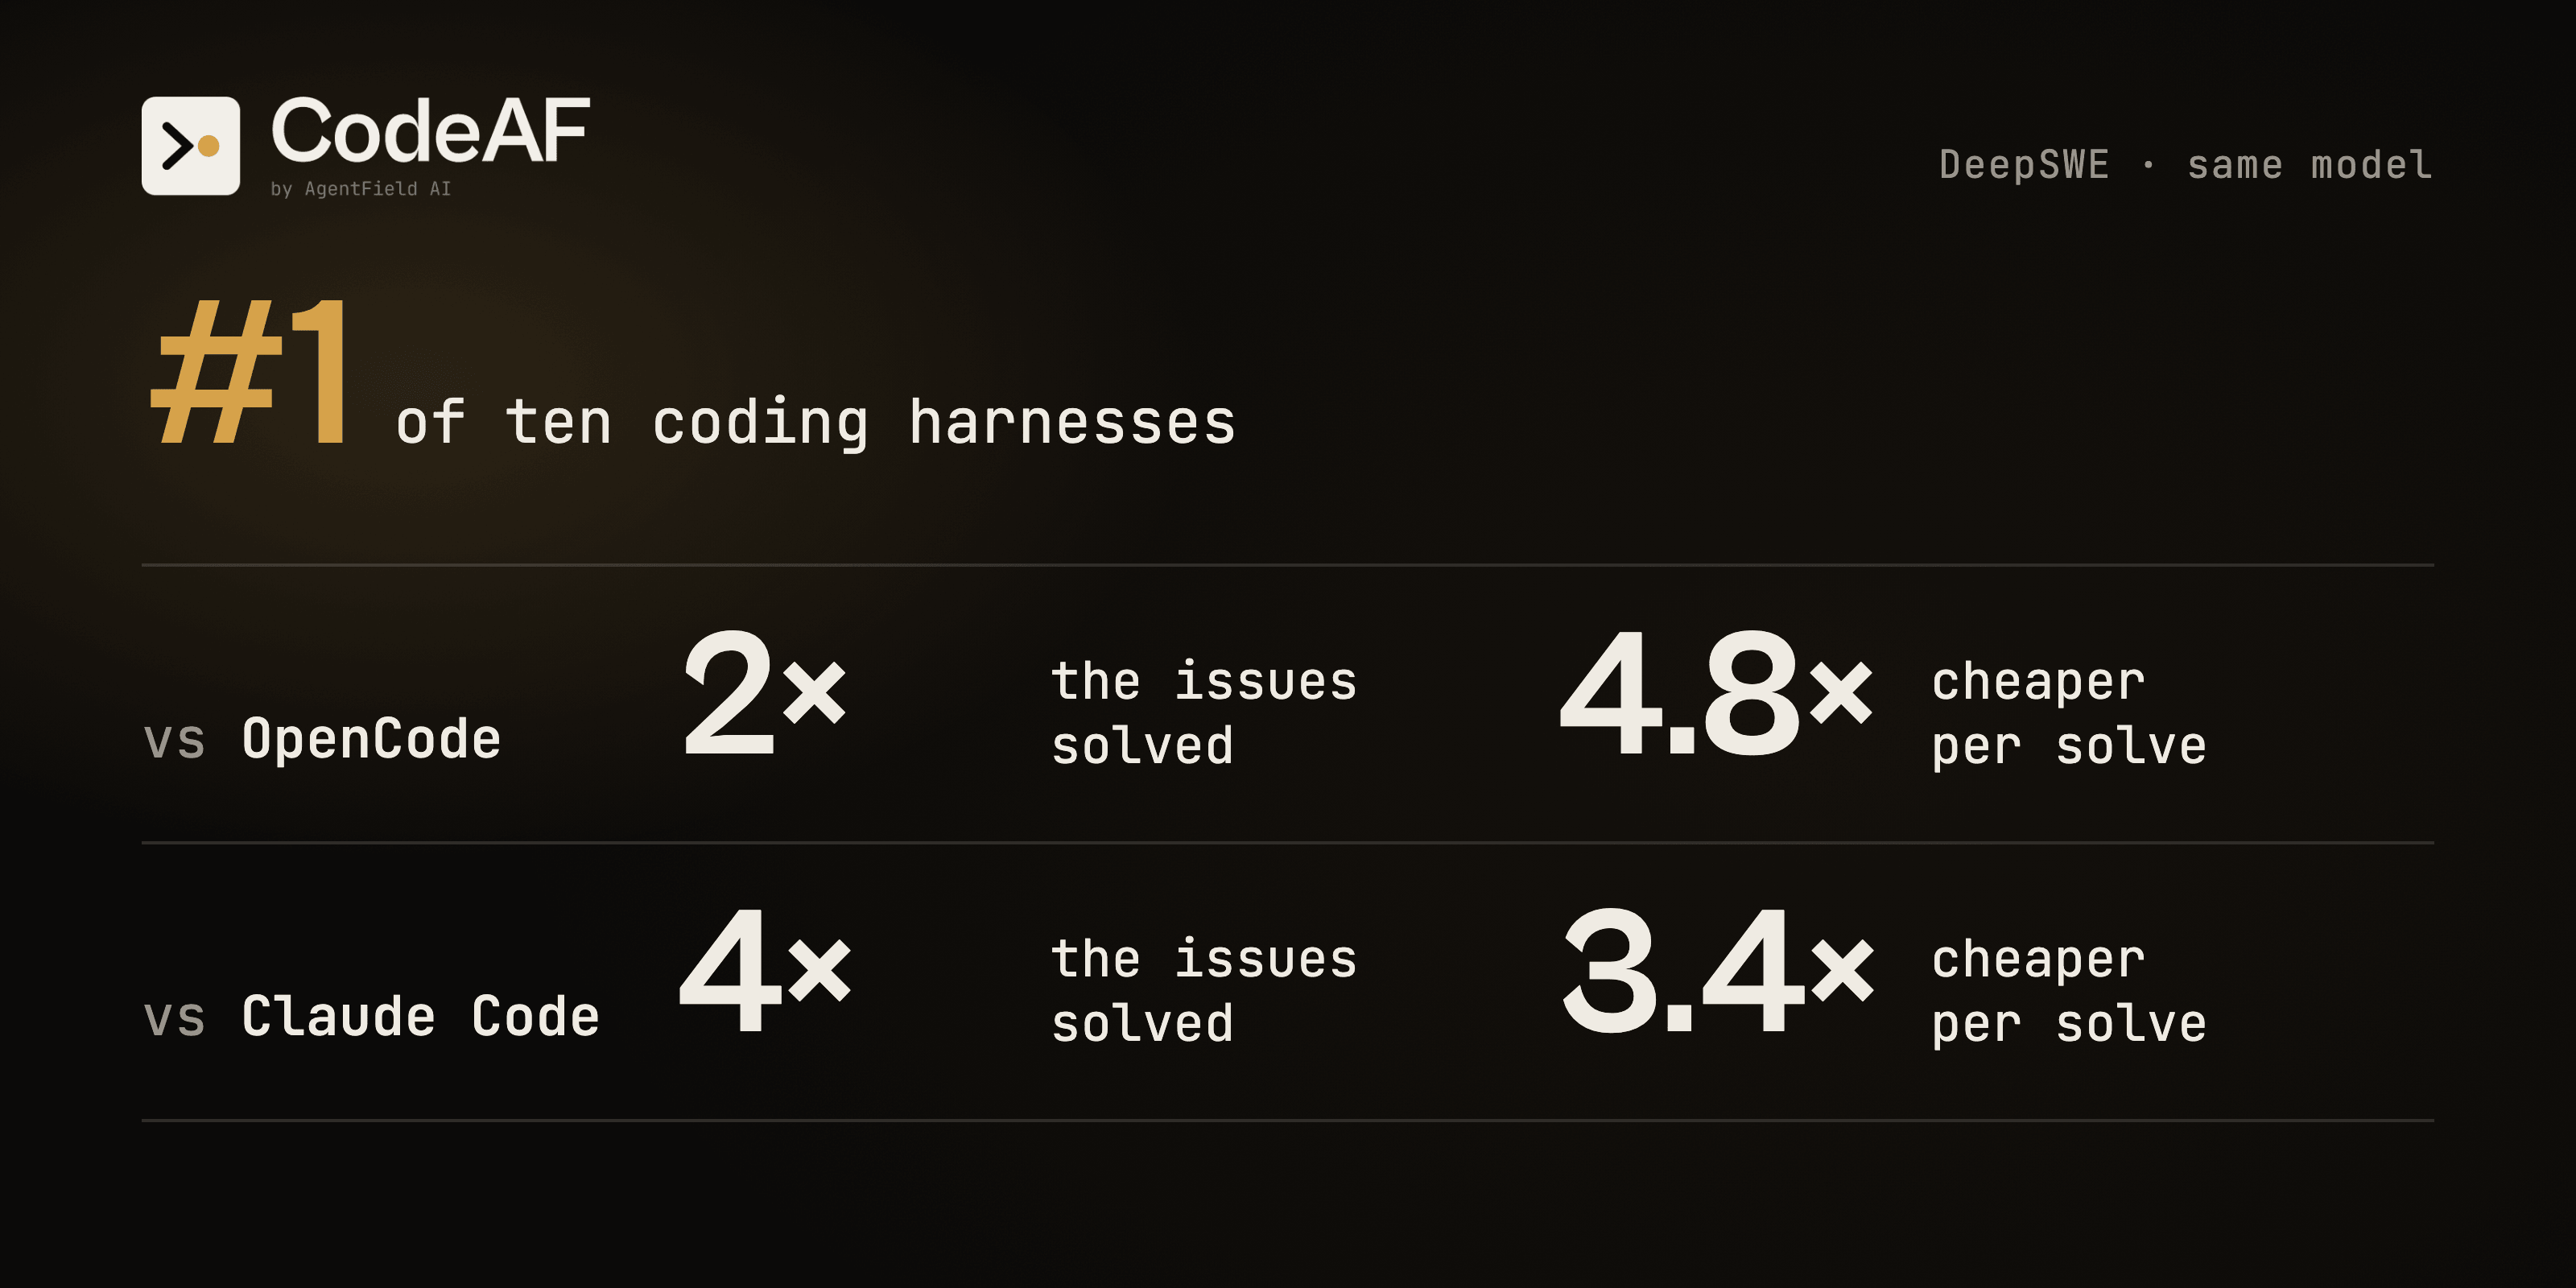
The harness is worth as much as the model. On DeepSWE, ten coding harnesses ran the same open model, DeepSeek V4 Flash, on 113 real GitHub issues graded by the official verifiers. CodeAF finished #1, ahead of Claude Code, Codex, OpenCode, Kilo and DeepSeek's own harness, and paid the least for every issue it solved: the others paid 1.9× to 26.6× more per solve. CodeAF is a new open-source coding harness built for open models, and it works with closed models too.
|
|
|
|
Top News
|
|
|
|
OpenAI launches Ultrafast tier with 8x faster GPT-6 and new GPT-6.1 Sol model
|
|
8,427 Likes
|
|
OpenAI just dropped two things worth knowing about: a new model and a new speed tier. GPT-6.1 Sol is the headline model. Think of it as Astra's smarter little sibling. It nearly matches GPT-6 Astra on agentic coding, computer use, and professional work at one-fifth of Astra's token prices. Call it via the API as gpt-6.1-sol. Then there is Ultrafast, a paid speed tier. Tokens are the chunks of text the model generates. Normally that feels slow when a user is waiting. Ultrafast hits up to 300 tokens per second, with 8x faster generation in Codex and 6x in the API. That unlocks real-time feeling apps that were too laggy before. To get Ultrafast in Codex and ChatGPT Work, you need the new Pro 500 plan. Pro 500 provides the highest included usage and is the only Pro tier that includes Astra Ultrafast. - GPT-6.1 Sol: $2 input / $10 output per 1M tokens
- Ultrafast Astra API: $60 input / $300 output per 1M tokens
- Pro 500: $500/month, 25x Plus usage, Ultrafast included
|
|
|
|
Presented by Origin Technology
|
|
Trace every AI agent action, prompt to outcome
|
|
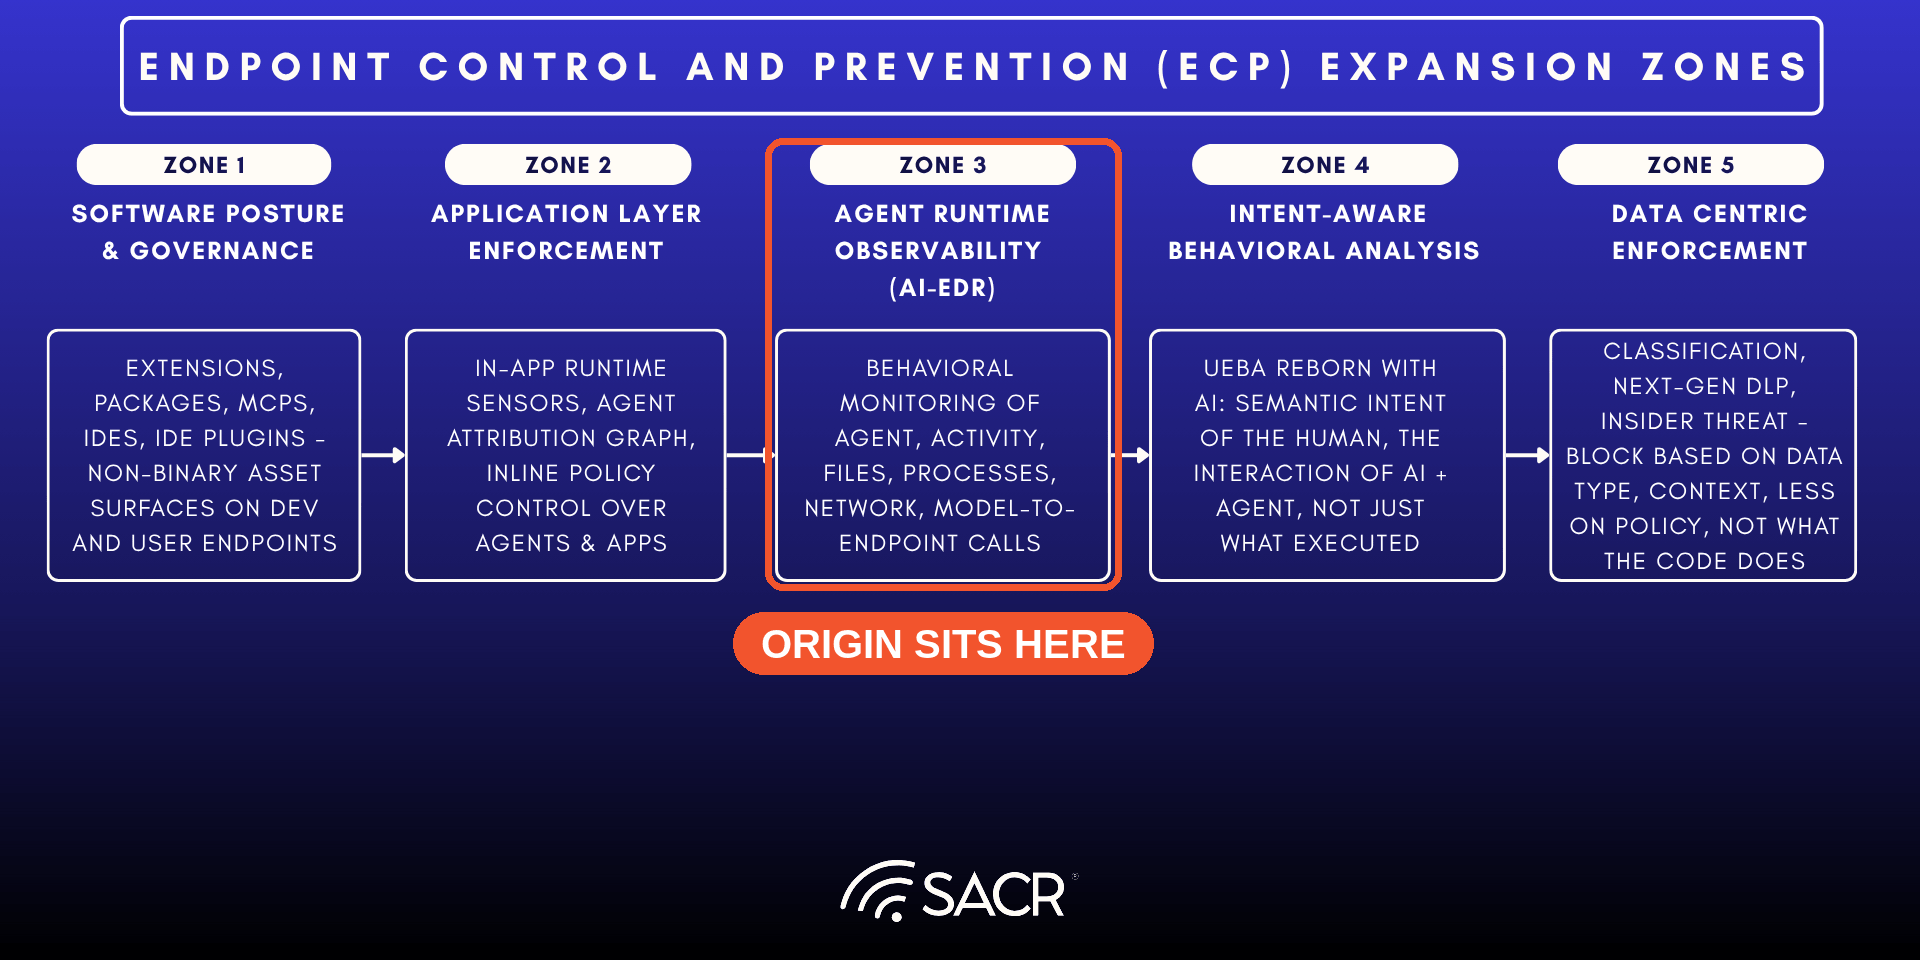
AI agents on your endpoints hold real credentials and never do a job the same way twice, so signatures miss them. SACR's Endpoint Control map puts Origin in Zone 3, agent runtime observability: a full trace from prompt to tool call to outcome, catching a leaked credential the moment it happens.
|
|
|
|
Top News
|
|
|
|
OpenAI ships major Codex CLI update with voice, parallel agents, and new UI
|
|
4,628 Likes
|
|
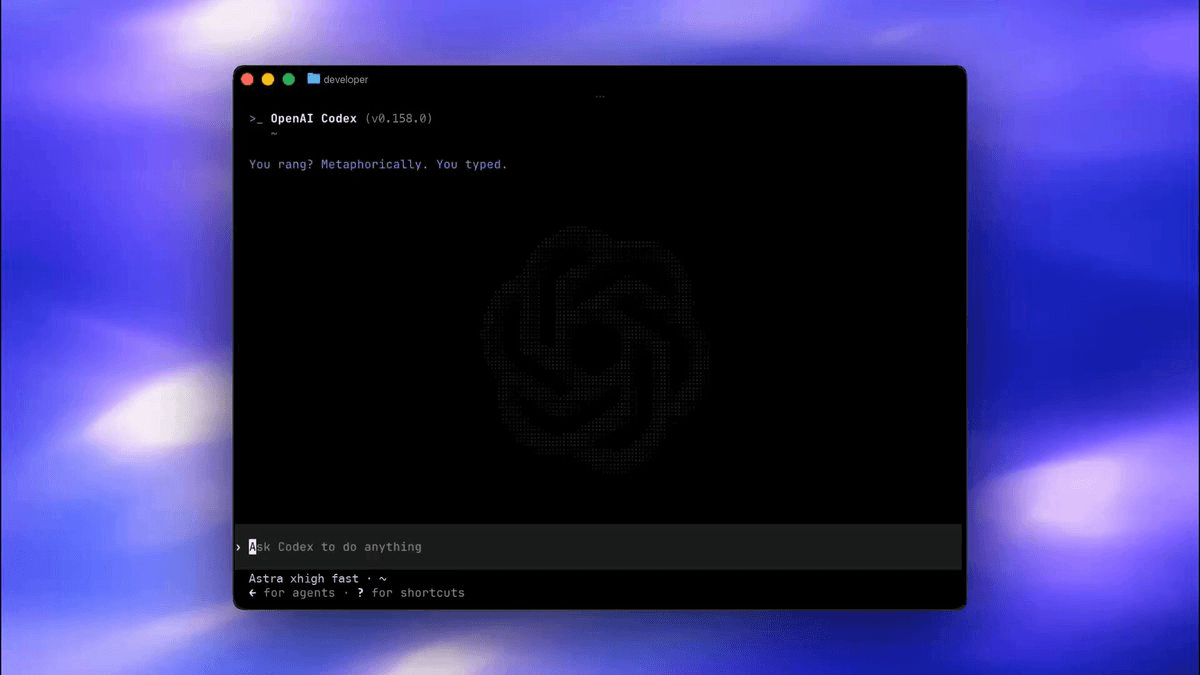
Codex CLI just got a serious upgrade, and if you live in the terminal, this one's for you. The whole interface is now full-screen with way better readability. Your input box stays pinned at the bottom, so no more scrolling up just to type your next message. Old history loads as you scroll back, no limits. The big new stuff: - /agents lets you see all running tasks, check progress, and jump between them
- /fork splits your current conversation into a separate branch with its own code checkout, so you can try a different approach without losing your original
- /voice lets you speak to Codex and hear it respond, right in the terminal
- /usage for analytics, /theme for custom looks, Mermaid diagrams and LaTeX rendered inline, collapsible diffs
This opens up real parallel workflows: run multiple agents, fork ideas, track everything, without leaving your terminal. To get it now: npm install -g @openai/codex@latest
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 300,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 300,000+ AI developers?
|
|
|
|
|
