|
Hey,
Your daily briefing is ready. You can finally take a break from the AI firehose.
Our algos spent the night splitting signal from noise and pulled the top news, models, papers, and repos.
Here’s the must-read:
|
|
Together with:
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer.
Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
Alibaba releases open-source Qwen3.5 Small series where 9B beats 120B-class models on reasoning benchmarks
|
|
16,274 Likes
|
|
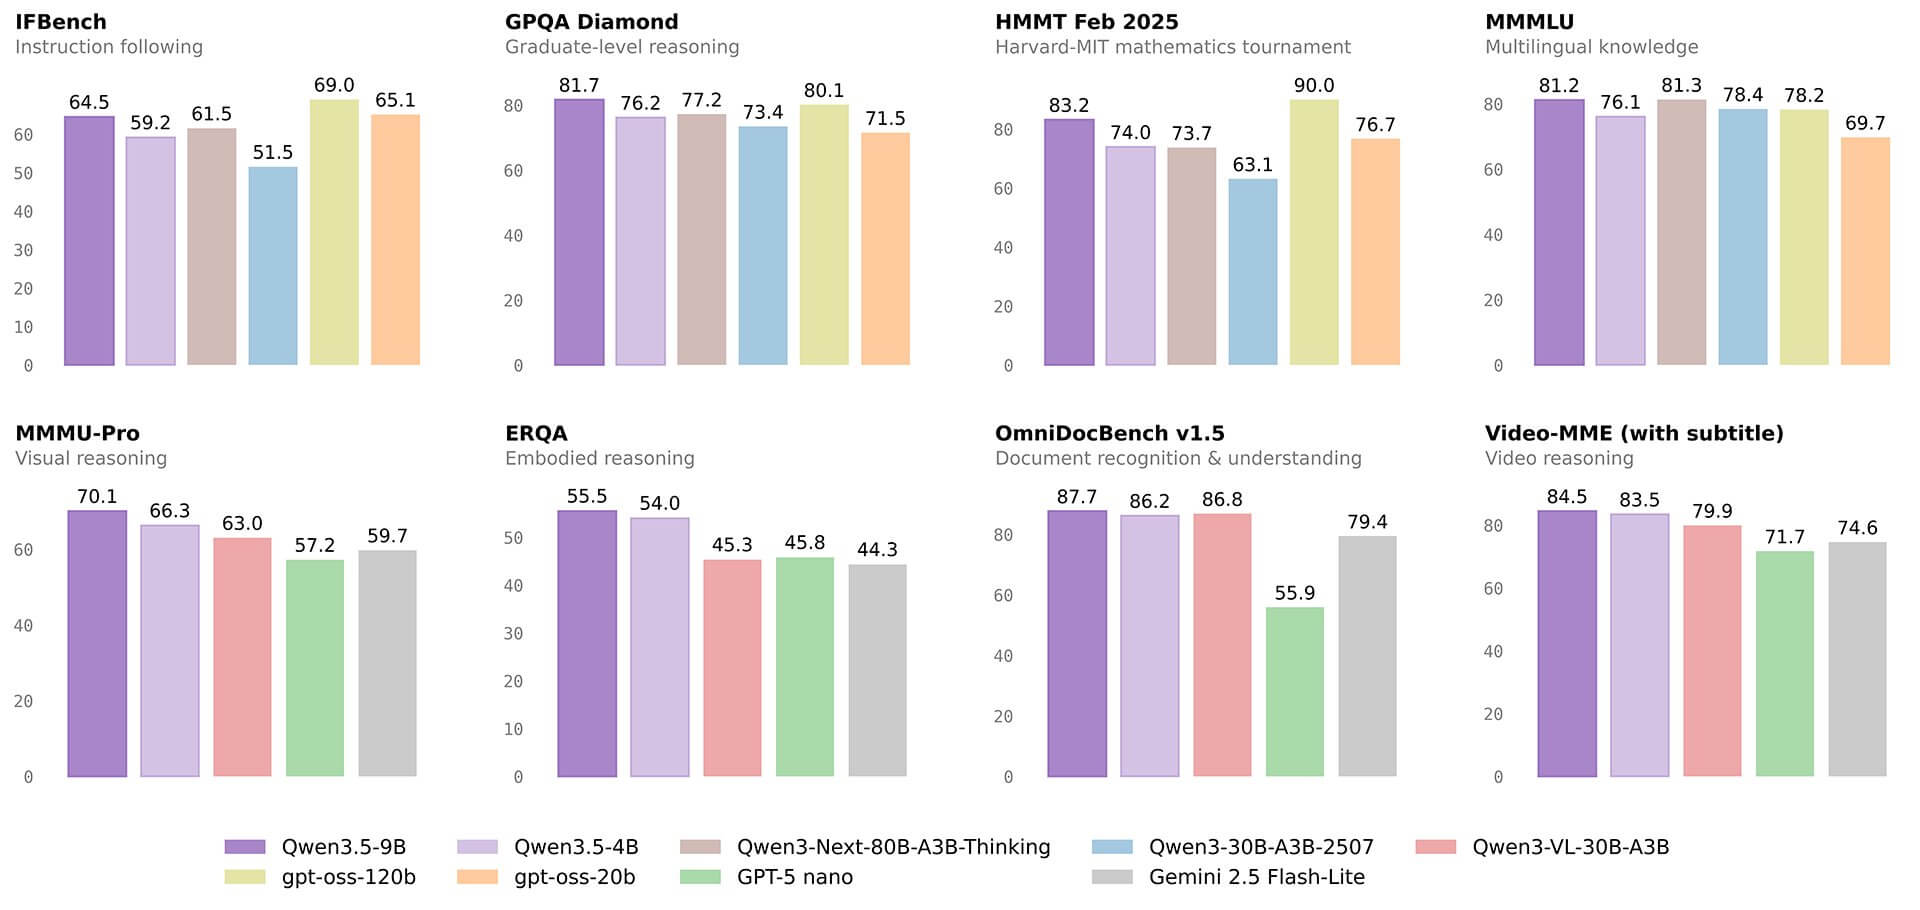
Alibaba released the Qwen3.5 Small Series, four models ranging from 0.8B to 9B parameters. The 9B model outperforms OpenAI's 120B gpt-oss on multilingual knowledge and graduate-level reasoning benchmarks.
You can deploy them locally, including on standard laptops and edge devices.
Model Lineup
Each model targets a different use case and hardware tier.
- 0.8B & 2B: optimized for edge devices like sensors and wearables
- 4B: multimodal, supports a 262,144-token context window
- 9B: the flagship reasoning model, 13x smaller than its closest rival
Architecture
Alibaba replaced the standard Transformer with a Gated Delta Networks and sparse Mixture-of-Experts design.
- Linear attention reduces memory usage at inference
- Sparse MoE activates only a fraction of parameters per token
- Early fusion trains text and image tokens together from scratch
How to Run It
Models run locally with standard open-source inference tools.
- Download via Hugging Face or ModelScope
- Compatible with Ollama, llama.cpp, and Hugging Face Transformers
- Base models are included for fine-tuning and research
|
|
|
|
Presented by LlamaIndex
|
|
#1 Agentic OCR for document ingestion
|
|
LlamaParse (LlamaIndex) turns messy PDFs, spreadsheets, images, and even scanned or handwritten files into clean, structured outputs (Markdown, JSON, or HTML).
Feed AI agents with real document context and ship ingestion pipelines that scale without constant upkeep. Trusted by Fortune 500 teams and top AI builders like Lovable and Tabs.
Go from raw docs to production-ready knowledge, fast.
|
|
|
|
partner with us
|
|
Top Paper
|
|
|
|
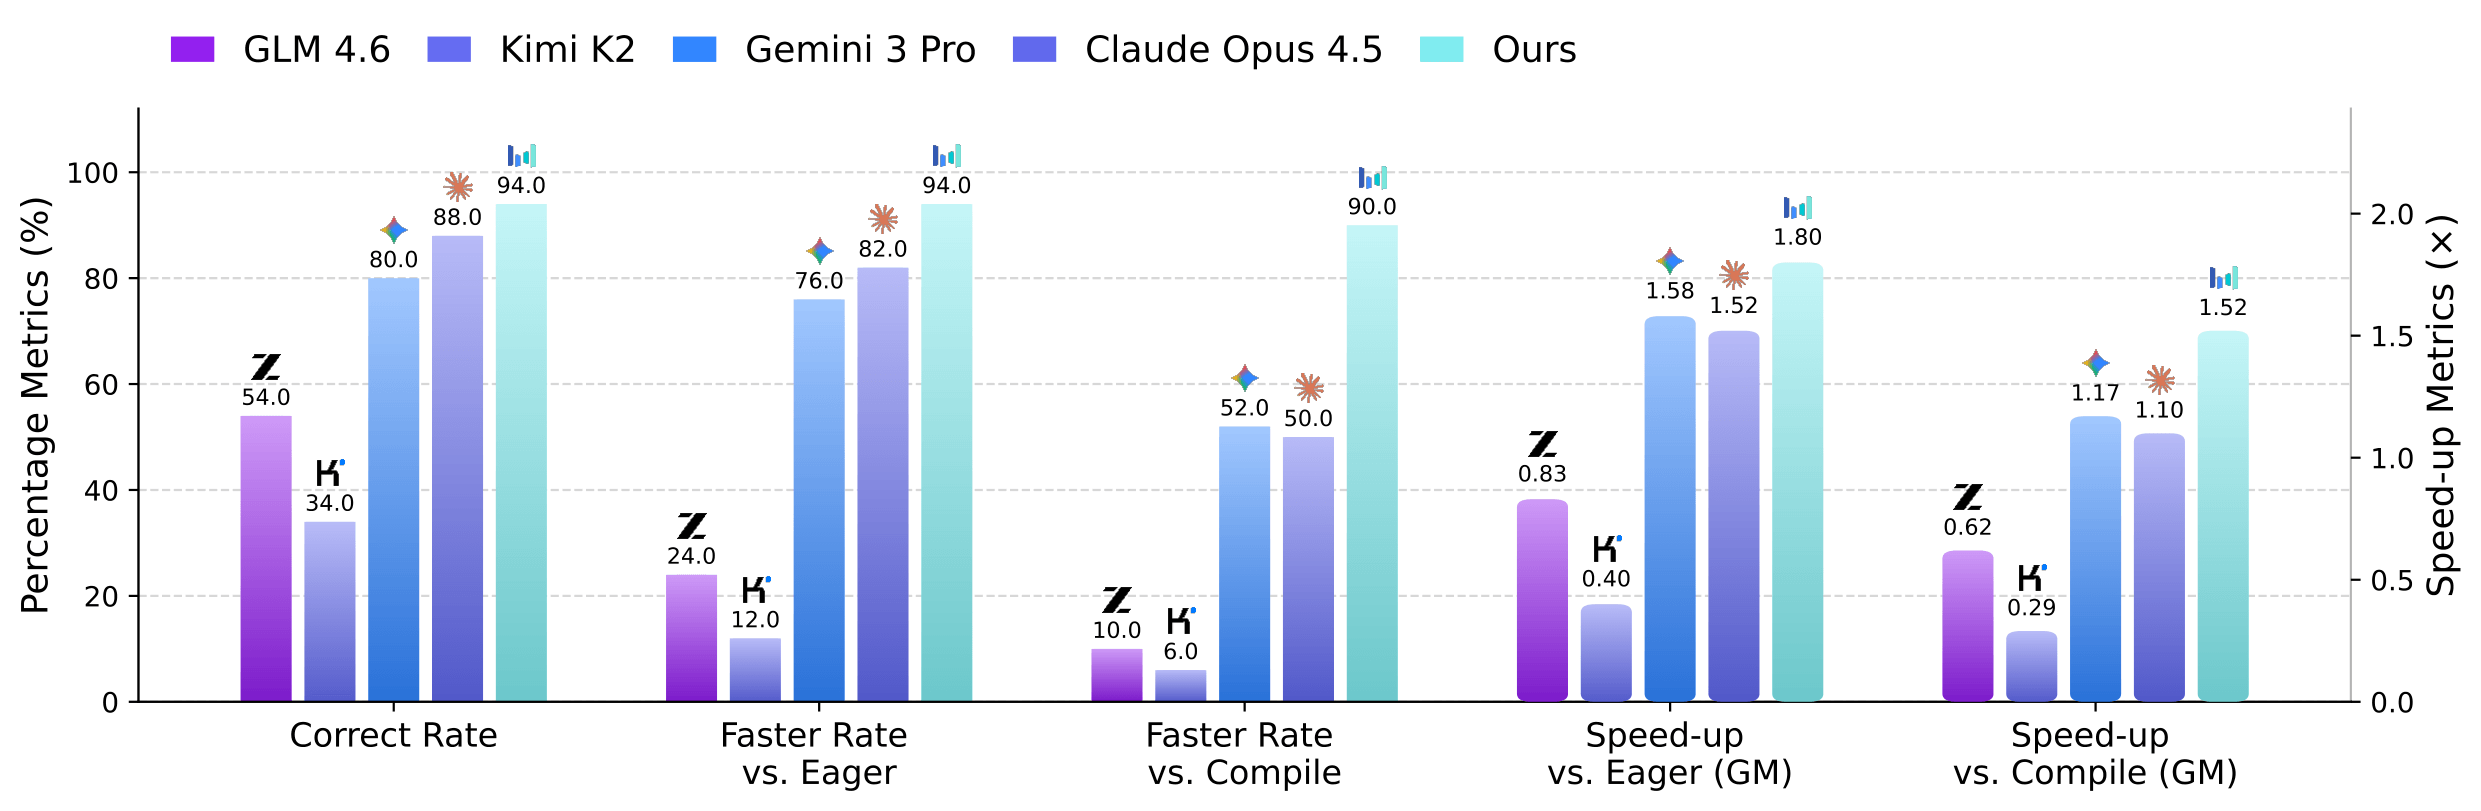
ByteDance presents CUDA Agent, solving 98.8% of GPU coding tasks while beating torch.compile 96.8% of the time
|
|
1,839 Likes
|
|
The CUDA Agent is a large-scale reinforcement learning system that writes and optimizes CUDA kernels based on real GPU performance. It does not stop at compiling code. It profiles kernels and trains directly on speed.
CUDA kernels run custom operations on NVIDIA GPUs. Performance depends on hardware details such as warps (groups of threads), memory bandwidth, and bank conflicts.
These factors do not appear in simple correctness checks. CUDA Agent rewards actual speed measured in a controlled profiling environment.
Key features and results
-
Reinforcement learning trained on real profiling speed, not compile success
-
6,000 synthesized training tasks (CUDA-Agent-Ops-6K) released publicly
-
98.8% overall pass rate on KernelBench
-
96.8% faster-than-compile rate vs. torch.compile
-
2.11× geometric mean speedup vs. torch.compile
-
90% faster-than-compile on hardest Level-3 split
-
~40-point advantage over proprietary models on Level-3
You can access the paper, GitHub repo, and CUDA-Agent-Ops-6K dataset to reproduce training or benchmark your own CUDA optimization agents.
|
|
|
|
Presented by Postman
|
|
Catalog all your APIs and services–yes, all of them
|
|
Get a continuous, real-time view of every API and service across your organization.
Use Postman's new API Catalog, including which team owns them, their specs, tests, CI activity, and how they behave in production in one place, so you can know what exists and what's actually working.
|
|
|
|
partner with us
|
|
Top Repo
|
|
|
|
Tongyi Lab unveils CoPaw, an open-source self-hosted agent workstation that manages memory, tools, and multi-channel access
|
|
6,742 Stars
|
|
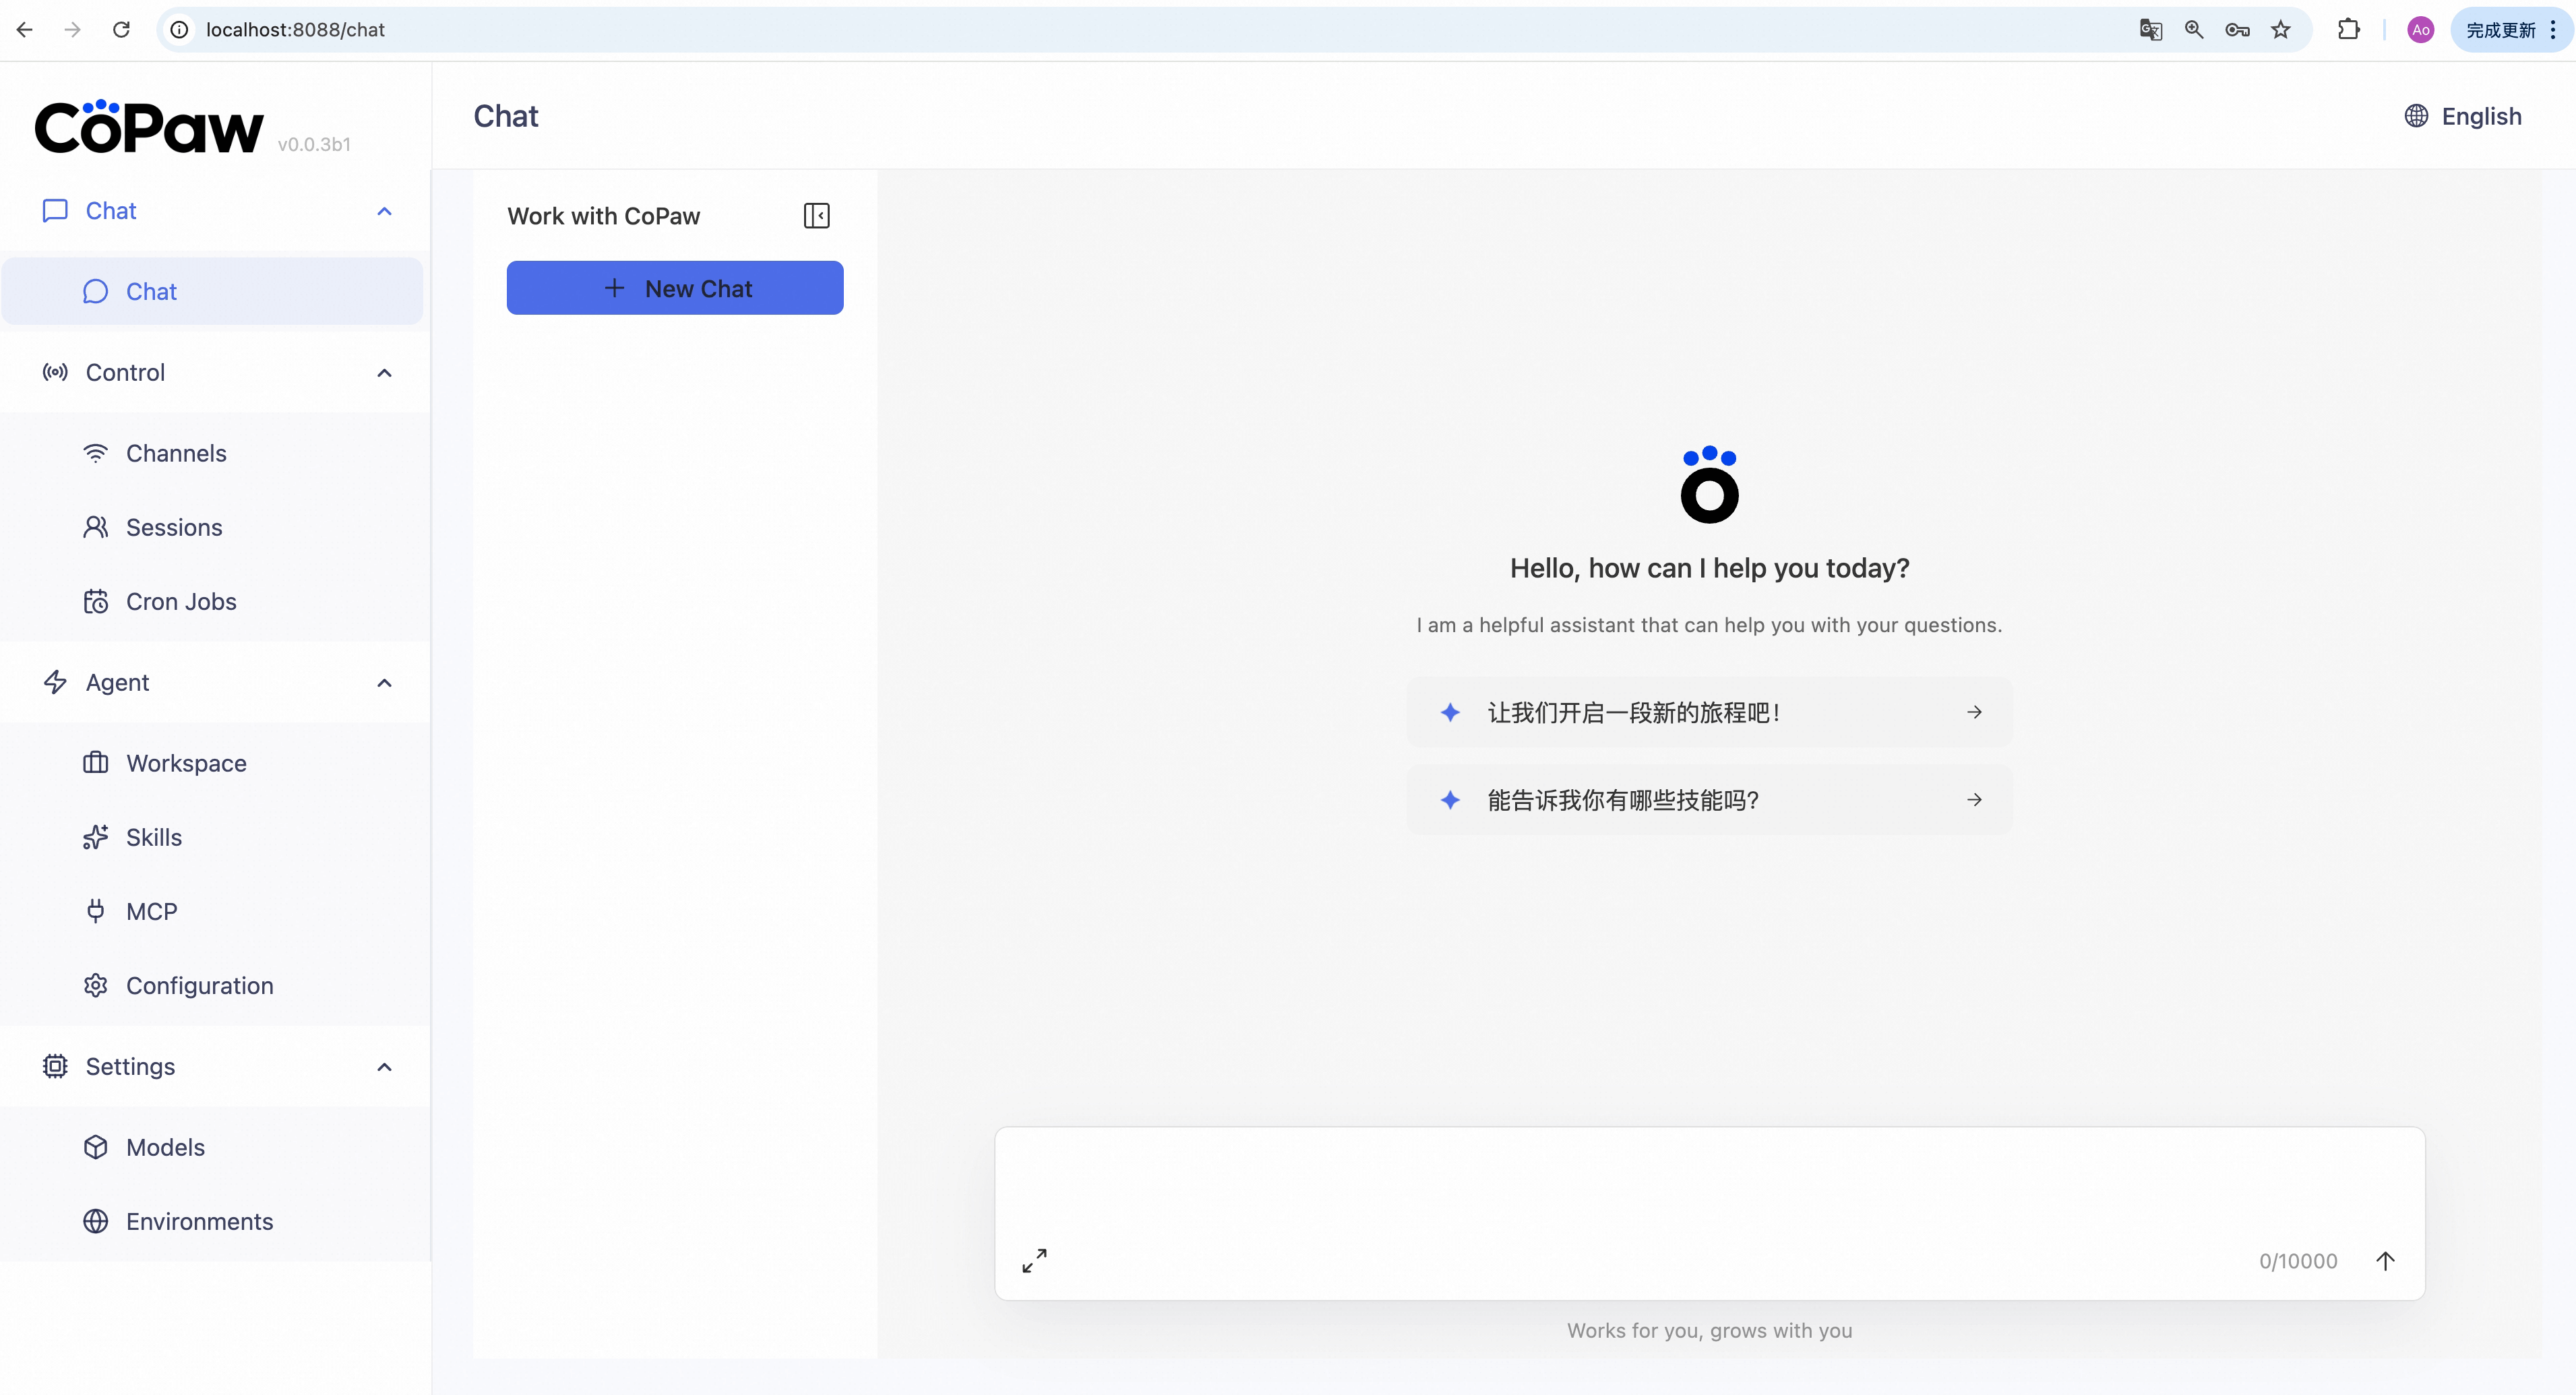
Alibaba’s Tongyi Lab just open-sourced CoPaw, a self-hosted personal agent workstation. It treats your AI as infrastructure you control, not just a chat window.
Instead of calling an LLM statelessly, you run a structured runtime that manages memory, tools, and multi-channel access.
CoPaw solves a common problem: LLM APIs forget context and lack persistent workflows. It adds long-term memory through ReMe (a memory module that stores past interactions) and runs on AgentScope, which coordinates agent logic and tools.
Key features and results:
-
Run local models via llama.cpp, MLX, or Ollama.
-
Plug in private or cloud model APIs.
-
Persist memory across sessions and platforms.
-
Add Python-based “Skills” without editing core code.
-
Connect one agent to Discord, DingTalk, Feishu, QQ, iMessage.
-
Schedule proactive tasks that push updates automatically.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 250,000+ AI developers?
|
|
|
|
|
