|
Hey,
Your daily briefing is ready. You can finally take a break from the AI firehose.
Our algos spent the night splitting signal from noise and pulled the top news, models, papers, and repos.
Here’s the must-read:
|
|
Together with:
|
|
|
|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer.
Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
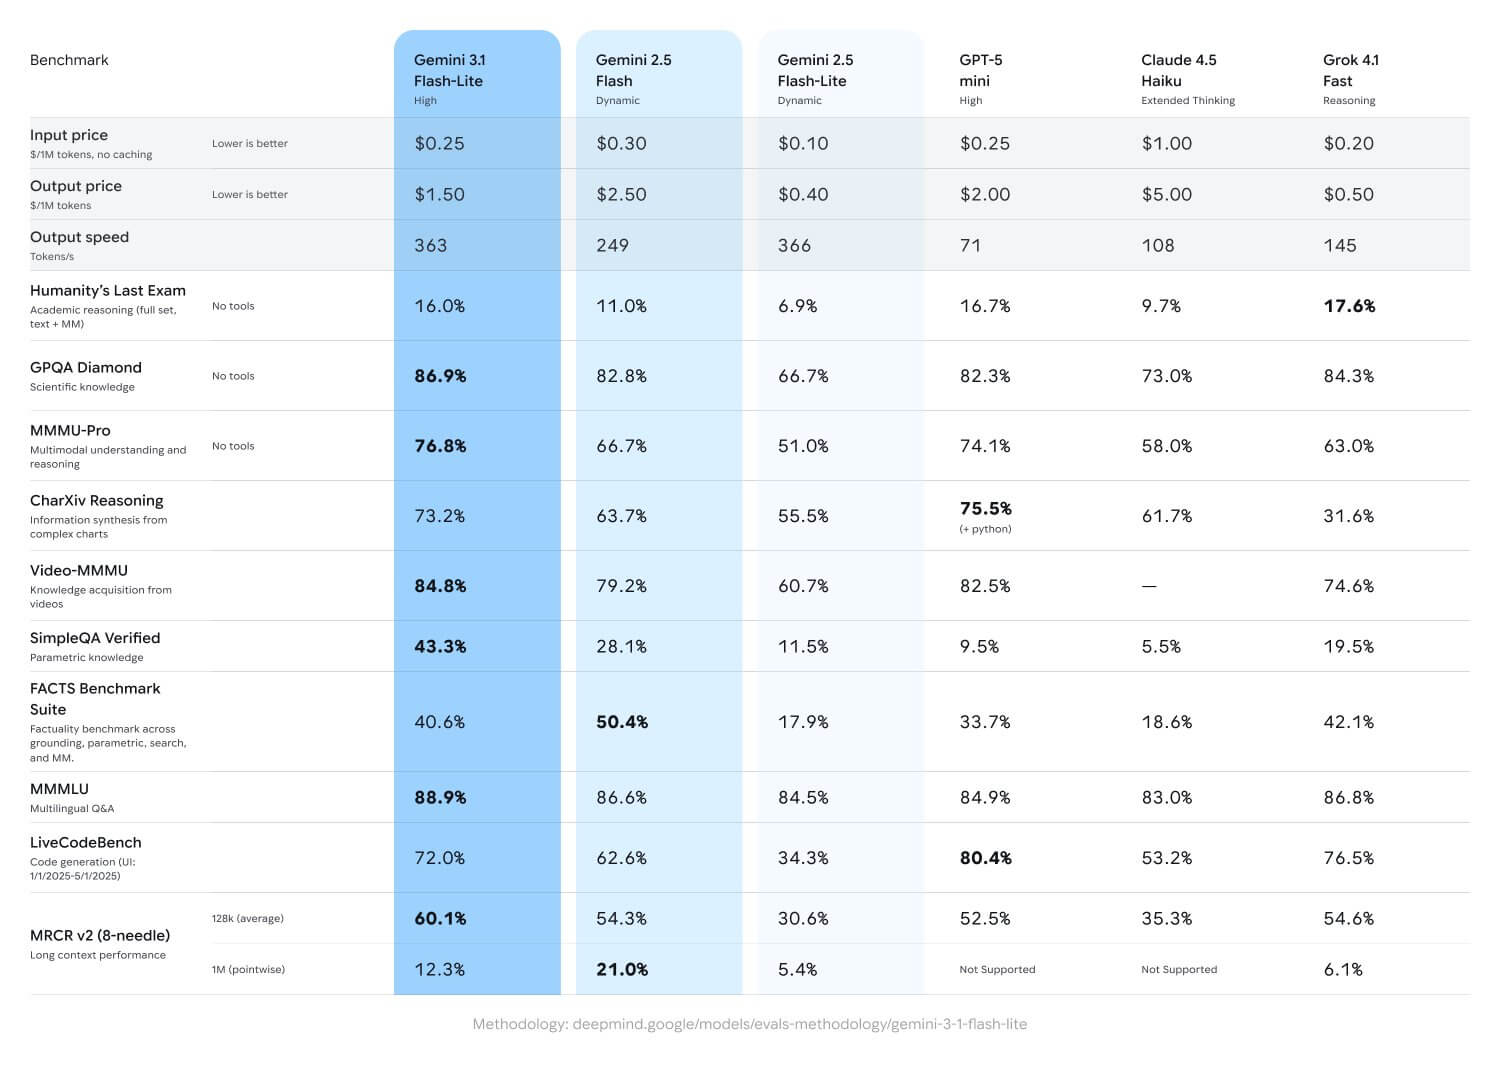
Google releases Gemini 3.1 Flash-Lite, scoring 86.9% on graduate-level reasoning while costing less than earlier Flash models
|
|
18,974 Likes
|
|
Many AI systems process millions of requests per day, such as translation services, moderation systems, or automated content generation. Larger models handle complex reasoning but cost more to run.
Flash-Lite targets the opposite problem: handle large workloads quickly while keeping token costs low.
You can access the model through the Gemini API in Google AI Studio or through Vertex AI for production systems.
You send prompts through the API and optionally adjust the model’s thinking level, which controls how much internal reasoning the model performs before answering.
Key features and results
-
$0.25 per 1M input tokens and $1.50 per 1M output tokens pricing.
-
2.5× faster time-to-first token and 45% higher output speed than Gemini 2.5 Flash.
-
Arena Elo 1432, 86.9% GPQA Diamond, and 76.8% MMMU Pro benchmark scores.
-
Configurable thinking levels let you adjust reasoning depth for different workloads.
-
Handles tasks such as translation pipelines, moderation systems, UI generation, and simulations.
|
|
|
|
Presented by Lambda
|
|
How to improve your Model FLOPS Utilization by >25%
|
|
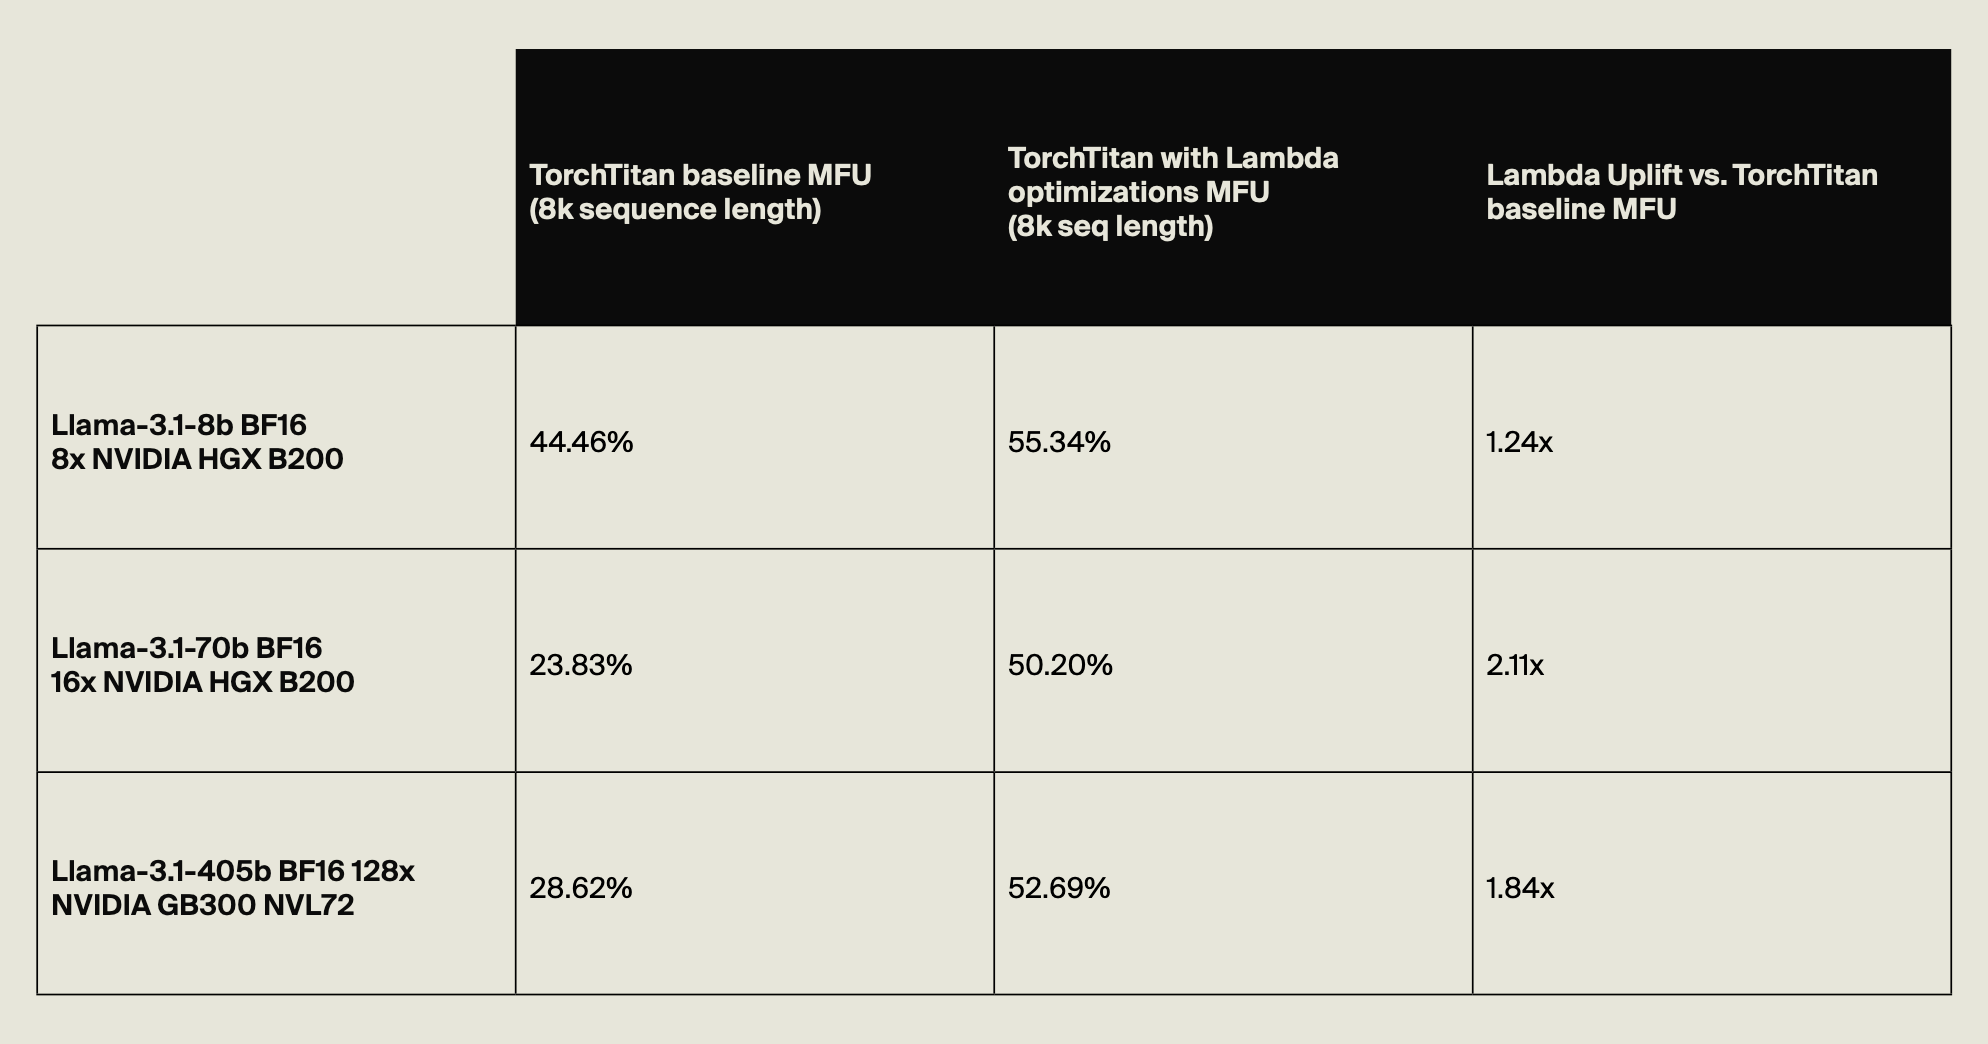
Most large-scale training runs operate at 35–45% Model FLOPS Utilization (MFU). You're paying for twice the compute you're using.
Lambda's engineers benchmarked Llama 3.1 models from 8B to 405B on NVIDIA Blackwell GPUs and traced efficiency loss to its root causes:
-
Memory overhead
-
Parallelism strategy
-
Serialized communication
The result: a first-of-its-kind reproducible framework that pushed MFU past 60% (25%+ improvement vs. industry benchmark) with no changes to model architecture.
|
|
|
|
partner with us
|
|
Top News
|
|
|
|
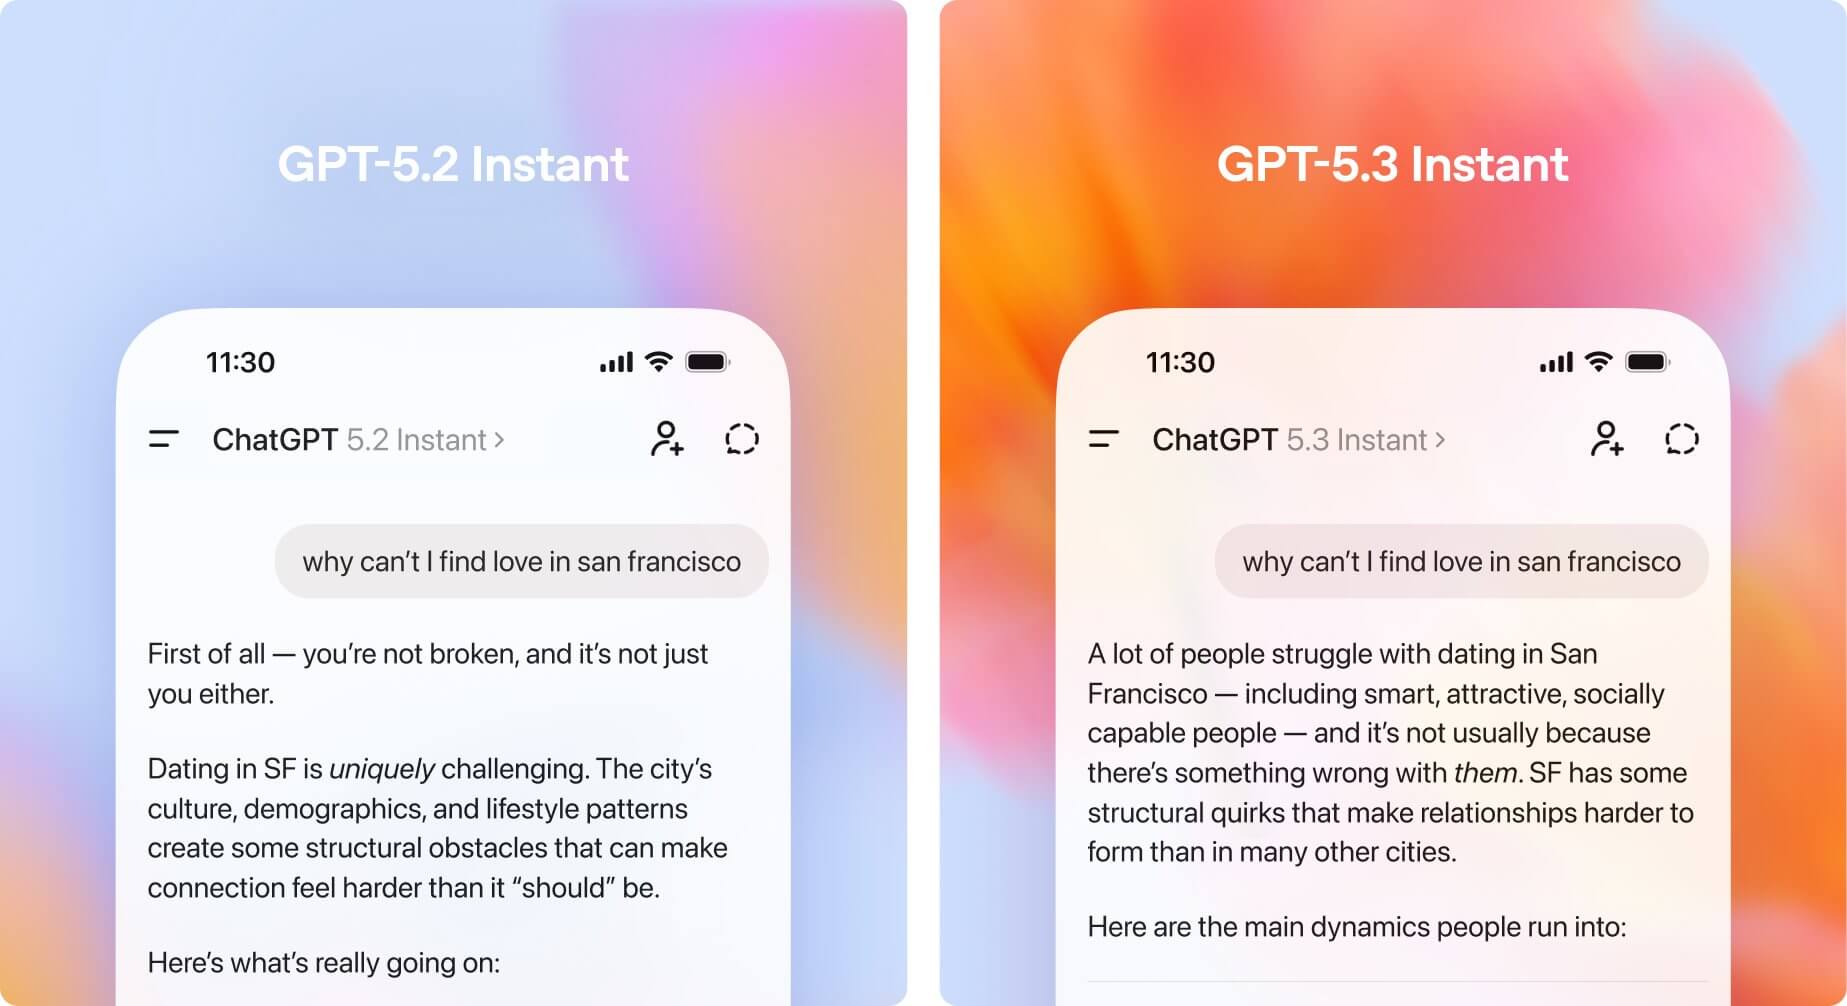
OpenAI ships GPT-5.3 Instant, cutting hallucinations 26.8% and removing defensive response preambles
|
|
14,839 Likes
|
|
This update changes how ChatGPT answers questions, reducing unnecessary refusals and long safety preambles that previously interrupted responses.
The model now starts answers more directly, integrates web results more clearly, and improves factual accuracy across common queries.
Key features
-
Direct answers: Reduces unnecessary refusals and removes long safety disclaimers before responses.
-
Better web synthesis: Combines search results with model reasoning instead of listing disconnected links.
-
Improved accuracy: Internal evaluations show hallucinations drop 26.8% with web access and 19.7% without it.
-
Clearer writing: Responses use structured explanations and concrete details instead of abstract phrasing.
Availability
-
You can access it through the API using gpt-5.3-chat-latest.
-
GPT-5.2 Instant remains available in legacy models until June 3, 2026.
|
|
|
|
Presented by TinyFish
|
|
Build the Agentic Web. 9 weeks to $2M Seed. 100% Virtual
|
|
Meet theTinyFish Accelerator: a $2M-backed, YC-style program for founders building agentic web apps. Partnered with ElevenLabs, Google, MongoDB & more for credits, mentorship & support.
Applications are now open!
|
|
|
|
partner with us
|
|
Top News
|
|
|
|
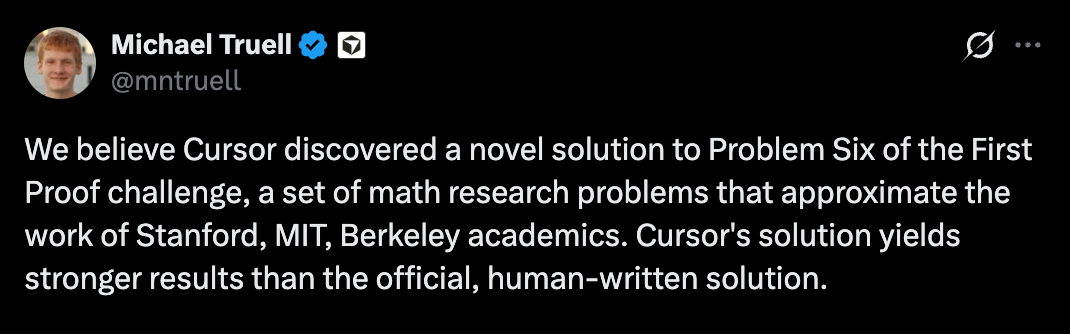
Cursor runs autonomous multi-agent system four days to solve a research-level math benchmark problem
|
|
7,742 Stars
|
|
The system ran fully autonomously for four days using Cursor’s multi-agent coordination harness and produced a proof stronger than the official human solution.
The most notable result: the proof increases the bound constant c from 0.03 to 0.13, which strengthens the mathematical guarantee.
The system tackles a real research workflow: explore proof ideas, test them, and verify each step. It uses tools from spectral graph theory, a field that studies graphs through matrix eigenvalues.
Key features and results
-
Multi-agent system coordinates planning, reasoning, verification, and search across long-horizon proof exploration.
-
Agent applies a technique for graph eigenvalue analysis.
-
Proof improves the bound constant from 0.03 to 0.13, which strengthens the theoretical result.
-
Solution partitions the entire vertex set into light components, unlike the earlier subset-based approach.
-
External mathematicians reviewed the proof and report no clear errors.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 250,000+ AI developers?
|
|
|
|
|
