Hey, | Welcome to this week's edition of AlphaSignal.
Whether you are a researcher, engineer, developer, or data scientist, our summaries ensure you're always up-to-date with the latest breakthroughs in AI.
Let's get into it!
Lior |
|
|
|
IN TODAY'S SIGNAL | Top Paper: Deleting 40% of LLM Layers Without Drop in Accuracy.
Top Announcements: OpenAI Demos New Voice Engine, Grok 1.5, Nous1-bit replication.
Top Model/Spaces: dbrx-instruct, AnimateDiff, Turbo Sketch
Read Time: 4 min 47 sec |
|
|
|
TOP PAPER | Language Models | Deleting 40% of LLM Layers Without Drop in Accuracy | ⇧ 2573 ⇆ 224 | 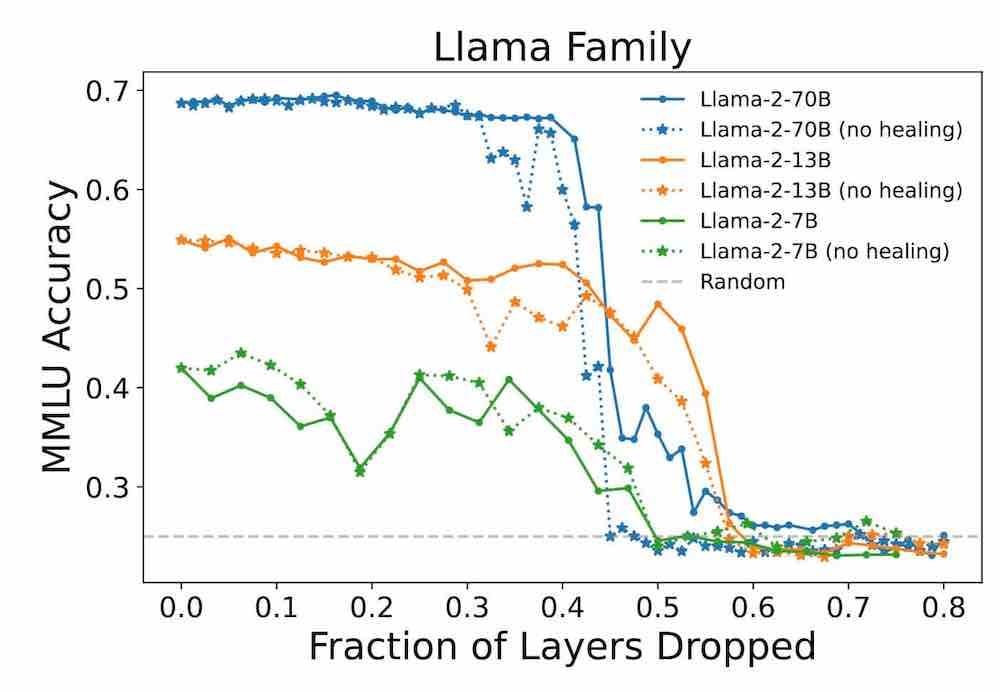 | What's New | Meta, Cisco, and MIT researchers demonstrated that large language models (LLMs) could have up to 40%-50% of their layers pruned with minimal impact on accuracy.
The process involved pruning, quantization, and parameter-efficient finetuning (PEFT) strategies, testing on models ranging from 2B to 70B parameters, across the Llama, Qwen, Mistral, and Phi families.
Performance Impact: - Llama 70B and Llama 13B models showed slight accuracy loss after 40% and 50% layer pruning, respectively.
- Other models experienced minimal accuracy declines with 20-30% of layers removed.
Pruning Process: - Identification of Layers for Removal: The team used a similarity score to find redundant or less important layers. Layers with the lowest angular distance between their representations were targeted for pruning.
- Layer Pruning Strategy: They progressively deleted layers that showed minimal change in output when compared to adjacent layers.
- Fine-tuning Post-pruning: The models were fine-tuned using QLoRA on the C4 dataset to recover any lost performance, focusing on regaining performance on benchmarks like MMLU and BoolQ.
Cost Benefits: The research highlighted a direct linear reduction in both memory and compute requirements for inference as layers were pruned, showcasing a method to make LLMs less resource-intensive.
Critical Role of Shallow Layers: Findings indicated that shallow layers had a disproportionate impact on model outcomes, suggesting deep layers could be removed with negligible effects. This points to potential inefficiencies in how deep layers are currently utilized. | Why This Matters | It suggests AI models might be more efficient than previously thought, opening paths to faster, cheaper AI, challenging the necessity of large models, and indicating a need to refine training methods to fully utilize model capacity. | Community Feedback | Tomas Miskov: "Interesting stuff. So why can't we just train a smaller network and get the same result? " | Stuart Watson: "The LLM AI field is so new that proper optimisation is just starting. Papers like this show there are massive leaps available"
| | Read paper |
|
|
|
 | Secure your spot at TED2024 | April 15-19
| Did you know you could be a part of the TED Conference? Let new sources of insight inspire and transform your vision. This year’s speaker lineup will feature the latest in technology, art, business, science and so much more. Seats are filling up fast – apply today.
| | Secure your spot | partner with us |
|
|
|
TOP ANNOUNCEMENTS | Audio Generation | | OpenAI just released Voice Engine, a text to speech model capable of generating natural sounding voice from a text and 15 sec audio sample. This model is already integrated into the text-to-speech API, ChatGPT Voice, and Read Aloud features.
This technology was reportedly developed in 2022 and aimed at generating emotive and realistic custom voices, very similarly to what Hume AI is trying to achieve through its latest Empathetic Voice Interface. OpenAI is carefully deploying this new technology given the risks associated to its misuse, and is working towards adding watermarking and voice authentication protocols. | ⇧ 5123 ⇆ 1511 | | Language Models | | Grok-1.5, developed by xAI, supports a 128,000-token context and shows improved scores: 50.6% on MATH, 90% on GSM8K, and 74.1% on HumanEval benchmarks.
Built on a JAX, Rust, Kubernetes framework, it enhances long-context comprehension. xAI has announced Grok-1.5 will be available this week and is open-source, with the development of Grok-2 underway, focusing on coding and math task performance improvements. | ⇧8622 ⇆ 3110 | | Replication | | Nous Research validated the Bitnet paper's claims, demonstrating a 1B model on the Dolma dataset using 1-bit quantization for significant VRAM efficiency. Their findings, shown on Weights & Biases, compare Bitnet to FP16 runs, highlighting a potential to run 70B models on 24GB VRAM. This approach suggests dramatic reductions in memory requirements, enabling larger models on limited hardware. | ⇧ 864 ⇆ 180 | | |
| |
|
|
TOP SPACES/MODELS | Text-to-Video | | AnimateDiff-Lightning is a lightning-fast text-to-video generation model. It can generate videos more than ten times faster than the original AnimateDiff. From a text prompt, the distilled model from AnimateDiff SD1.5 v2 generates a video in just a few seconds.
You can try it in the space by entering a text prompt and selecting the base model, the type of motion you want and the number of inference steps. | ⇧ 177 | | Image-2-Image | | The space proposes a general method for adapting a single-step diffusion model to new tasks and domains through adversarial learning. This enables to leverage the internal knowledge of pre-trained diffusion models while achieving efficient inference.
You can try it directly within the space by entering a text prompt, sketching a first draft, choosing the style and the level of sketch guidance and generate an image based on your settings. | ⇧ 156 | | Language Models | | DBRX Instruct, a specialized fine-tuned version of the DBRX LLM for few-turn interactions, leverages a 132B parameter MoE architecture, trained on 12T tokens. It excels in tasks requiring precise instructions, and is open-source, offering superior performance in coding and natural language tasks. It supports up to 32K token inputs for English text. | ⇧ 772 | | |
| |
|
|
Ghita is an editor at AlphaSignal and AI Engineer at Clear Ventures. Experienced in Computer Vision and Language models, she holds 2 masters in Applied Mathematics. |
|
|
|
Want to promote your company, product, job, or event to 175,000+ AI researchers and engineers? | | Sponsor |
|
|
|
|
