|
Hey,
Your daily briefing is ready. You can finally take a break from the AI firehose.
Our algos spent the night splitting signal from noise and pulled the top news, models, papers, and repos.
Here’s the must-read:
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer.
Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
Alibaba upgrades Qwen3-TTS with 49+ timbres, giving far more control over voice style
|
|
2,534 Likes
|
|
|
Alibaba’s new Qwen3-TTS update lands with the energy of a team that knows exactly what developers want: better voices, clearer speech, and more control.
The earlier version already handled basic text-to-speech, but it struggled to sound truly character-specific or language-flexible. That gap set the stage for a sharper upgrade.
The team traced the issue to limited timbres and uneven multilingual accuracy. The insight was simple: expand the voice set and refine prosody, the rhythm and emphasis that make speech feel natural.
The breakthrough arrives as a model with 49+ timbres, 10 languages, and 9 dialects, backed by lower word-error rates than MiniMax, ElevenLabs, and GPT-4o-Audio-Preview on the same benchmark. It gives developers a broader palette and more predictable speech control.
Key features:
-
49+ timbres across genders, ages, and character roles
-
10 languages and 9 Chinese dialects
-
Lower WER than all tested baselines
-
Improved prosody and rate adaptation
You can use Qwen3-TTS through the Qwen API or run it locally via HF or ModelScope.
|
|
|
|
Trying to “Clean Up” Messy Sales or AI Training Data? Here’s the Fix
|
|
Sponsored
|

|
Mid-sprint and you’re already rerunning scripts just to deduplicate job postings that were “new” last quarter. Your sales ops is nagging for fresh leads, but you’re stuck writing one-off parsers and throwing out 40% of your vendor’s “verified” contacts.
You know the result: half your signals go stale before hitting production. Models degrade, dashboards lie, and the blame circles back to your data sources.
Coresignal is a leading data provider that gives up-to-date information, helping develop AI platforms and enrich sales funnels.
Skip the endless ETL cycle. With Coresignal, you get:
- Structured, AI-ready data on companies, employees, jobs, all in one place
- Real-time updates and full coverage (over 1B records)
- APIs that return fresh data in formats you already use
You can preview, enrich, or query in playgrounds before buying. Plus, everything’s business-focused and privacy-compliant.
Through December 15th, ALPHASIGNAL15 gets you 15% off your first monthly or annual plan.
If you’re tired of spending more time cleaning than building, here’s a dataset that doesn’t fight you at every step.
|
|
|
|
partner with us
|
|
Top News
|
|
|
|
Poetiq, founded only 170 days ago, hits 54% on ARC-AGI-2 ahead of Deep Think
|
|
2,365 Likes
|

|
Poetiq’s week started with a bold claim: a six-person team, only 173 days old, outscored Google’s Gemini 3 Deep Think on ARC-AGI-2 while spending half as much.
ARC-AGI is a reasoning test built from small grid puzzles that force models to infer patterns instead of memorizing facts. Hitting 54% at $31 per task sets a new bar for test-time reasoning systems.
The problem is simple to state but hard to solve: frontier models know a lot, but they often miss the multi-step logic that these puzzles require. Poetiq approached this by treating reasoning like debugging.
The system tries an idea, checks it, critiques it, and tries again without retraining any model. The breakthrough came from a meta-system that controls the entire loop using standard API calls.
Key features:
-
Runs iterative reasoning loops without modifying base models.
-
Uses fewer than two calls per task to control cost.
-
Writes code when helpful and audits results for correctness.
-
Works across Gemini 3 Pro, GPT-5.1, Grok 4 Fast, and GPT-OSS.
The impact is clear: clever orchestration now moves accuracy in ways once reserved for bigger models and bigger budgets.
|
|
|
|
Top News
|
|
|
|
Microsoft presents open-source VibeVoice, a TTS system generating 90 minutes of multi-speaker audio
|
|
2,143 Likes
|
|
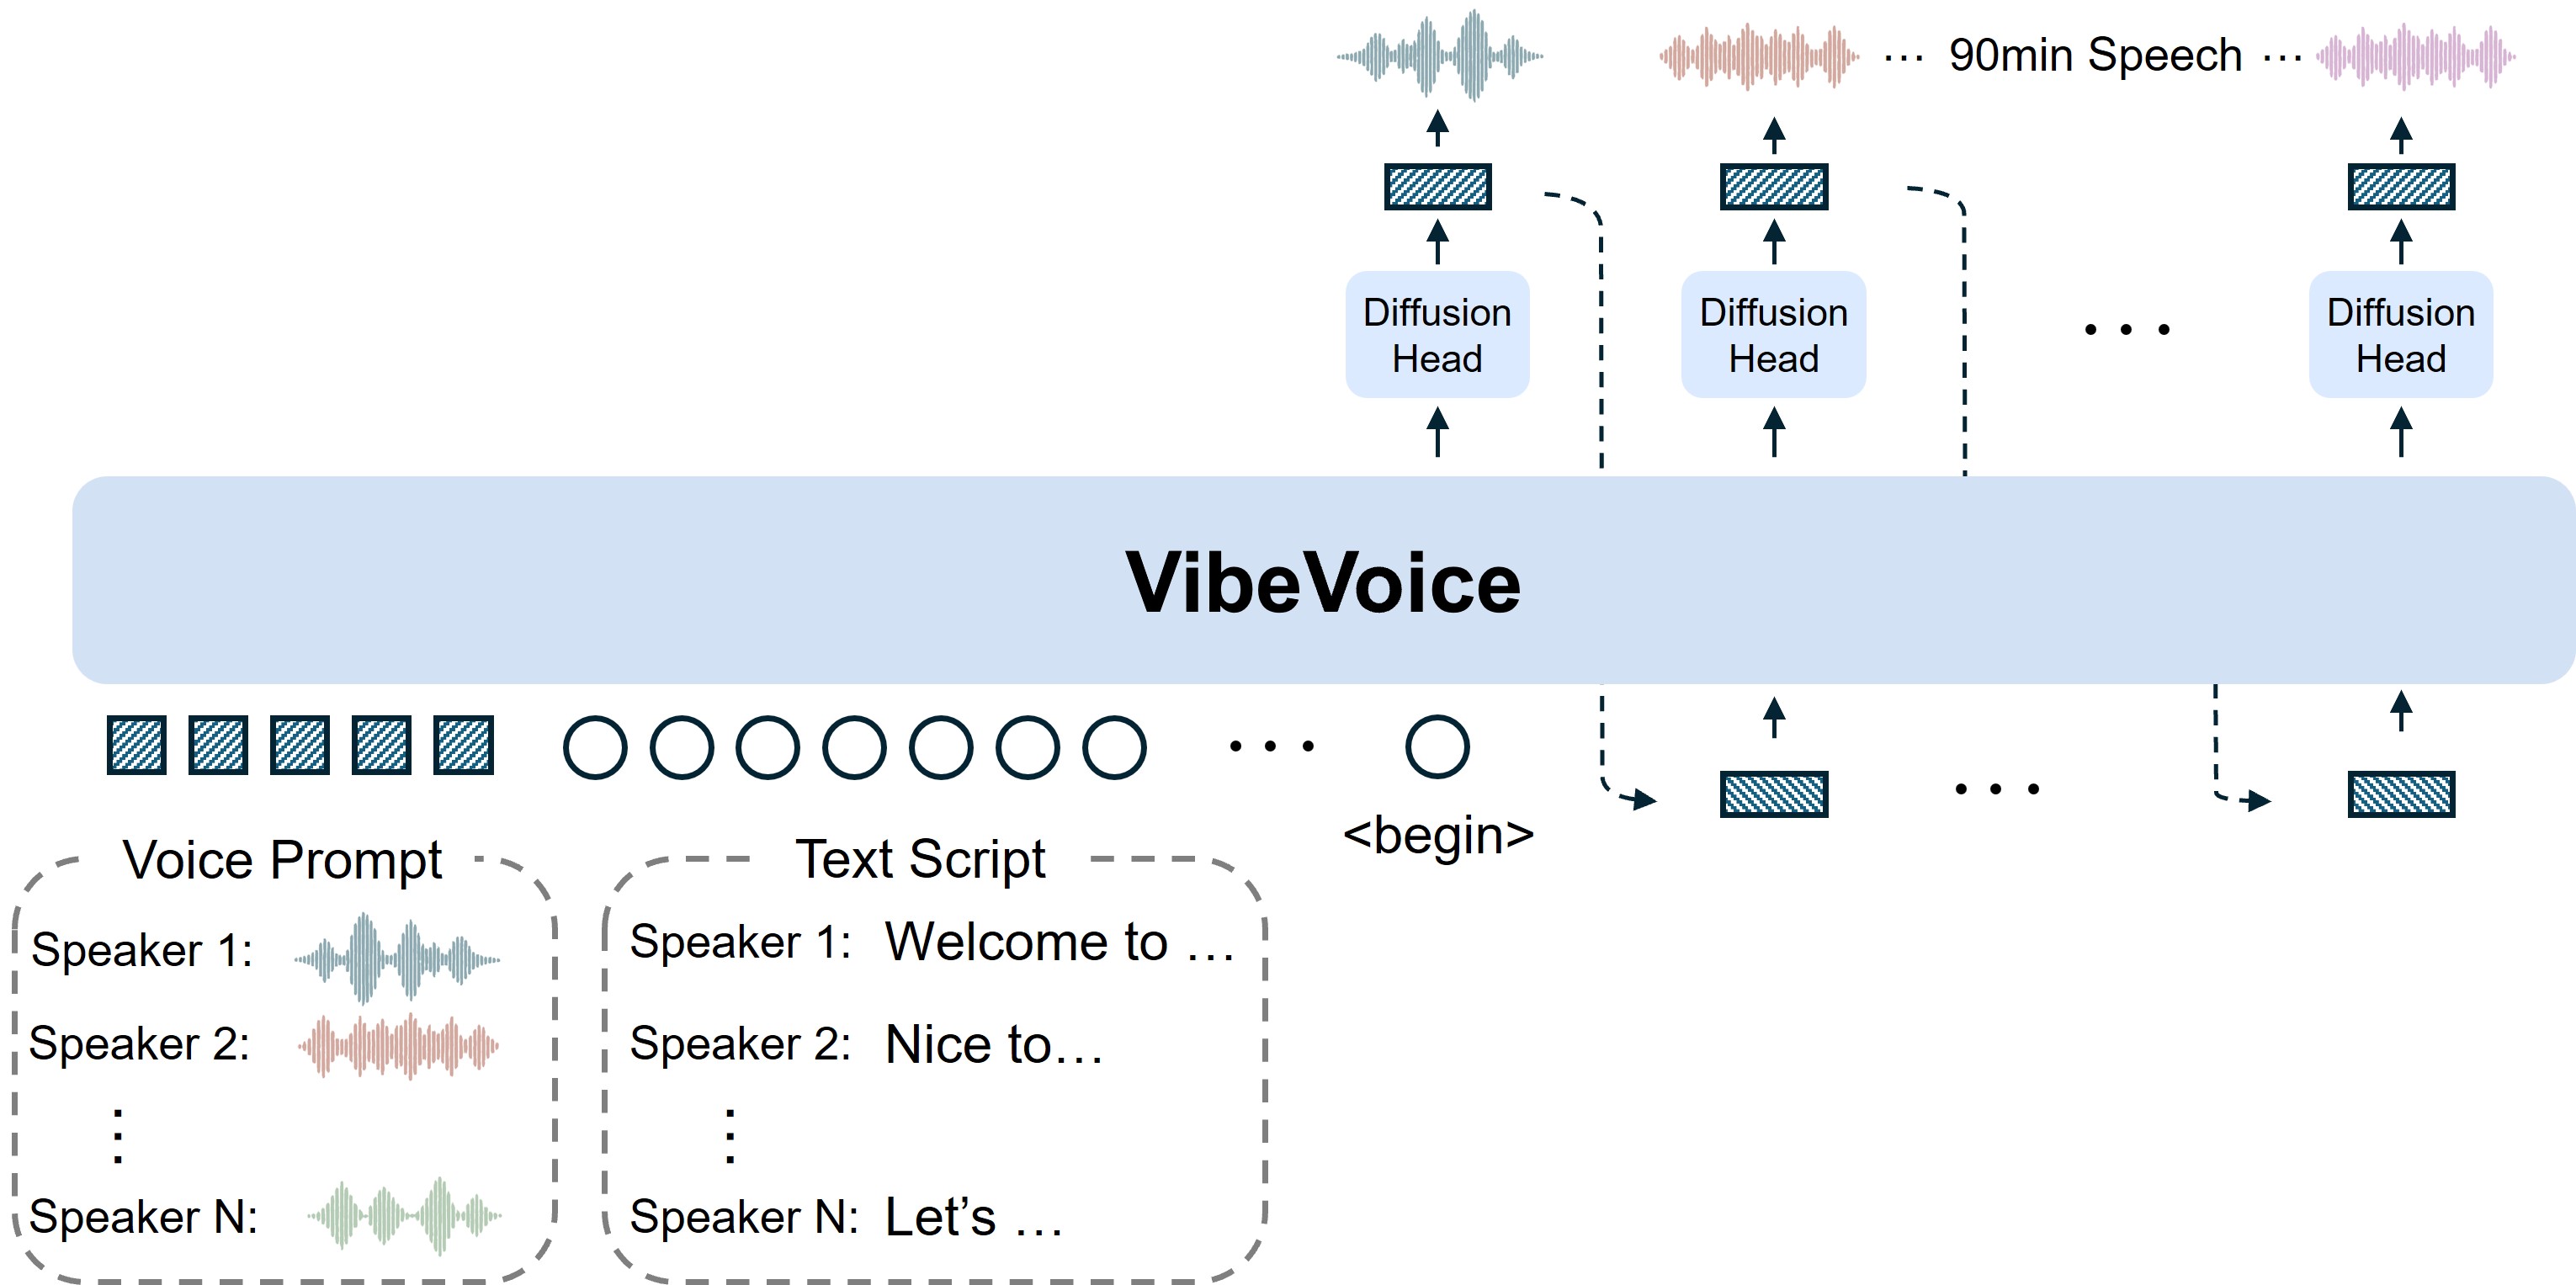
VibeVoice arrives like a TTS project that decided podcasts shouldn’t be hard anymore. The setup is simple: long-form, multi-speaker audio usually breaks once you push past a few minutes.
Models lose voices, drift in tone, or collapse under sequence length. VibeVoice steps in with a different plan. The insight comes from continuous speech tokenizers that shrink audio into slow, information-dense tokens at 7.5 Hz.
You can think of it as “compress first, then reason,” which lets the system stay stable for 90-minute conversations with four speakers. An LLM handles what’s being said; a diffusion head handles how it sounds.
That combination produces the breakthrough: stable voices, natural handoffs, and real-time synthesis in ~300 ms.
Key features and results:
-
90-minute multi-speaker generation with four distinct voices.
-
Realtime 0.5B model outputs audible speech in ~300 ms.
-
Continuous tokenizers reduce sequence length at 7.5 Hz.
-
MOS preferences show higher perceived quality vs. baselines.
How to use it:
The models are available in GitHub and Hugging Face. The is a Colab Notebook for quickstart as well.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 250,000+ AI developers?
|
|
|
|
|
