| Hey, | Welcome to AlphaSignal – the most read newsletter by AI developers.
We bring you the top 1% of news, papers, models, and repos, all summarized to keep you updated on the latest in AI. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 5 min 02 sec | 🎖️ Top News
⚡️ Trending Signals
💻Top Repos
Unsloth is a platform that helps you fine-tune large models like Llama and Mistral, improving performance and reducing memory usage.
vLLM is a library for fast and memory-efficient LLM inference and serving, supporting various models and hardware.
Potpie helps create AI agents for code analysis, debugging, testing, and custom automation using a knowledge graph.
🧠 Top Lecture
|
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| AI Model | xAI releases Grok-3, the first AI model to break 1400 on Chatbot Arena, with “Think” mode for better reasoning
| ⇧ 44,583 Likes |
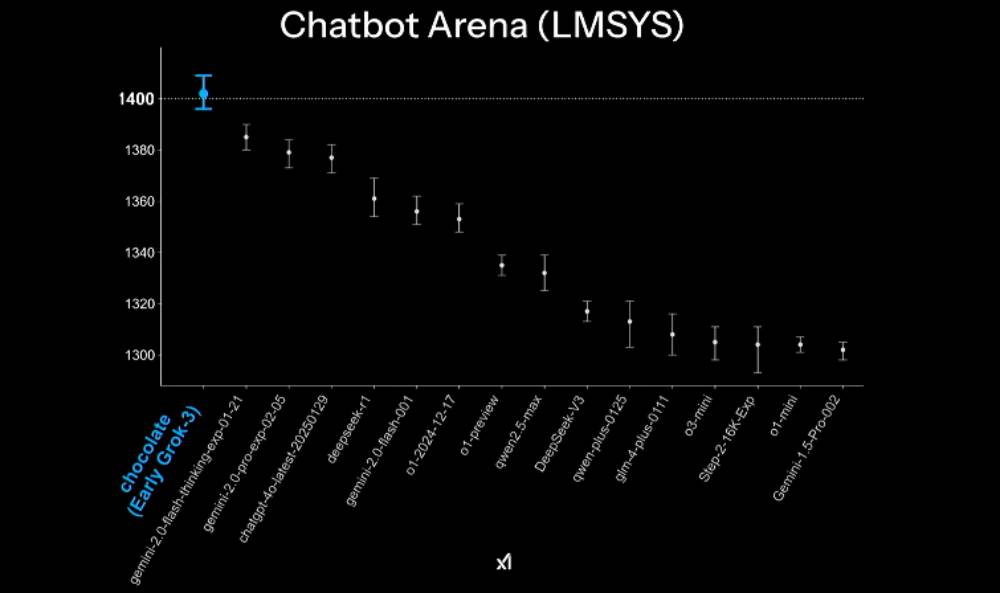
| What's New | xAI launches Grok-3, their latest AI model. It outperforms GPT-4o, Claude 3.5 Sonnet, and Gemini-2 Pro on AIME’24 (math), GPQA (graduate-level science), and LiveCodeBench (coding).
Key Features
Improved reasoning with Think Mode for logical processing and Big Brain Mode for complex problem-solving.
DeepSearch retrieves information and explains results with context-aware insights.
Optimized performance using 200,000 NVIDIA H100 GPUs for faster query processing.
Multimodal capabilities with text support and future plans for voice interaction.
Performance
It ranks #1 on Chatbot Arena, scoring over 1400, the highest recorded for a publicly available model.
- Math: Grok-3 outperforms leading models on AIME’24, handling complex algebraic and combinatorial problems more reliably.
- Science: It leads on GPQA, demonstrating strong knowledge of graduate-level physics, biology, and chemistry.
- Coding: On LiveCodeBench, it generates executable and optimized code more accurately than previous versions.
- Reasoning: It enables multi-step logical processing through its “Think” and “Big Brain” modes, improving problem-solving accuracy.
- Speed vs. Accuracy: The Grok-3 mini variant responds faster but sacrifices some reasoning depth.
Technical Details
Grok-3 trains on 10x more compute than its predecessor.
xAI uses Colossus, a 200,000 H100 GPU supercomputer, scaling training resources beyond Grok-2.
The model introduces reasoning variants, similar to OpenAI’s o3-mini and DeepSeek’s R1, that execute multi-step logical reasoning.
DeepSearch
DeepSearch extends Grok-3’s research capabilities. This feature retrieves and summarizes internet information, competing with OpenAI’s Deep Research and Perplexity AI’s DeepResearch. It answers general knowledge queries correctly but hallucinates URLs and omits key industry details in some cases. Some features remain in beta.
Grok-3 mini
Grok-3 mini prioritizes speed over accuracy. This smaller version delivers faster responses but sacrifices some reasoning capabilities. xAI obscures parts of the model’s reasoning in the Grok app to prevent distillation attacks that competitors use to extract model knowledge.
Availability and Access Grok 3 is currently available to X Premium Plus subscribers. | |
| Learn more
|
|
|
|
TRENDING SIGNALS
| AI Tool |
|
⇧ 9,473 Likes | |
Custom LLM |
|
⇧ 1,593 Likes | |
AI Tool |
|
⇧ 5,539 Likes | |
LLM Evaluation |
|
⇧ 674 Likes | |
Training Optimization |
|
⇧ 10,475 Likes | | |
|
|
|
|
TOP MODELS
| LLM Fine-tuning |
|
⇧ 30,340 Downloads |
Unsloth is an open-source platform that helps fine-tune large language models like Llama, Phi, Mistral, and more, offering 2x faster performance with up to 80% less memory usage. It supports models for free, with easy-to-use notebooks for quick fine-tuning. Key features include memory-efficient quantization and reasoning capabilities. |
| Model Serving |
| ⇧ 38,330 Downloads |
vLLM is a high-throughput, memory-efficient engine for serving LLMs, offering fast inference with minimal memory usage. It supports advanced features like continuous batching, speculative decoding, and efficient attention management with PagedAttention. vLLM integrates with Hugging Face models, supports various quantizations, and optimizes performance using CUDA kernels and FlashAttention. |
| Agents |
| ⇧ 2,427 Downloads |
Potpie helps you create AI agents specialized in your codebase for tasks like automated debugging, code analysis, and testing. It builds a knowledge graph to understand relationships within the code. It works with any size codebase and supports custom agent creation. Prebuilt agents cover testing, debugging, and code generation. |
| |
| |
|
|
TOP LECTURE
| AI Optimization |
Optimizing AI Reasoning: A Hands-On Guide to GRPO
| ⇧ 3,438 Likes |
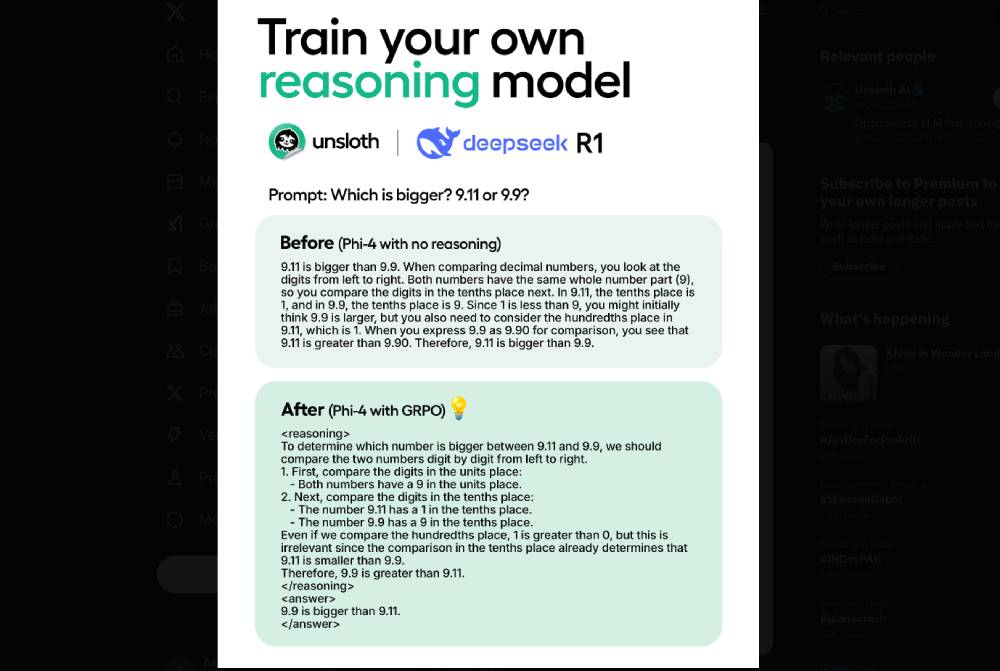
| This blogpost explains how to train your own R1 reasoning model using Unsloth and Group Relative Policy Optimization (GRPO). You’ll learn how GRPO enables models to extend their reasoning time, improving accuracy without human feedback.
You’ll learn:
- How GRPO optimizes responses without a value function, unlike PPO.
- When to use GRPO over standard fine-tuning methods.
- How to train reasoning models locally with as little as 7GB VRAM.
- How to apply GRPO with QLoRA and LoRA.
- Strategies for selecting and rewarding reasoning traces.
- How to transform Llama-3.1 (8B) and Phi-4 (14B) into reasoning models.
- Best practices for training and deploying GRPO-enhanced models.
- Real-world applications of reasoning models in AI.
|
| Read more
|
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
