The bar just got raised twice today. Anthropic ships its most powerful model ever, and Cognition proves it still can't write production-ready code.
That tension is the story. We're getting stronger models while simultaneously learning they score 13/100 on what actually matters: code a real maintainer would merge.
More capability, higher standards. We think that's healthy, actually.
|
|
In Partnership with
|
·
|
|
|
|
|

|
Today's Author
Lior Alexander. Founder of AlphaSignal and former ML Engineer. Previously built ML systems at Iguazio, Guesty, Enphase, Mila.
|
|
Top News
|
|
|
|
Cognition releases coding benchmark where top models score just 13 out of 100
|
|
4,905 Likes
|
|
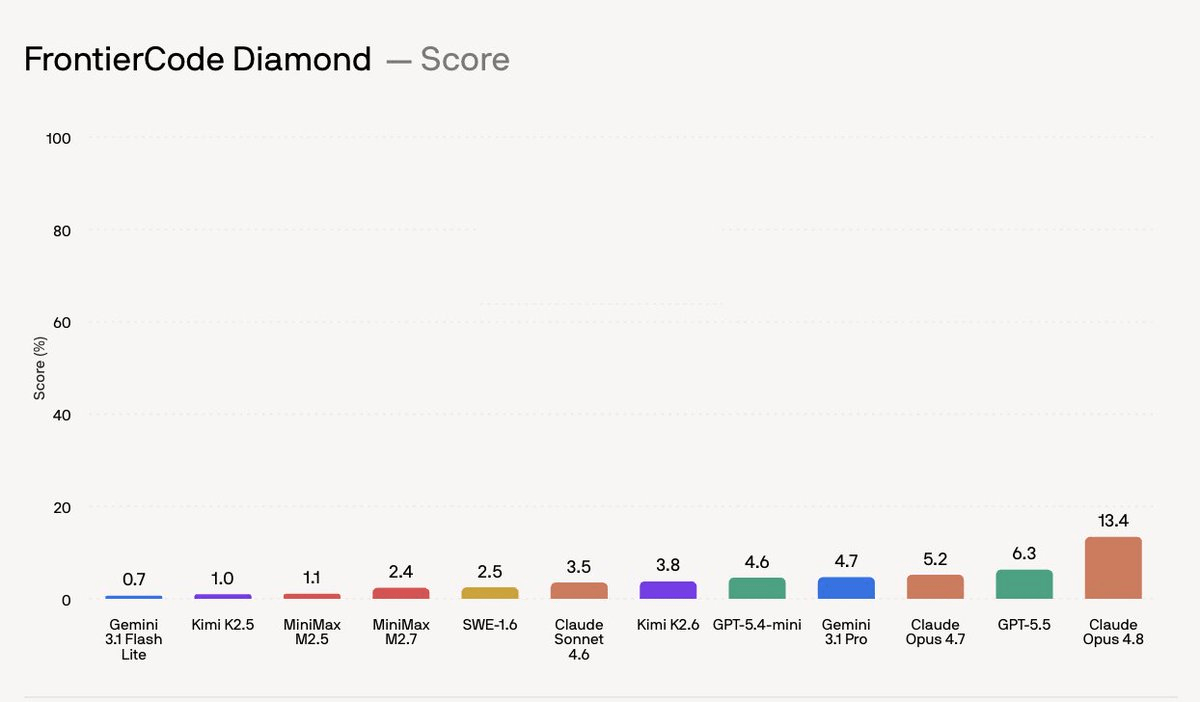
Most AI coding benchmarks ask one question: does the code work? FrontierCode, a new benchmark from Cognition, asks something harder: would a real maintainer actually merge it? That shift matters. AI models have gotten good at writing code that passes tests but is messy, out of scope, or ignores a project's style. FrontierCode catches all of that. Here is what it actually grades: - Correctness, yes, but also test quality and regression safety
- Scope discipline: did the model change only what it needed to?
- Style and adherence to that specific codebase's standards
The tasks were built by maintainers of 36 real open-source repos, each spending 40+ hours per task. It has three tiers: Extended, Main, and Diamond. The results are humbling. On the hardest Diamond set, the top model scores just 13.4 out of 100. It also produces 81% fewer grading errors than SWE-Bench Pro, so the scores you see actually mean something. For you, this is a much more honest signal of whether an AI tool is ready for your real codebase.
|
|
|
|
Presented by Orkes
|
|
Beyond Sandboxes: Build AI Agents That Don't Break
|
|
AI agents often work well in demos but struggle in production when crashes, restarts, and long-running tasks cause them to lose state and execution context. These challenges mirror those encountered during the rise of distributed microservices: handling failures, preserving state, managing retries, and maintaining visibility across complex workflows. Join us on June 11th to learn how durable execution makes AI agents resilient, observable, and production-ready across popular agent frameworks.
|
|
|
|
Top News
|
|
|
|
Anthropic releases Claude Fable 5, its most capable model with built-in safety limits
|
|
4,282 Likes
|

|
Anthropic just dropped Claude Fable 5, the first publicly available model from their powerful Mythos family. Think of Mythos as their most capable AI tier, previously too risky to release widely. Now you can use it. Here's what makes it stand out: - Top of nearly every benchmark, with exceptional results in coding, vision, and scientific research
- The harder and longer the task, the bigger its lead over previous models
- It can rebuild a web app from screenshots alone, and even completed Pokemon FireRed autonomously
- API pricing is $10 per million input tokens, $50 per million output tokens
The catch: sensitive topics like cybersecurity and biology automatically reroute to Claude Opus 4.8 instead. You get notified when that happens. It triggers in less than 5% of sessions, so most of your work is unaffected. Claude Mythos 5 is the same model but with fewer restrictions, currently limited to vetted security partners only. Fable 5 is available to everyone right now.
|
|
|
|
Presented by Datadog
|
|
Ship AI Features Without the Guesswork
|
|
CI pipelines, LLM monitoring, feature flags. Everything you need to ship AI with confidence. Assets on modern AI delivery include: - Product briefs
- eBook
- On-demand webinar
One toolkit, zero guesswork.
|
|
|
|
Top News
|
|
|
|
Google upgrades NotebookLM with agentic chat and advanced multi-step reasoning
|
|
4,193 Likes
|
|
NotebookLM just leveled up. It used to be a smart document reader. Now it acts more like a research partner that actually does work for you. The big idea here is agentic AI, meaning the tool can plan and execute multi-step tasks on its own, without you prompting every single step. Give it a goal, it figures out the path. Here is what is new: - Runs code inside your notebook: each notebook now has a secure cloud computer, so it can write and execute code to crunch data and generate charts on the spot
- Finds its own sources: start with just a loose idea and it crawls the web to build your source library, with your permission
- New export formats: PDF, DOCX, XLSX, PPTX, CSV, JSON, PNG, SVG and more, all downloadable directly
- Powered by Gemini 3.5 with visible step-by-step reasoning so you can see how it thinks
In Google's own tests, the upgrade beat the old system in over 65% of comparisons. Currently rolling out to Google AI Ultra subscribers first.
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We're passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We're based in the United States. By using our site, you agree to be governed by U.S. laws.
|
|
|
Looking to promote your company, product, service, or event to 250,000+ AI developers?
|
|
|
|
|
