| Hey, | Welcome to AlphaSignal – the most read newsletter by AI developers.
We bring you the top 1% of news, papers, models, and repos, all summarized to keep you updated on the latest in AI. |
|
|
|
IN TODAY'S SIGNAL
| Read time: 5 min 37 sec | 🎖️ Top News
📌 Crossing Minds
⚡️ Trending Signals
💻 Top Tutorials
🧠 How To |
|
|
|
If you're enjoying AlphaSignal please forward this email to a colleague.
It helps us keep this content free. |
|
|
|
TOP NEWS
| AI Performance Optimization | DeekSeek AI unveils FlashMLA, an open-source high-performance decoding solution for transformer models
| ⇧ 7,735 Likes |
| What's New |
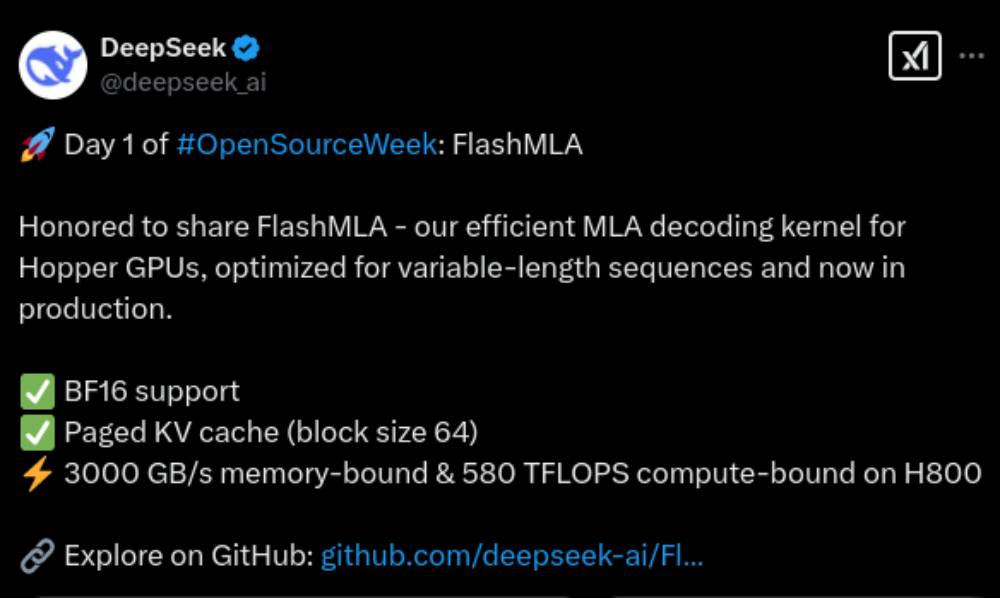
On Day 1 of DeekSeek AI's open source week it announces FlashMLA, an optimized Multi-head Latent Attention (MLA) decoding kernel designed for NVIDIA's Hopper GPUs. It boosts AI inference performance, especially for transformer models with variable-length sequences.
Key Highlights BF16 precision maintains model accuracy while increasing performance.
Paged KV cache (block size 64) enhances memory lookup efficiency.
CUDA 12.6 ensures compatibility with modern GPU features.
Multi-head Latent Attention (MLA)
MLA is a technique used in transformer models to attend to different parts of the input sequence in parallel. This method improves the model’s ability to handle complex dependencies in data, particularly in NLP tasks. FlashMLA optimizes the decoding process for MLA, reducing computational overhead when working with variable-length sequences.
Hopper GPUs
NVIDIA's Hopper GPUs are built for high-performance AI workloads, offering significant improvements in processing power and efficiency. These GPUs include advanced features like Tensor Cores and support for CUDA 12.6, making them ideal for accelerating AI tasks. FlashMLA takes full advantage of these capabilities, optimizing GPU utilization for MLA tasks.
Efficient Variable-Length Sequence Processing
By restructuring memory access patterns, FlashMLA reduces computational overhead when handling dynamic or irregular input sizes. It ensures optimized AI inference without additional compute costs.
Significance of FlashMLA
FlashMLA provides a production-tested solution for AI inference on Hopper GPUs. It improves memory efficiency, reduces computational waste, and improves throughput for transformer-based models. It also enables faster inference speeds without compromising model accuracy, making it relevant for large-scale machine learning applications. |
|
| Try now
|
|
|
|
| Supercharge your LLMs without the complexity of fine-tuning. | Shipping an LLM-based product feature is easy. The hard part is getting it to drive real business impact.
A/B testing your solution with real users lets you know how it’s working, but what do you do with the results?
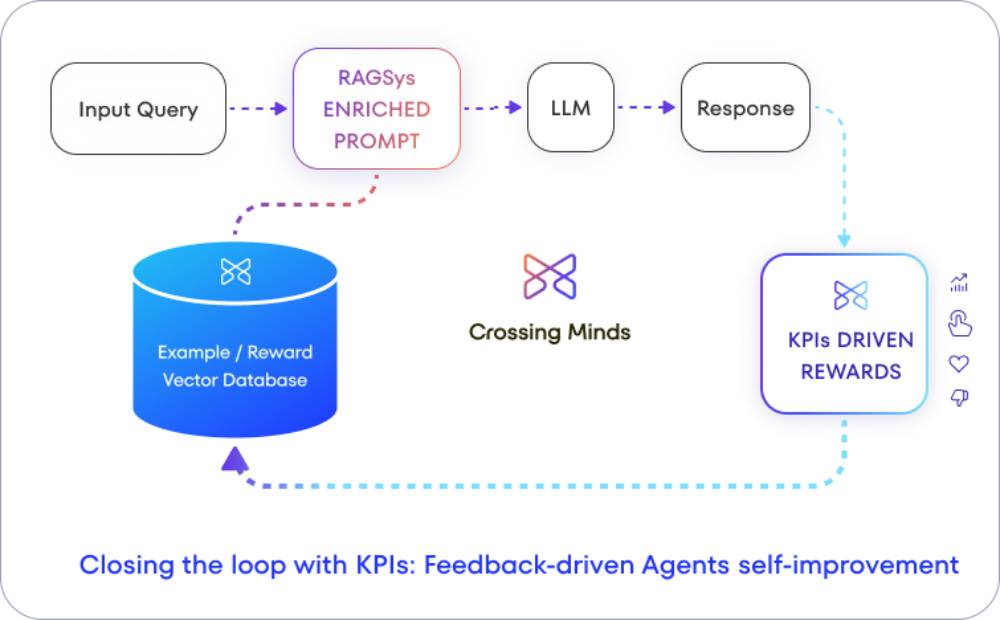
Crossing Minds just released a real-time fine-tuning engine, RAGSys, that lets LLMs adapt and optimize based on feedback.
Unlike traditional RAG, RAGSys introduces:
KPI-optimized retrieval – Prioritizes data that directly impacts business goals.
Live feedback integration – Refines responses continuously based on real-world interactions.
Adaptive knowledge repository – A dynamic, self-improving knowledge base for domain-specific intelligence.
Few-shot learning – Accelerates fine-tuning up to 300x faster by optimizing retrieval instead of retraining LLMs.
Seamlessly integrate with any LLM (OpenAI, Anthropic, open-source) while future-proofing your AI stack.
No more static models. No more guesswork. Align AI output with your key business metrics.
|
| Learn more now
| partner with us → |
|
|
|
TRENDING SIGNALS
| Agent |
|
⇧ 7,424 Likes | |
AI Tool |
|
⇧ 1,946 Likes | |
Vision Language Model |
|
⇧ 1,539 Likes | |
AI Video Editing |
|
⇧ 2,238 Likes | |
AI Document Processing |
|
⇧ 1,245 Likes | | |
|
|
|
|
TOP TUTORIALS
| Agent |
| ⇧ 1,947 Likes |
Learn to build and run an autonomous deep research agent using LangGraph Studio. Configure report structure, planner and writer models, search APIs, and research depth. Compare architectures, explore human-in-the-loop strategies, and evaluate open-source implementations. Analyze costs against paid alternatives. Includes a live demo and breakdown of key system components. |
| Coding Assistant |
| ⇧ 22,469 Likes |
Create and deploy a Brick Breaker game in 3 minutes using Grok-3 and Replit. Learn to generate code, set up a Replit project, and deploy a live game. Requires a Replit account and an X account logged into Grok.com. Includes a step-by-step walkthrough with a final live demo. |
| Document Processing |
| ⇧ 451 Likes |
This tutorial covers transcribing typed text, handwritten notes, and forms with a mix of both. Extract structured text from images and PDFs. Discover Claude 3’s advantage over OCR systems by specifying what to transcribe. See how to convert unstructured information into structured JSON output for easier data processing. |
| |
| |
|
|
HOW TO
| Agents |
Build a Multi-Agent Financial Analyst |
⇧ 1,374 Likes | This guide walks you through setting up CrewAI with SambaNova’s DeepSeek-R1 to analyze stock gains and visualize financial data.
Step 1 Create a .env file and add your SambaNovaAI API key for DeepSeek-Distill-Llama.
Step 2 Integrate CrewAI for multi-agent orchestration. Connect your SambaNovaAI's DeepSeek-R1 LLM for fast inference.
Step 3 Set up a query parser agent to process natural language queries and extract structured data using Pydantic.
Step 4 Set up the code writer agent. This agent generates Python code for stock data visualization with Pandas, Matplotlib, and Yahoo Finance.
Step 5 Use CrewAI's sandbox environment to review and execute the generated Python code.
Now, you can analyze and plot stock gains for any company via a simple query. |
| Github repo
|
|
|
|
At Alpha Signal, our mission is to build a sharp, engaged community focused on AI, machine learning, and cutting-edge language models, helping over 200,000 developers stay informed and ahead. We’re passionate about curating the best in AI, from top research and trending technical blogs to expert insights and tailored job opportunities. We keep you connected to the breakthroughs and discussions that matter, so you can stay in the loop without endless searching. We also work closely with partners who value the future of AI, including employers and advertisers who want to reach an audience as passionate about AI as we are.
Our partnerships are based on shared values of ethics, responsibility, and a commitment to building a better world through technology.Privacy is a priority at Alpha Signal. Our Privacy Policy clearly explains how we collect, store, and use your personal and non-personal information. By using our website, you accept these terms, which you can review on our website. This policy applies across all Alpha Signal pages, outlining your rights and how to contact us if you want to adjust the use of your information. We’re based in the United States. By using our site, you agree to be governed by U.S. laws. |
|
|
|
Looking to promote your company, product, service, or event to 200,000+ AI developers? Let's work together.
|
| Work with us
|
|
|
|
|
