
Alibaba's Qwen3-30B Beats Gemini 2.5 Flash on Math Running on a Laptop
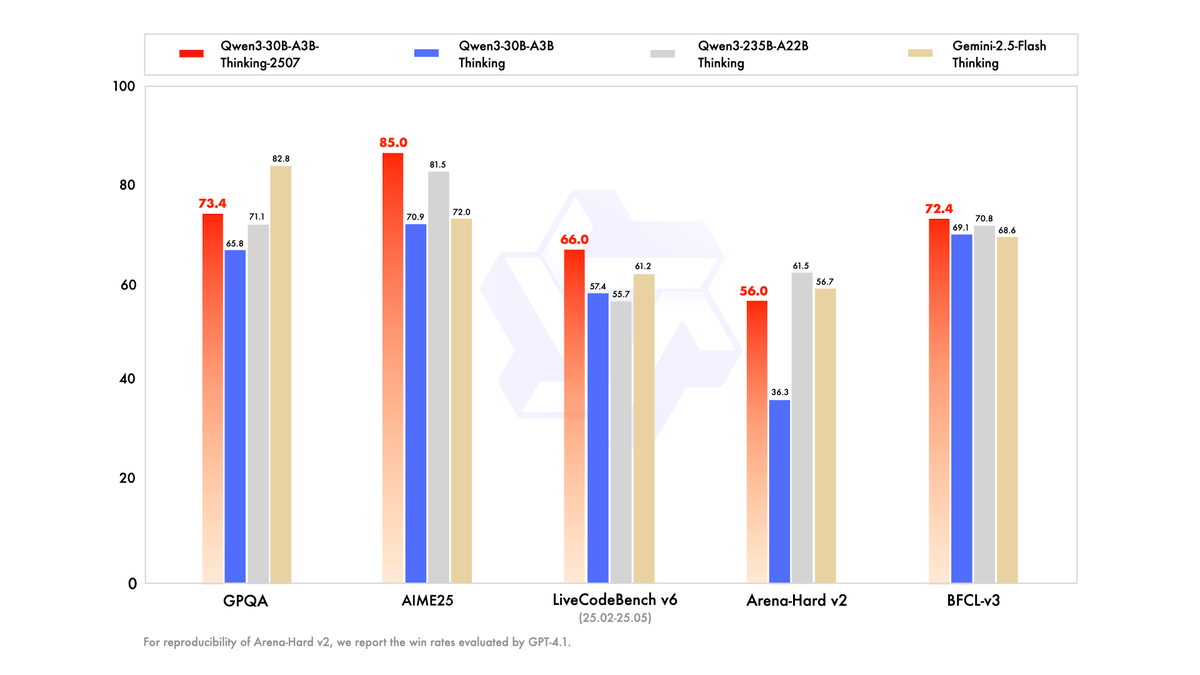
Alibaba's Qwen team releases a pure reasoning MoE with 3.3B active parameters that beats Gemini 2.5 Flash Thinking on AIME25 and LiveCodeBench.
Takeaways
- Alibaba's Qwen team releases Qwen3-30B-A3B-Thinking-2507, a pure reasoning MoE under Apache-2.0.
- 30.5B total parameters, 3.3B active, 128 experts with 8 activated per token, 48 layers.
- Scores AIME25 85.0, HMMT25 71.4, LiveCodeBench v6 66.0, beating Gemini 2.5 Flash Thinking.
- Native 256K context, extendable to 1M tokens via Dual Chunk Attention and MInference.
- Hybrid thinking mode is retired; reasoning and instruct models are now trained separately.
- Runs locally via vLLM, SGLang, Ollama, LM Studio, MLX-LM and llama.cpp with community quantizations.
Alibaba's Qwen team has released Qwen3-30B-A3B-Thinking-2507, a dedicated reasoning model that separates the thinking pathway from the instruction-following one. It ships under Apache-2.0 with weights and configs on Hugging Face, and the community has already flooded the ecosystem with GGUF, AWQ, FP8, and FP4 quantizations for local inference.
The headline claim: a Mixture-of-Experts with only 3.3B active parameters can match or beat much larger reasoning models on math, code, and agentic benchmarks, while still fitting on a single high-memory consumer or workstation GPU.
What's actually in the box
Qwen3-30B-A3B-Thinking-2507 is the latest thinking checkpoint in the Qwen3 series. The MoE has 30.5 billion total parameters and 3.3 billion active, aimed at complex tasks. Architecturally, it runs 48 layers, grouped-query attention with 32 query heads and 4 key/value heads, and 128 experts with 8 activated per token.
One notable design shift: the hybrid thinking toggle is gone. Alibaba also released Qwen3-235B-A22B-Instruct-2507, which replaces the older combined model, and going forward instruction and thinking variants will be trained separately to improve quality. The 30B checkpoint follows the same split: it only produces reasoning traces, and the enable_thinking flag no longer exists. The chat template automatically injects a <think> tag, which is why outputs may contain only the closing </think>.