Quantization
Subtopic of GPUs
About
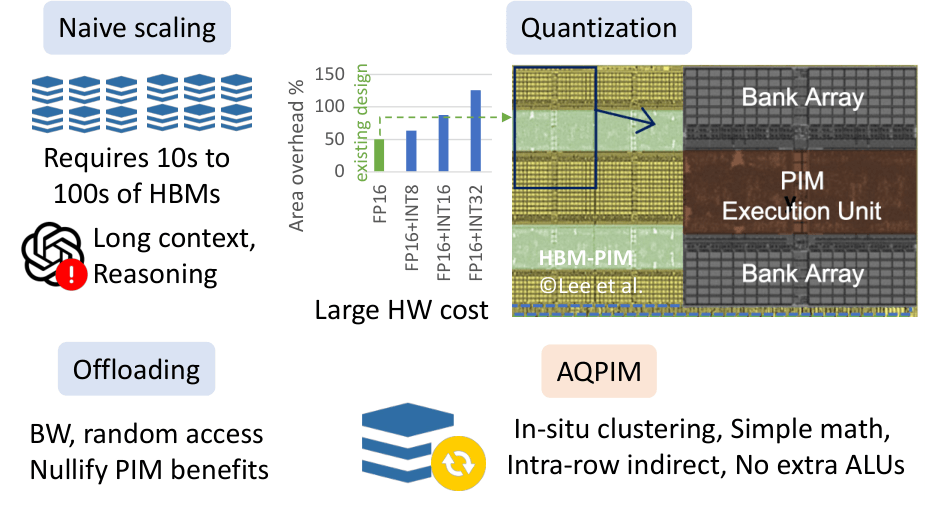
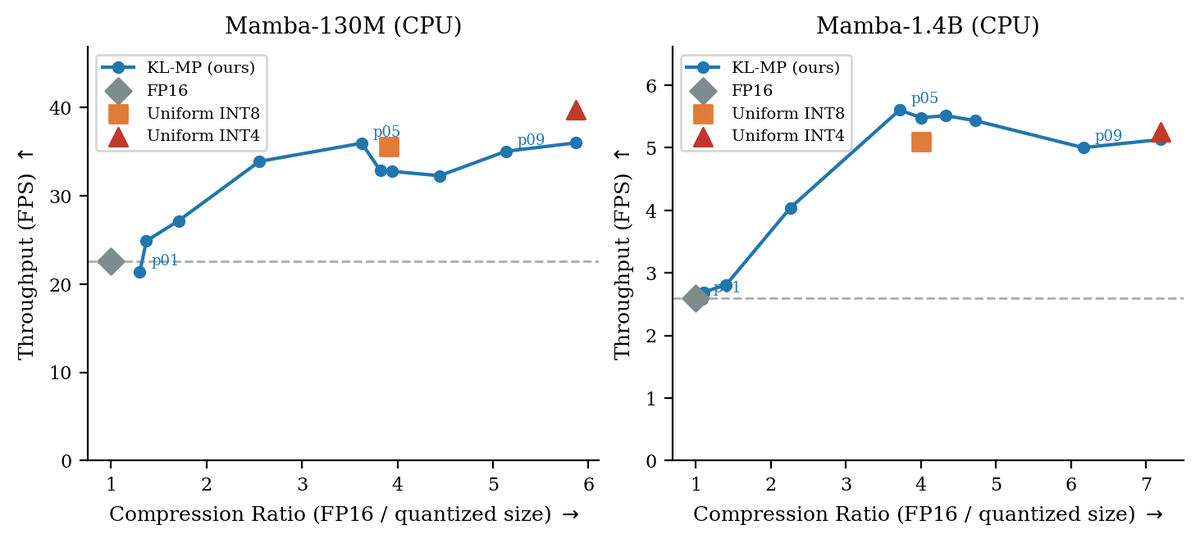
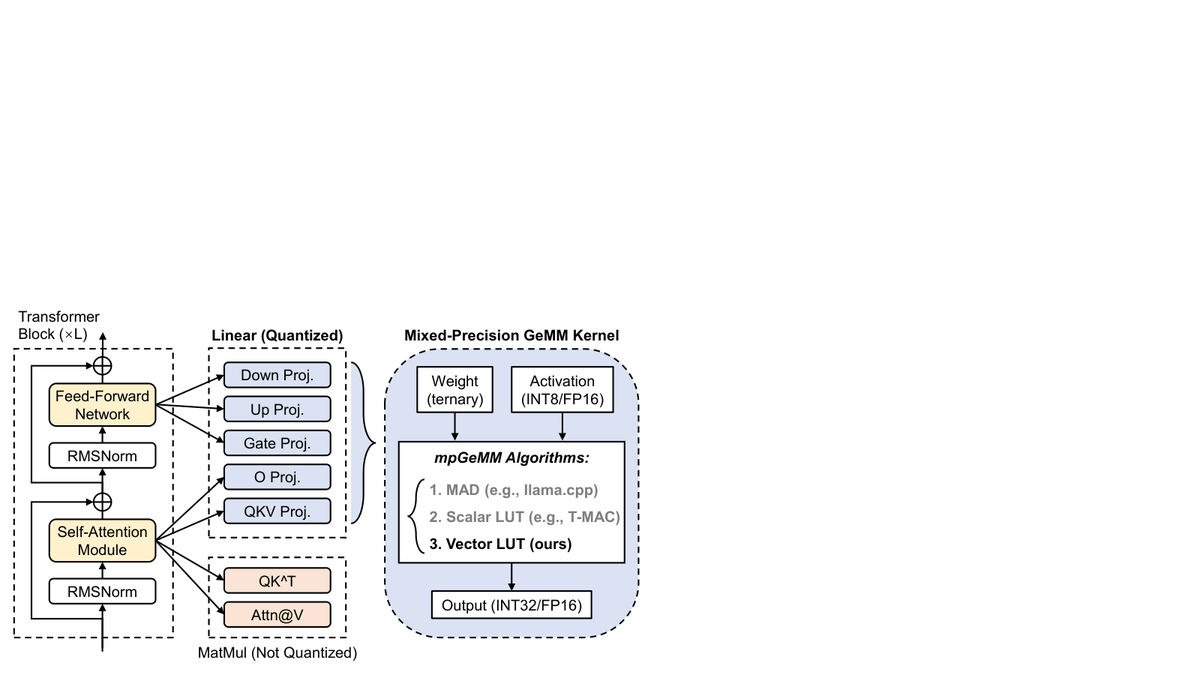
Shrinking models so they run faster and on cheaper hardware. Quantization stores a model's numbers with fewer bits, such as 8 or 4 instead of 16, cutting memory and speeding up responses. The challenge is keeping the smaller model nearly as accurate as the original, and it's how large models end up on laptops and phones.
Activity
2026
119 stories so far in 2026
| Month | Stories |
|---|---|
| January | 0 |
| February | 0 |
| March | 0 |
| April | 11 |
| May | 1 |
| June | 20 |
| July | 4 |
| August | 6 |
| September | 10 |
| October | 32 |
| November | 35 |
| December | 0 |
Part of
Top companies
119 stories