
audio.cpp Ships 60+ Audio Models in GGUF Running 5x Faster Than Python
A ggml-powered C++ engine brings dozens of TTS, ASR, and voice-conversion models to portable GGUF weights, running up to 5x faster than PyTorch.
Takeaways
- audio.cpp-gguf collects 60+ GGUF-converted audio models for the ggml-based audio.cpp runtime.
- Covers TTS, ASR, voice cloning, source separation, diarization, and music generation in one C++ engine.
- Reports 1.8x-5.0x speedups over Python references, with 45%-80% less end-to-end wall time on CUDA.
- PocketTTS reaches 31x realtime one-shot; Kokoro TTS reports 52x realtime on long-form input.
- Backends include CPU, CUDA, Vulkan, and Metal; server exposes OpenAI-style speech and transcription endpoints.
- Quantization saves VRAM (about 25% on Qwen3-TTS Q8_0) but can degrade quality on some model families.
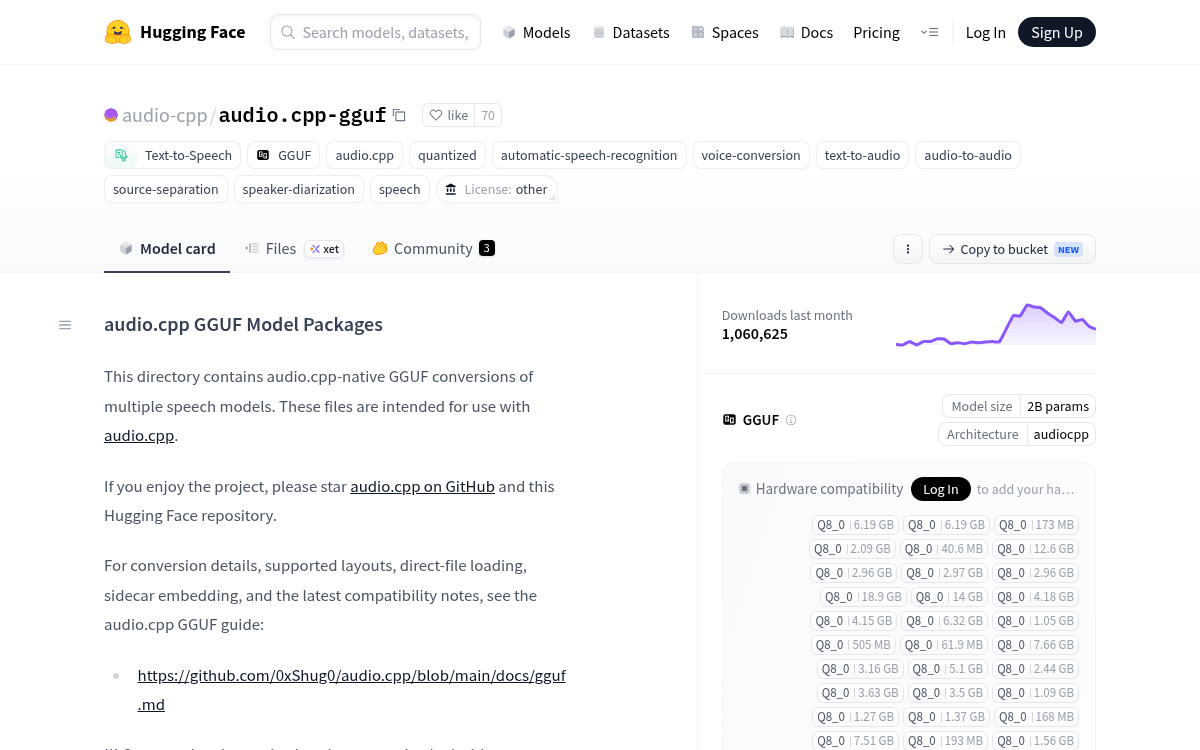
The GGUF format that made local LLMs practical is coming for audio. audio.cpp, a ggml-based inference engine, just shipped a companion Hugging Face repository containing pre-converted GGUF weights for more than 60 speech, music, and audio models, spanning text-to-speech, ASR, voice cloning, diarization, and source separation. The repo has already crossed a million downloads, which suggests real hunger for a llama.cpp-style stack in the audio world.
One runtime, many audio tasks
audio.cpp is described as an all-in-one, pure C++ inference engine for audio models, built on ggml with no Python dependency. Rather than shipping a separate demo per model family, it unifies TTS, STT, VAD, voice conversion, source separation, forced alignment, diarization, and music generation behind a single CLI and server binary. The same runtime powers voice cloning, codec models, and higher-level workflows through a common framework surface.
The GGUF repository is where this becomes concrete. It contains audio.cpp-native conversions of dozens of speech models, intended for direct use with the runtime. Notable families in the collection include:
- Qwen3-TTS and Qwen3-ASR (0.6B and 1.7B), plus a Qwen3 forced aligner
- Chatterbox, VoxCPM2, VibeVoice, PocketTTS, MioTTS, MOSS-TTS, Higgs Audio v3