
DeepSeek Quietly Drops V3-0324 With MIT License and 20-Point Math Jump
DeepSeek quietly drops a major V3 update with near-reasoning-model math scores, MIT license, and 1M+ downloads on Hugging Face
Takeaways
- DeepSeek released V3-0324 with no announcement; discovered by the community and now has 1M+ Hugging Face downloads.
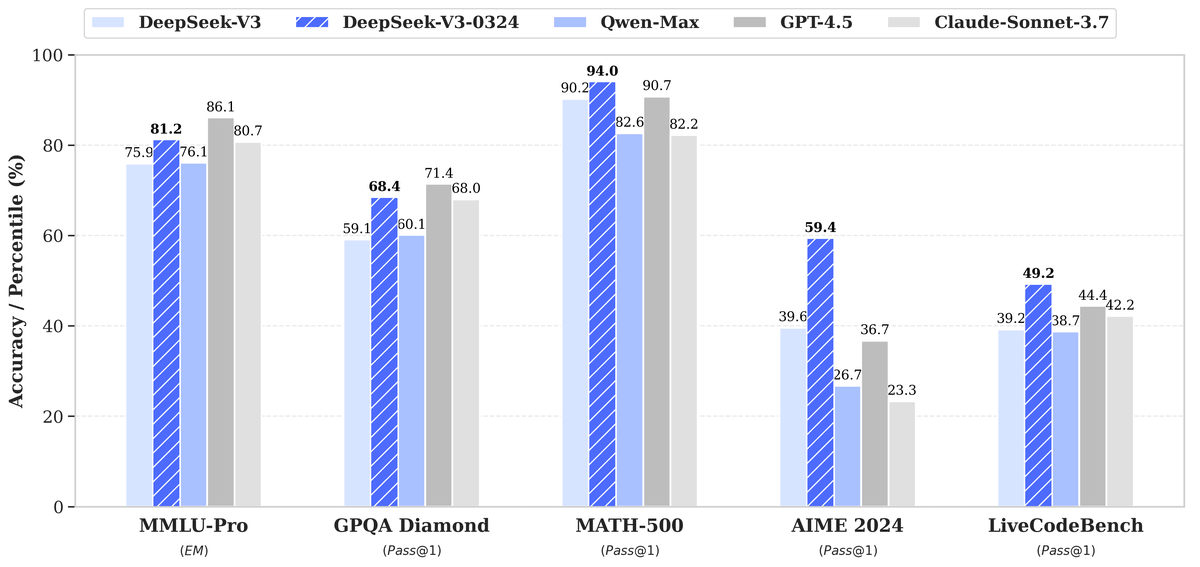
- AIME math score jumped +19.8 points (39.6 → 59.4), rivaling dedicated reasoning models without chain-of-thought inference.
- Same 671B MoE architecture as V3, but post-training was overhauled using RL techniques borrowed from DeepSeek-R1.
- Now MIT licensed, making it fully permissive for commercial use for the first time.
- API pricing starts at $0.21/1M tokens via DeepInfra; also available on OpenRouter, Azure, and Novita.
- Limitations include no native Transformers support, heavy VRAM requirements for self-hosting, and noted content censorship behavior.
DeepSeek-V3-0324 landed on Hugging Face with no press release, no blog post, and no fanfare. On March 24, 2025, DeepSeek quietly uploaded a new model checkpoint to public repositories. No formal announcement accompanied the release. The update emerged through community discovery and rapidly circulated through AI development circles. That low-key style is becoming a signature move for a lab that keeps punching above its weight.
The license is MIT, which is new: the previous DeepSeek V3 had a custom license. That alone is a meaningful shift for teams that need permissive terms for commercial deployment. The model has since crossed 1 million downloads on Hugging Face.
Same bones, sharper brain
The model structure of DeepSeek-V3-0324 is exactly the same as DeepSeek-V3. What changed is everything under the hood of post-training. While it uses the same base model as DeepSeek-V3, the post-training pipeline has been improved, drawing lessons from the reinforcement learning technique in DeepSeek-R1. This allows the new model to have better reasoning performance, coding skills, and tool-use capabilities.
The benchmark jumps are hard to ignore:
- AIME (competition math): 39.6 → 59.4 (+19.8 points)
- GPQA (graduate-level science): 59.1 → 68.4 (+9.3 points)
- LiveCodeBench (real-world coding): 39.2 → 49.2 (+10.0 points)
- MMLU-Pro (broad knowledge): 75.9 → 81.2 (+5.3 points)
In math and coding evaluations, DeepSeek-V3-0324 even outperforms GPT-4.5. The AIME jump of nearly 20 points is particularly striking for a non-reasoning model, meaning one that does not use extended chain-of-thought at inference time.
The architecture powering it
DeepSeek-V3 is a Mixture-of-Experts (MoE) language model with 671B total parameters with 37B activated for each token. To achieve efficient inference and cost-effective training, it adopts Multi-head Latent Attention (MLA) and DeepSeekMoE architectures. MoE means the model routes each token through only a small subset of its parameters, keeping compute costs manageable despite the enormous total size.