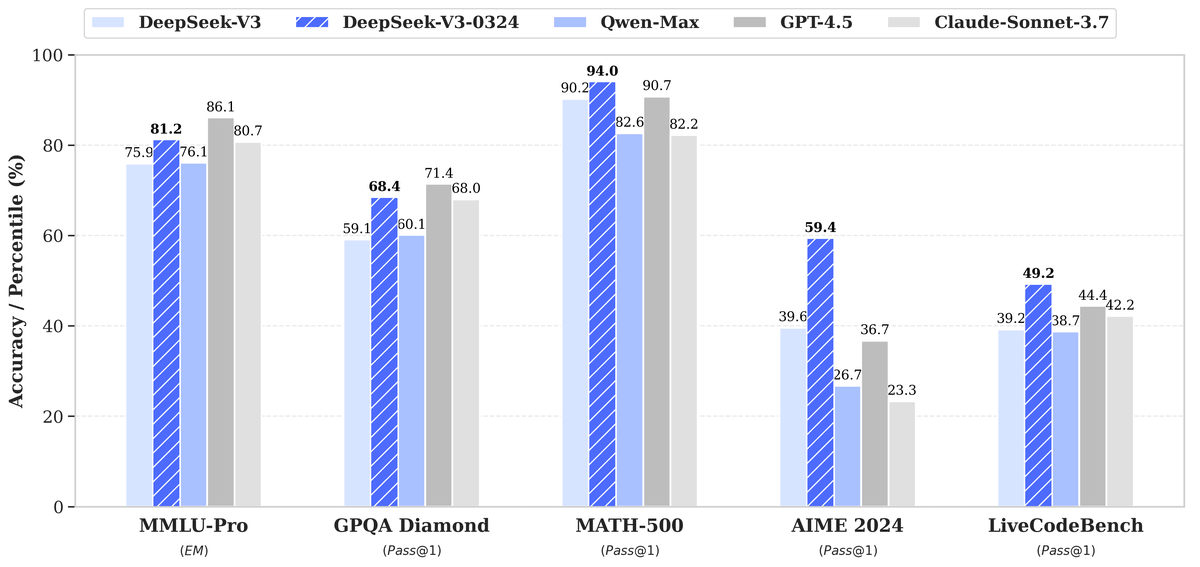
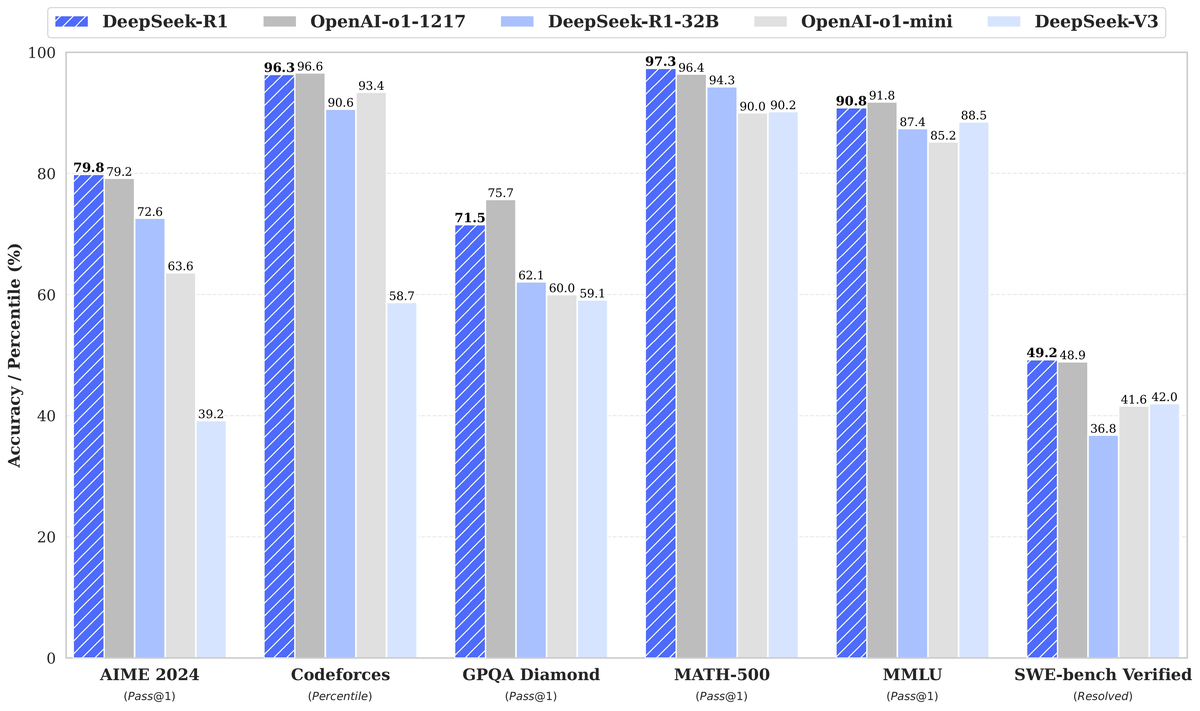
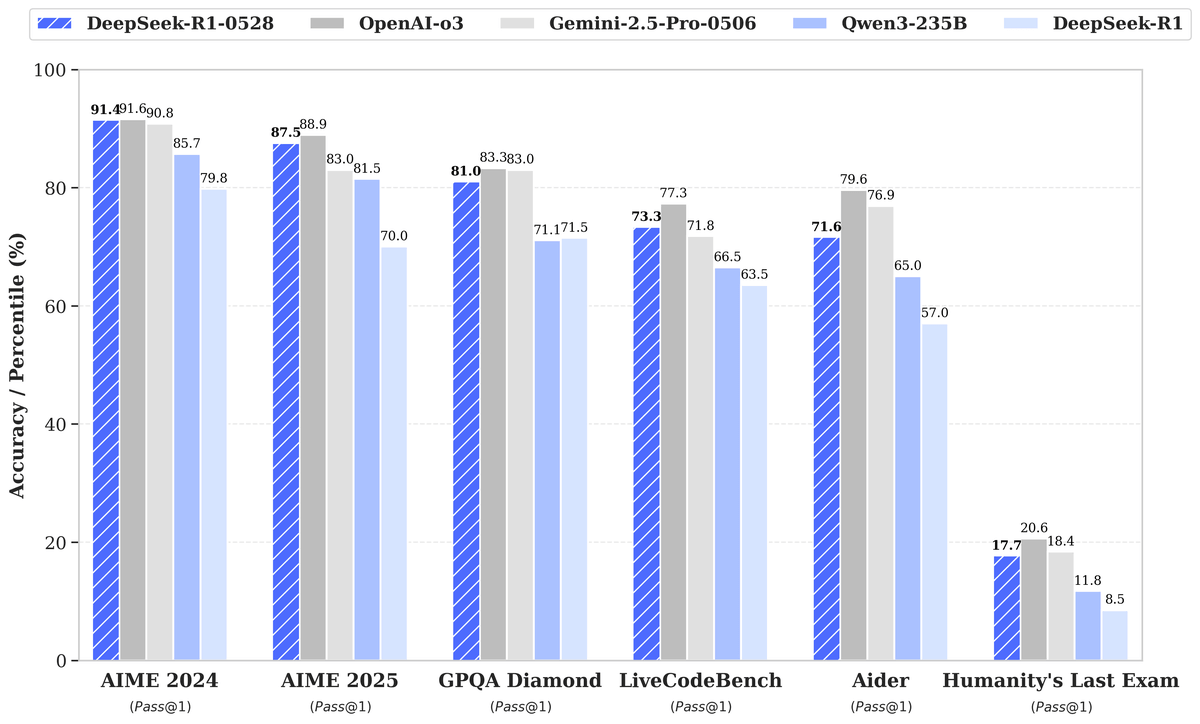
Chinese AI lab building open-weight LLMs under the DeepSeek-V and R1 model families. Uses sparse MoE architectures, pure reinforcement learning for reasoning (no SFT on R1-Zero), and GRPO. V4 Pro runs 1.6T parameters with 49B active. Models release under MIT License with frontier-competitive benchmark performance at significantly lower training cost.
DeepSeek quietly open sourced the research prototype behind its internal coding super-agent, a repository-scoped assistant built to minimize human attention.
DeepSeek open-sourced DeepInfer and deepseek-recipe, the production stack powering DeepSeek-V4.1-Flash, bringing their internal serving optimizations and API parity to anyone.
DeepSeek's 552B mixture-of-experts model splits input and output compute asymmetrically, natively handles vision, and undercuts its own flagship on price.
DeepSeek open-sourced dsh, a plugin-based coding agent framework where the model, tools, sandbox, UI, and even the agent loop itself are all swappable.
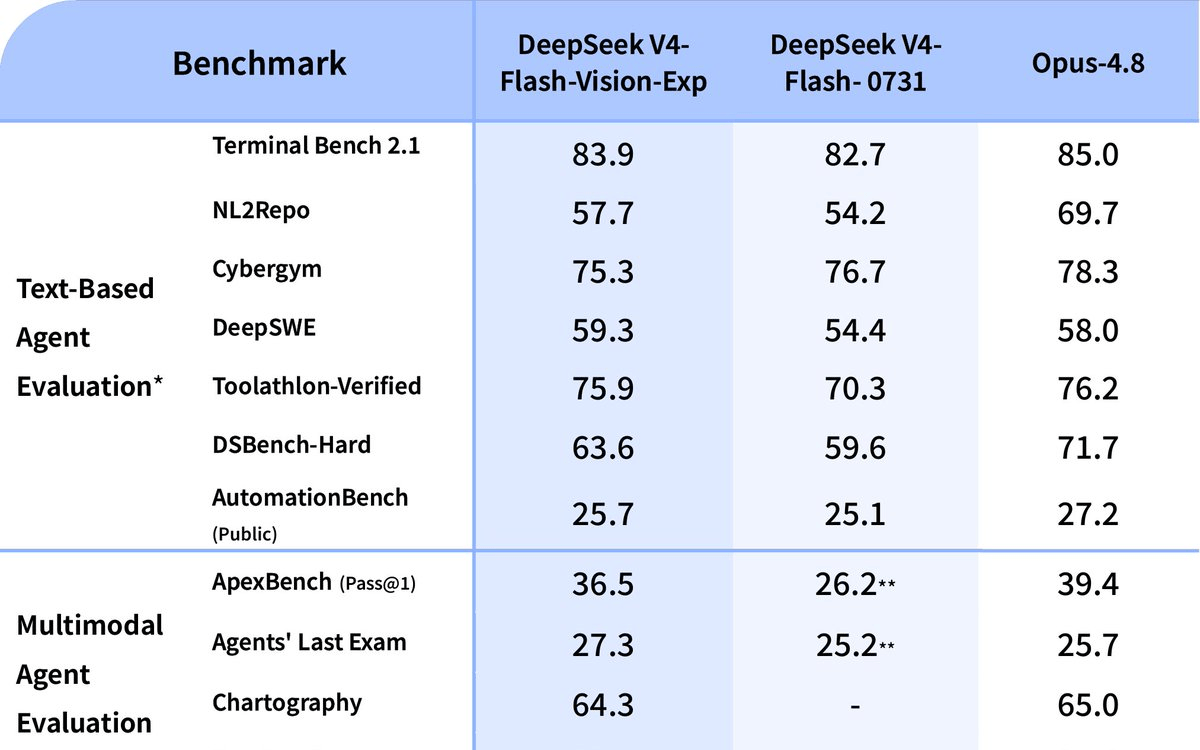
DeepSeek's new experimental vision model bolts image understanding onto V4-Flash at the same price, closing in on Claude Opus 4.8 on multimodal agent tasks.
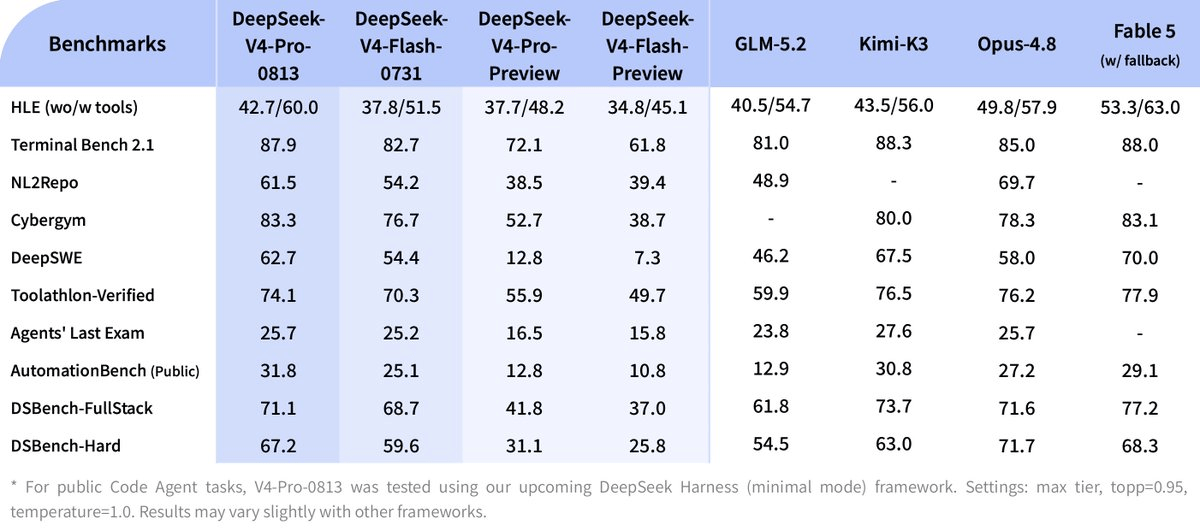
DeepSeek-V4-Pro exits four months of preview with major agent upgrades, flexible reasoning modes, and native OpenAI Responses API support for Codex workflows
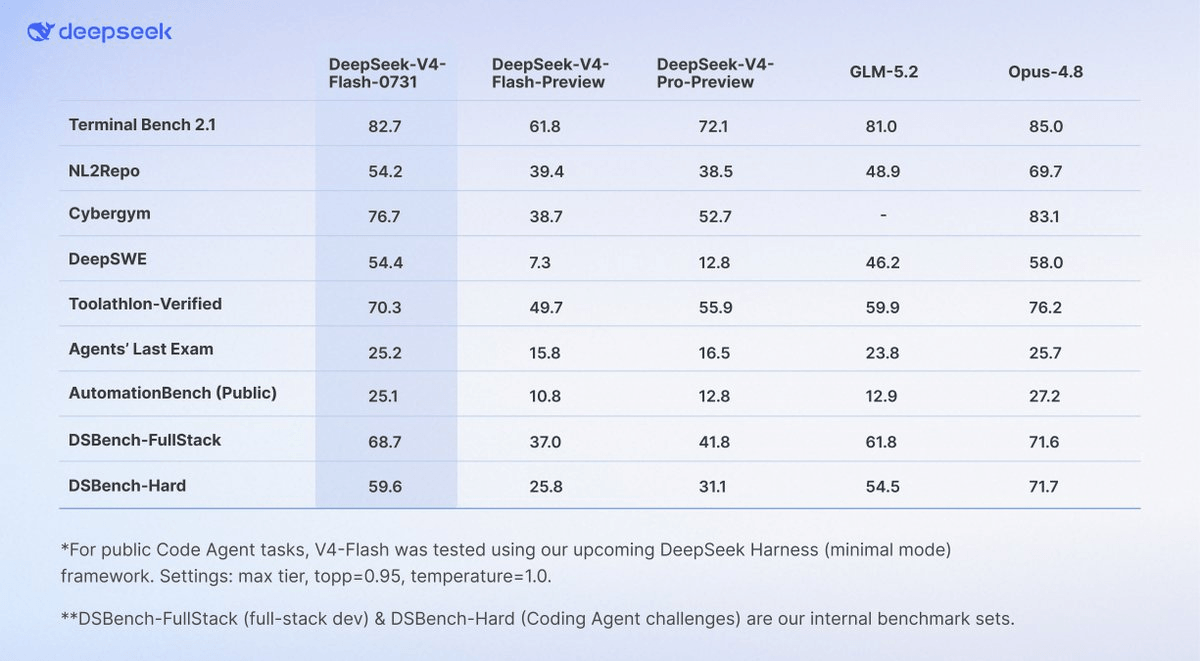
DeepSeek-V4-Flash exits preview with massively upgraded agent skills, native Responses API support, and Codex integration — same price, same architecture, much better performance.
DeepSeekMath-7B-Instruct brings near-GPT-4 math reasoning to a 7B open-source model using a novel RL algorithm that's now reshaping how reasoning models are trained.
DeepSeek Coder 6.7B base is a fully open-source code model that matches CodeLlama-34B performance at a fraction of the size, running on consumer hardware.
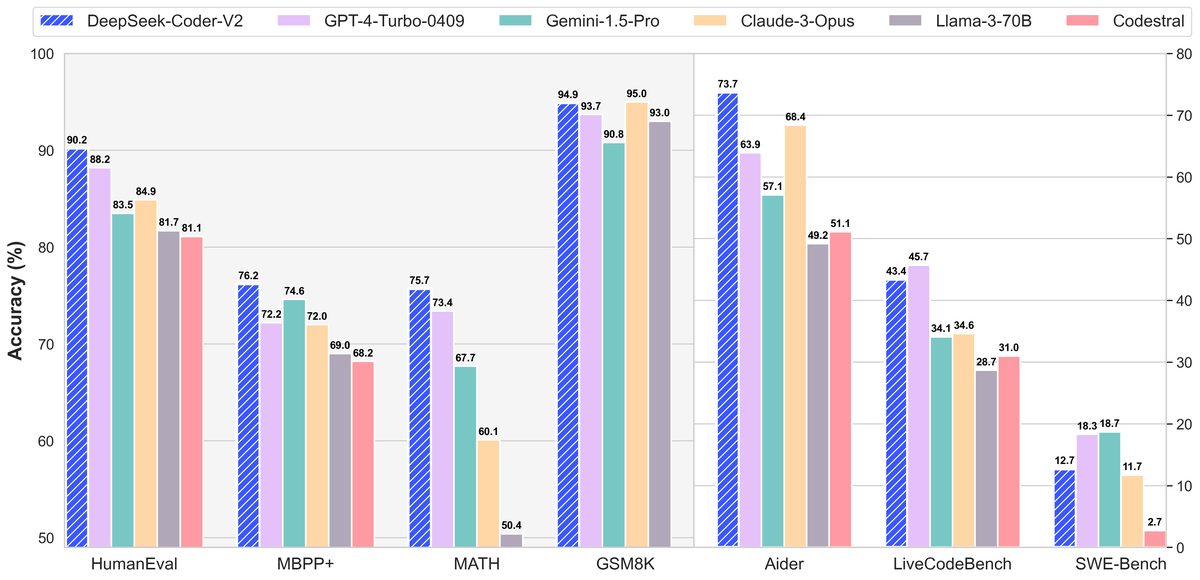
DeepSeek releases a refined 236B MoE coding model with function calling, FIM completion, and GPT-4-Turbo-level benchmark scores — open-source and commercially licensed
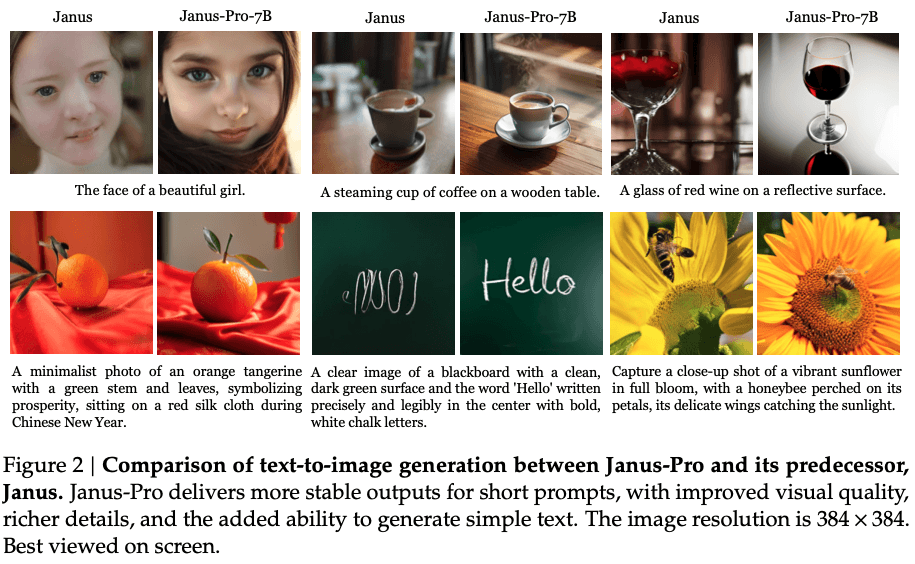
DeepSeek's Janus-Pro-7B unifies image understanding and generation in one open-weight model, beating DALL-E 3 on text-to-image benchmarks with a novel decoupled visual encoder design.
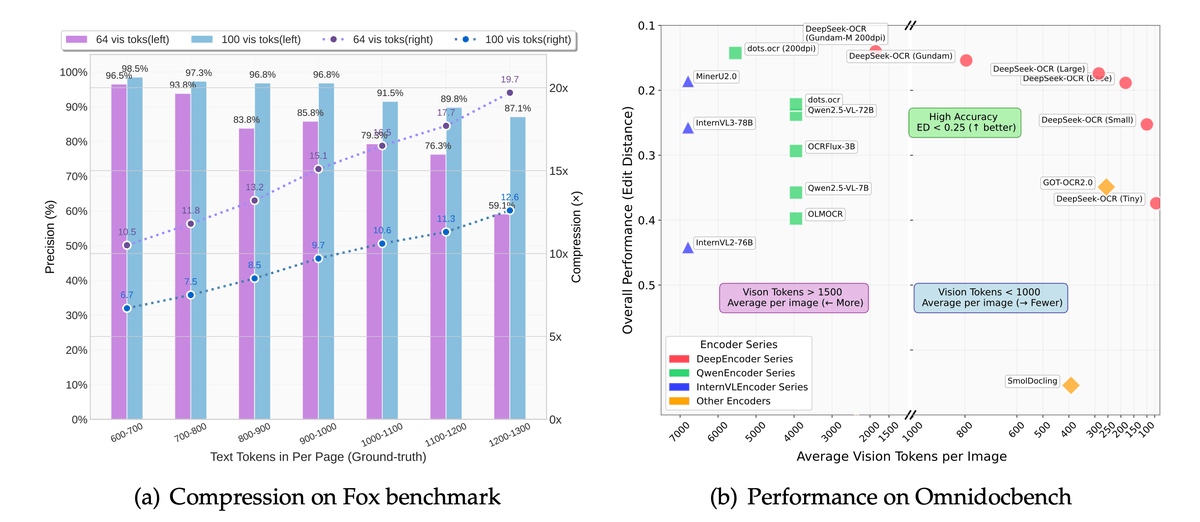
DeepSeek-OCR compresses document pages into as few as 100 vision tokens, hitting 97% OCR precision while processing 200k+ pages per day on a single GPU.
DeepSeek open-sources DeepSpec, a full-stack toolkit for training and evaluating speculative decoding draft models, alongside the DSpark algorithm paper
DeepSeek's open-source CUDA kernel library gets Mega MoE, FP8×FP4 GEMM, and a fused MoE mega-kernel that overlaps NVLink comms with tensor core compute
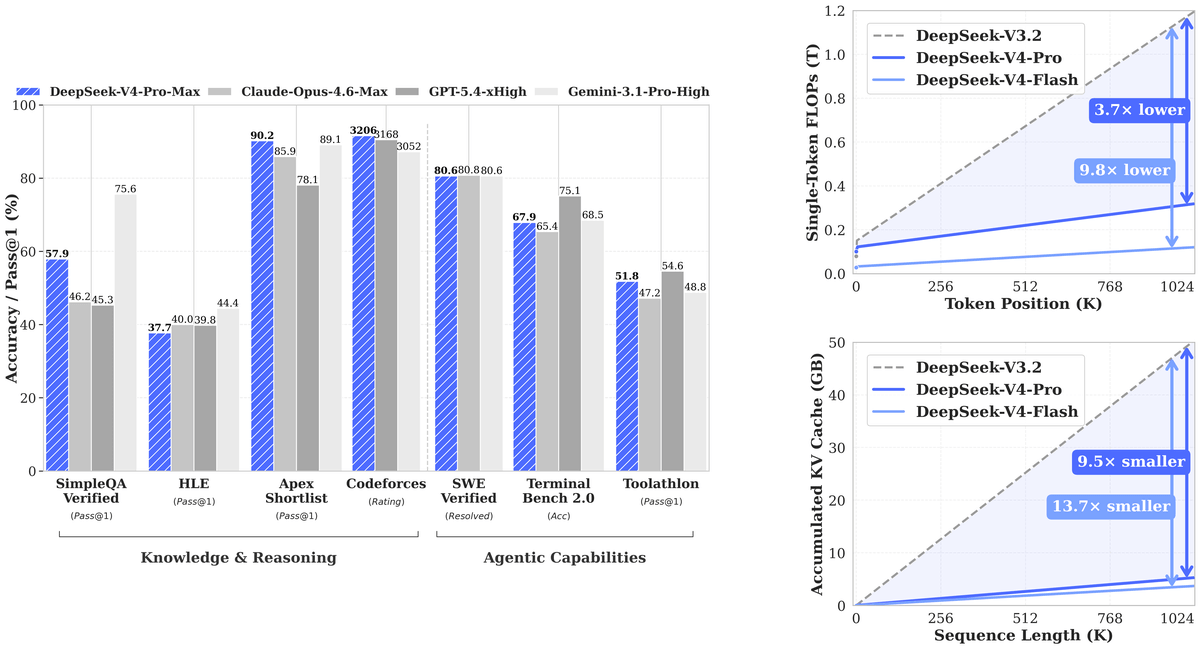
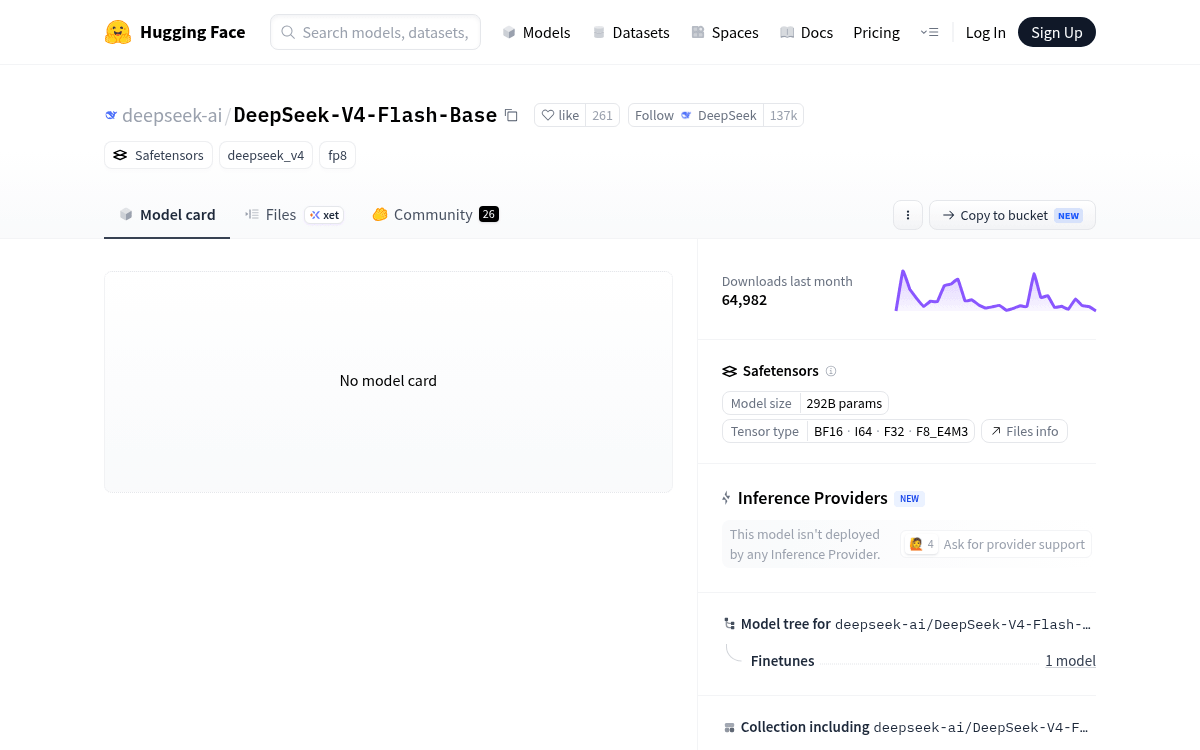
DeepSeek releases V4-Flash-Base, a 284B open-weight MoE model with 1M-token context and a new hybrid attention architecture that slashes inference costs