
DeepSeek Quietly Upgrades Its Open-Source Coder V2 to Match GPT-4o
DeepSeek releases a refined 236B MoE coding model with function calling, FIM completion, and GPT-4-Turbo-level benchmark scores — open-source and commercially licensed
Takeaways
- What: DeepSeek releases DeepSeek-Coder-V2-Instruct-0724, a refined 236B MoE coding model with 21B active parameters.
- Architecture: Built on DeepSeekMoE, continued pre-training from DeepSeek-V2 with 6 trillion additional tokens for coding and math.
- Capabilities: Supports 338 programming languages, 128K context, function calling, JSON output mode, and FIM (fill-in-the-middle) completion.
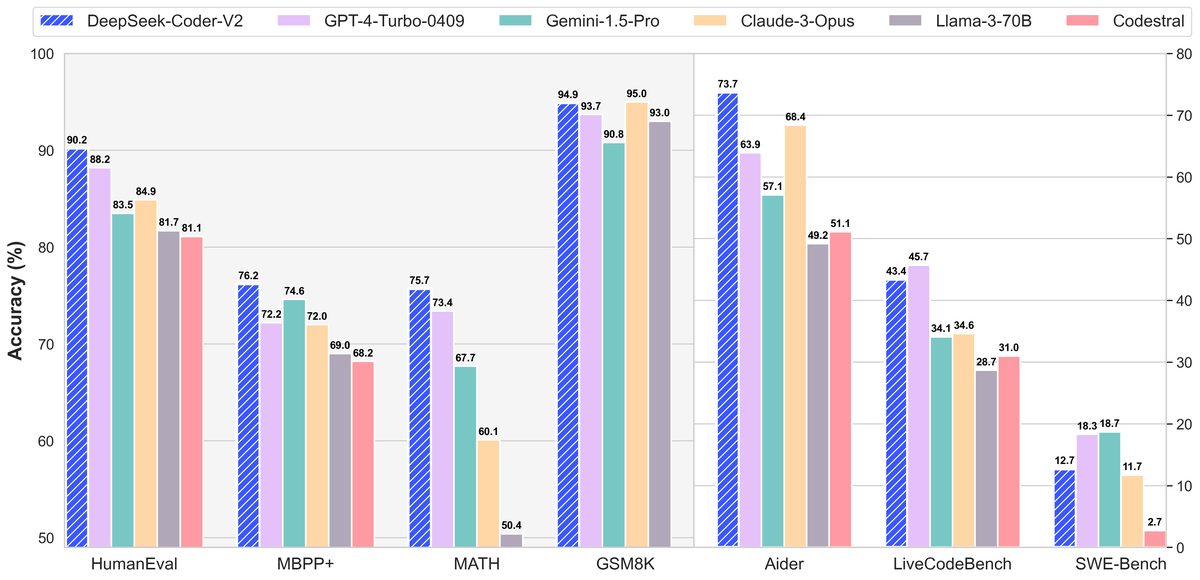
- Benchmarks: Matches GPT-4-Turbo on code tasks; ties GPT-4o on LiveCodeBench at 43.4%; 75.7% on MATH benchmark.
- Hardware: Full 236B model needs 80GB×8 GPUs; the 16B Lite variant runs locally with quantization via Ollama or llama.cpp.
- Lineage: Later merged into DeepSeek-V2.5; for new projects, DeepSeek V4-Flash is the current recommended API model.
DeepSeek-Coder-V2-Instruct-0724 is a refreshed checkpoint of DeepSeek's flagship open-source coding model, quietly dropped as a direct upgrade to the deepseek-coder API endpoint. The "0724" suffix is simply the date stamp , a convention DeepSeek uses to signal a mid-cycle improvement over the base release without bumping the major version number. If you were already calling the deepseek-coder API, you were automatically routed to this version the day it launched.
The update further enhanced code generation capabilities based on the original Coder model, optimizing for common programming application scenarios. It sits on top of the same architecture as the original Coder V2, but with additional fine-tuning passes that sharpen instruction-following and real-world coding performance.
A 236B Model That Only Runs 21B at a Time
DeepSeek-Coder-V2 is an open-source Mixture-of-Experts (MoE) code language model that achieves performance comparable to GPT4-Turbo in code-specific tasks. MoE (Mixture-of-Experts) is an architecture where the model is divided into many specialized sub-networks called "experts," and only a small subset of them are activated for any given token , making inference far cheaper than the total parameter count suggests.
DeepSeek released the V2 with 16B and 236B parameters based on the DeepSeekMoE framework, with active parameters of only 2.4B and 21B respectively. That sparsity is the whole point of the architecture , the full 236B model only fires 21B parameters per token, so inference cost scales with active parameters rather than the total.
DeepSeek-Coder-V2 is further pre-trained from an intermediate checkpoint of DeepSeek-V2 with an additional 6 trillion tokens. Through this continued pre-training, it substantially enhances the coding and mathematical reasoning capabilities of DeepSeek-V2, while maintaining comparable performance in general language tasks.