
DeepSeek's V4-Pro Drops 1.6T Open-Weight Model at 12x Below GPT-5 Pricing
DeepSeek's 1.6T-parameter open-weight model tops coding benchmarks and cuts long-context inference costs by 90%, under an MIT license.
Takeaways
- DeepSeek-V4-Pro is a 1.6T-parameter open-weight MoE model with a 1M-token context window, released under the MIT license.
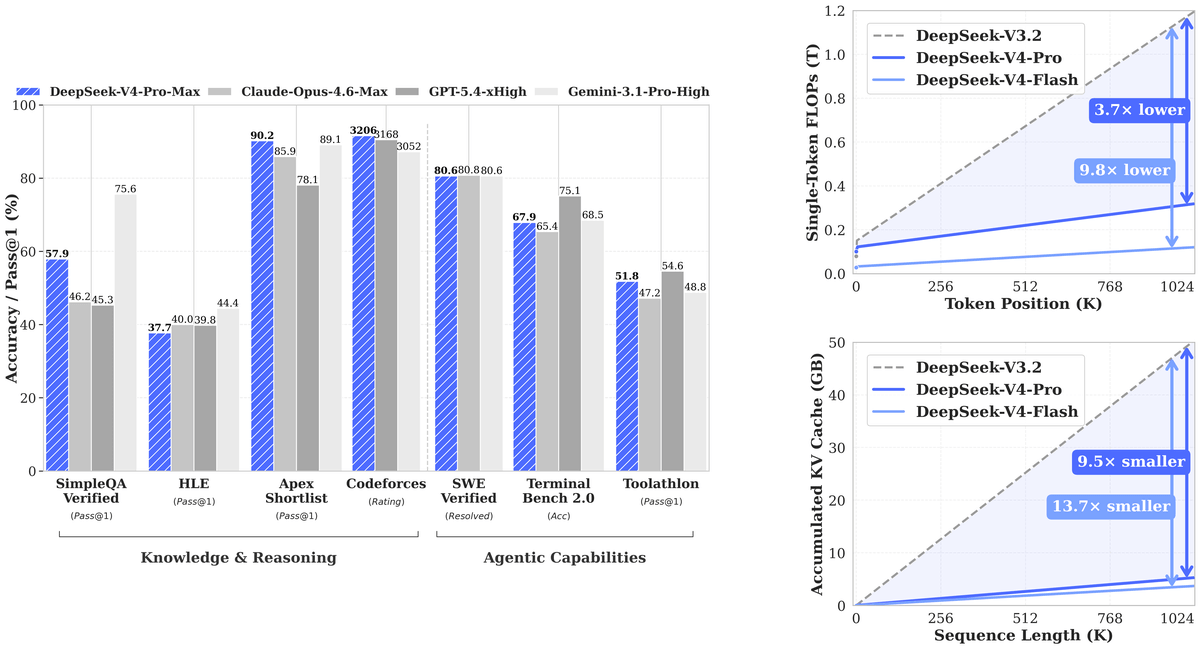
- A new hybrid attention design (CSA + HCA) cuts long-context inference to 27% of FLOPs and 10% of KV cache vs. DeepSeek-V3.2.
- V4-Pro-Max scores 93.5% on LiveCodeBench and 3206 on Codeforces, the highest among all evaluated models including GPT-5.4 and Gemini 3.1 Pro.
- Pricing is $0.435/M input and $0.87/M output tokens — roughly 12x cheaper than GPT-5.5 — with free chat at chat.deepseek.com.
- Known weaknesses: 94% hallucination rate on unknown-answer tasks and a regression in creative writing quality vs. V3.2.
- Weights are freely available on Hugging Face and the technical report is on arXiv.
DeepSeek-V4-Pro is here, and it is the most ambitious open-weight model release since DeepSeek-V3 rattled the industry. With 1.6 trillion total parameters, a native one-million-token context window, and an MIT license, it lands squarely in the territory previously occupied only by closed-source frontier labs. The headline claim from DeepSeek: V4-Pro-Max is the best open-source model available today.
What just shipped
DeepSeek presents two strong Mixture-of-Experts language models: DeepSeek-V4-Pro with 1.6T parameters (49B activated) and DeepSeek-V4-Flash with 284B parameters (13B activated), both supporting a context length of one million tokens. The weights are open, the license is MIT, and both models are live on the API, the web, and the mobile app right now.
MoE (Mixture-of-Experts) means that despite the enormous total parameter count, only a fraction of the network is active for any given token. V4-Pro is a large-scale MoE model with 1.6T total parameters and 49B activated parameters, designed for advanced reasoning, coding, and long-horizon agent workflows, with strong performance across knowledge, math, and software engineering benchmarks.
The architecture changes that actually matter
The biggest architectural story is not the scale, it is the efficiency. DeepSeek redesigned how attention works at long context lengths, and the numbers are striking. V4-Pro introduces a hybrid attention architecture combining Compressed Sparse Attention (CSA) and Heavily Compressed Attention (HCA). At 1M-token context, it requires only 27% of single-token inference FLOPs and 10% of KV cache compared to DeepSeek-V3.2.
To understand why that matters: the KV cache is the memory structure that stores all past tokens so the model can attend to them. At one million tokens, this cache becomes the dominant cost of inference. Cutting it to 10% of the prior generation's footprint is what makes a million-token context window economically viable rather than a theoretical curiosity.