
Unsloth's Qwen3.6-35B-A3B Fits on One GPU and Runs 1.79x Faster
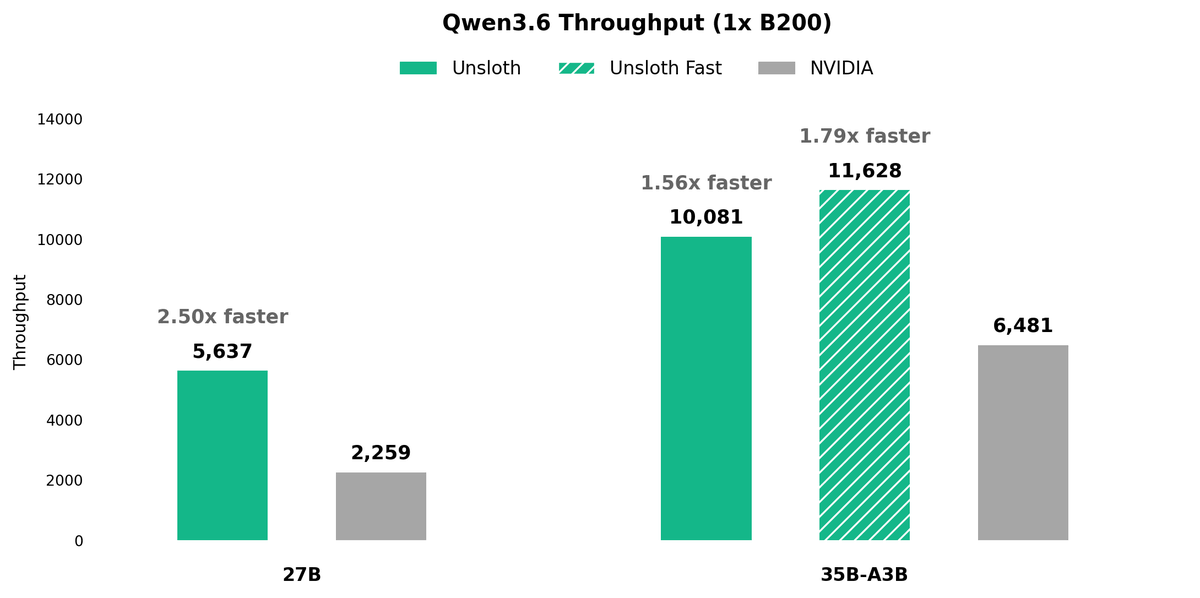
Unsloth's Dynamic NVFP4 quant runs Qwen3.6-35B-A3B up to 1.79x faster on 32GB Blackwell GPUs while matching BF16 accuracy on MMLU-Pro, GPQA, and AIME.
Takeaways
- Unsloth released Dynamic NVFP4 quants of Qwen3.6-35B-A3B in two variants: standard and Fast
- Fast variant hits 1.79x throughput on B200; standard hits 1.56x with slightly better accuracy
- Both fit in 32 GB VRAM and use true W4A4 running on Blackwell FP4 tensor cores
- MMLU-Pro, GPQA, and AIME 2025 scores stay within noise of BF16 baseline
- Requires Blackwell hardware (RTX 50, DGX Spark, B200/B300); vLLM 0.25+ recommended
- Base Qwen3.6-35B-A3B scores 73.4 on SWE-bench Verified with 262K context
Unsloth just shipped a 4-bit NVFP4 version of Alibaba's Qwen3.6-35B-A3B that squeezes the mixture-of-experts model onto a single 32GB Blackwell GPU and runs meaningfully faster than the reference NVIDIA quantization. The release comes in two flavors: a standard variant tuned for accuracy and a Fast variant that pushes the full W4A4 path for maximum throughput.
Qwen3.6-35B-A3B-NVFP4 is a 26.5 GB checkpoint on Hugging Face under Apache 2.0. The underlying model from Alibaba is an open-weight multimodal MoE with 35 billion total parameters, 3 billion active per token, and a native 262,144 context window extensible to 1,010,000 tokens.
Why NVFP4 beats the alternatives
NVFP4 is NVIDIA's native 4-bit format for Blackwell tensor cores. Against MXFP4, it uses a block size of 16 rather than 32, so outliers are isolated more easily and scaling factors cover smaller subsets of weights. It also uses an FP8 (E4M3) block scale instead of a power-of-two E8M0 scale, which tends to work better for LLMs.
The key move in Unsloth's Dynamic NVFP4 recipe is that it does not force every layer into 4-bit. Important layers stay in FP8 (W8A8) or BF16 while the rest go to true W4A4, avoiding W4A16. That distinction matters because W4A4 actually runs on Blackwell's FP4 tensor cores, whereas W4A16 falls back to slower paths. Unsloth also bakes in FP8 KV cache calibration, which they claim doubles the usable context length at inference time.