
Unsloth's Qwen3.6-35B Hits 240 Tokens per Second on a Single GPU
Unsloth's Qwen3.6-35B-A3B MTP GGUFs bake speculative decoding into the quant, hitting 240 tokens per second on a single RTX 6000.
Takeaways
- Unsloth released Qwen3.6-35B-A3B MTP GGUFs with Multi Token Prediction baked into the quantization files.
- MTP delivers 1.4 to 2.2x faster generation with no accuracy loss, hitting 240 tokens/s on RTX 6000.
- Base model is a 35B total, 3B active MoE with hybrid Gated DeltaNet plus gated attention layers.
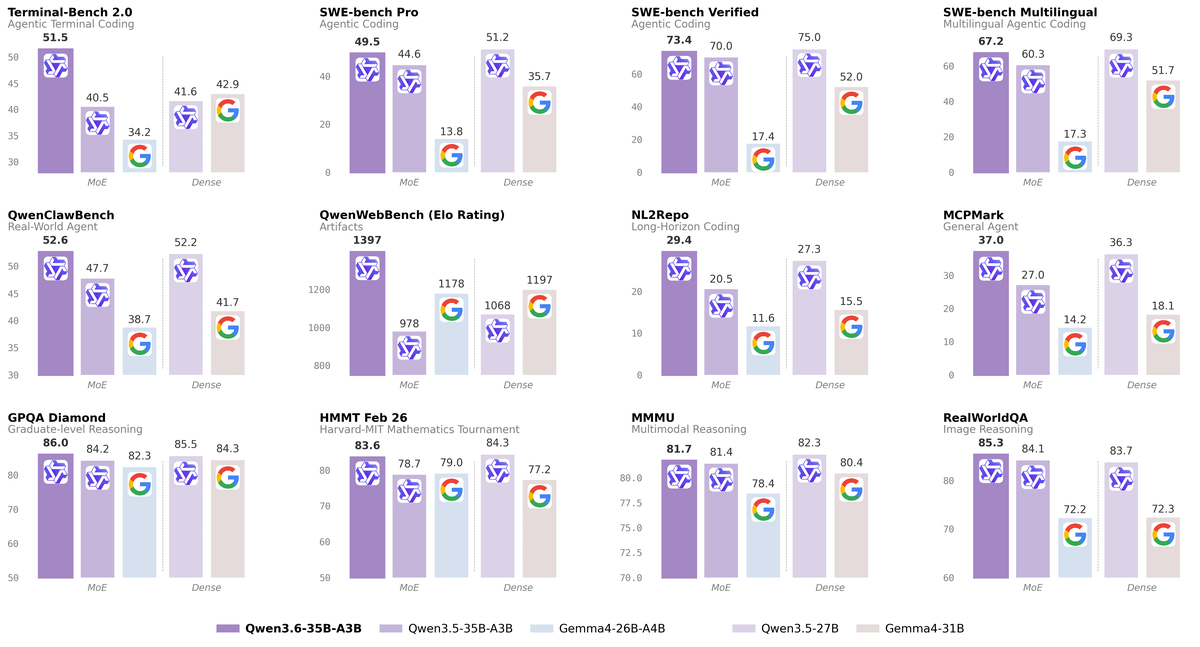
- Scores 73.4 on SWE-bench Verified, 92.7 on AIME26, with 262K native context extensible to 1M.
- Runs in 22-24 GB memory at 4-bit; quants range from 1-bit (11.4 GB) to BF16 (71 GB).
- Apache 2.0 license, multimodal input, works with Unsloth Studio, llama.cpp, vLLM, SGLang.
The Qwen3.6-35B-A3B MTP GGUF release from Unsloth packages Alibaba's newest sparse mixture of experts model with Multi Token Prediction built directly into the quantization. It targets developers who want frontier agentic coding performance running locally on a single workstation, without paying the latency tax that MoE inference usually incurs.
The base is Qwen3.6-35B-A3B, an open weight multimodal model from Alibaba Cloud. It carries 35 billion total parameters with 3 billion active per token, using a hybrid sparse mixture-of-experts architecture that combines Gated DeltaNet linear attention with standard gated attention layers. That sparsity ratio is the story: you get the representational capacity of a 35B model at roughly the compute footprint of a 3B one.
Where MTP earns its keep
Multi Token Prediction is a speculative decoding technique where the model predicts several future tokens ahead of time and then verifies them in parallel with a single forward pass. MTP lets Qwen3.6 generate roughly 1.4 to 2.2x faster with no accuracy change, giving the 27B and 35B-A3B variants better than a 1.4x speed-up over the original baseline, which matters a lot for local inference.