
Fish Audio's S2 Opens Expressive Voice AI That Whispers, Laughs, and Follows Instructions
Fish Audio S2 is a fully open-source TTS system that follows plain-English vocal instructions, generates multi-speaker dialogues, and streams audio in under 100ms
Takeaways
- Fish Audio S2 is a fully open-source TTS system that follows plain-English inline vocal instructions like
[laugh],[whispers], and[angry]at specific word positions. - Built on a Dual-Autoregressive architecture using Qwen3-4B as the backbone, trained on 10M+ hours of audio across ~80 languages.
- Achieves lowest WER on Seed-TTS-Eval among all models (including closed-source), and 81.88% win rate on EmergentTTS-Eval — beating GPT-4o and Gemini TTS.
- Production-ready SGLang inference engine delivers RTF of 0.195 and time-to-first-audio under 100ms on a single H200 GPU.
- Key innovation: the same speech quality model and ASR model used to filter training data are reused as RL reward signals, eliminating distribution mismatch between pretraining and RL.
- Weights, fine-tuning code, and inference engine are all open-source on GitHub and Hugging Face.
Fish Audio S2 is a new open-source text-to-speech system that does something most TTS models still can't do reliably: follow natural-language instructions about how to speak. Tell it to whisper a word, laugh mid-sentence, or sound angry, and it will. The team has released model weights, fine-tuning code, and a production-ready inference engine, putting a genuinely expressive, instruction-following TTS system in the hands of anyone who wants to build with it.

The gap that S2 is filling
Modern TTS has gotten very good at sounding natural in a vacuum. But controlling how a voice sounds at a specific word or phrase, without retraining the model, has remained a hard problem. Most open-source systems either rely on coarse global style prompts ("read this sadly") or require dedicated control tokens that are rigid and hard to compose. Generating coherent multi-speaker dialogues in a single pass, or keeping a voice consistent over several minutes of audio, are even harder. Generating fine-grained natural-language instructions for vocal features at scale remains a major bottleneck for the field.
On the closed-source side, models from Google and OpenAI have started to close this gap, but they come with API lock-in and no ability to fine-tune. Fish Audio S2 establishes a fully open, high-performance foundation for controllable, expressive, streaming TTS, addressing limitations of speaker adaptation, zero-shot style transfer, and fine-grained instruction following present in prior systems.
What S2 actually does
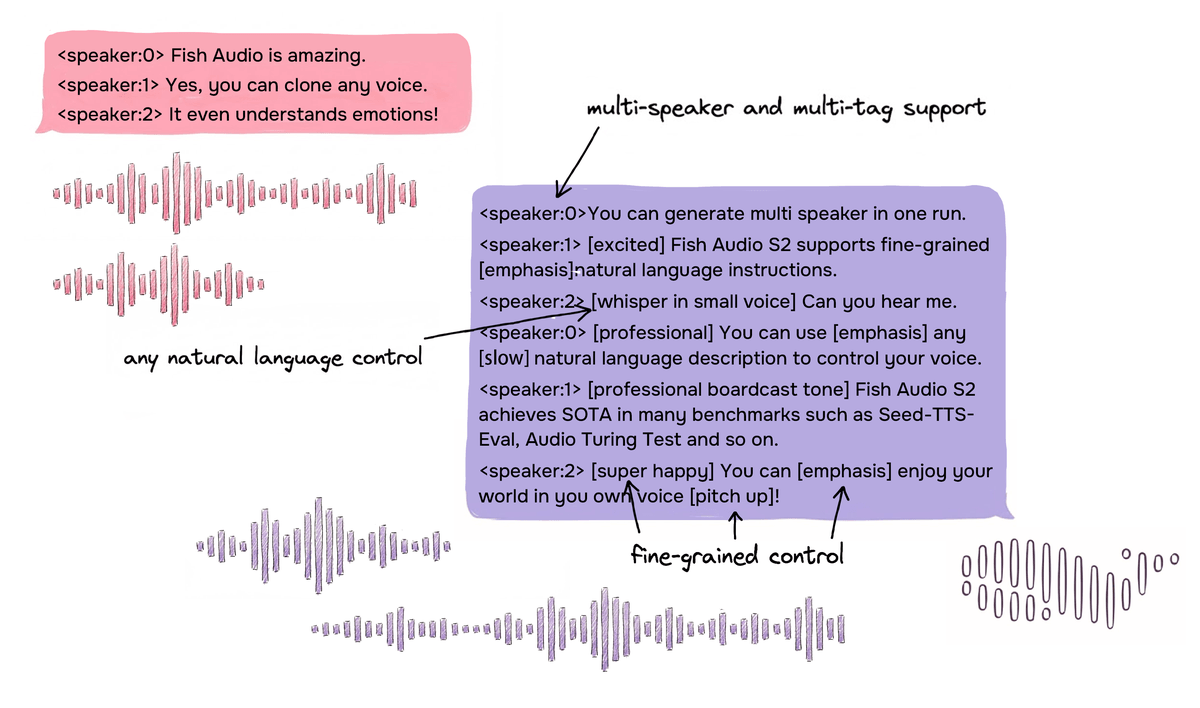
Trained on over 10 million hours of audio across approximately 80 languages, S2 combines reinforcement learning alignment with a Dual-Autoregressive architecture to generate speech that sounds natural, realistic, and emotionally rich. It supports fine-grained inline control of prosody and emotion using natural-language tags like [laugh], [whispers], and [super happy], as well as native multi-speaker and multi-turn generation.
The key practical capabilities are:
- Inline instruction tags: embed
[angry],[inhale],[emphasis], or any free-form description at any word position in the text - Multi-speaker dialogues: use
<|speaker:0|>and<|speaker:1|>tokens to generate interleaved conversations in a single pass - Long-form stability: coherent voice synthesis over extended durations without timbre drift