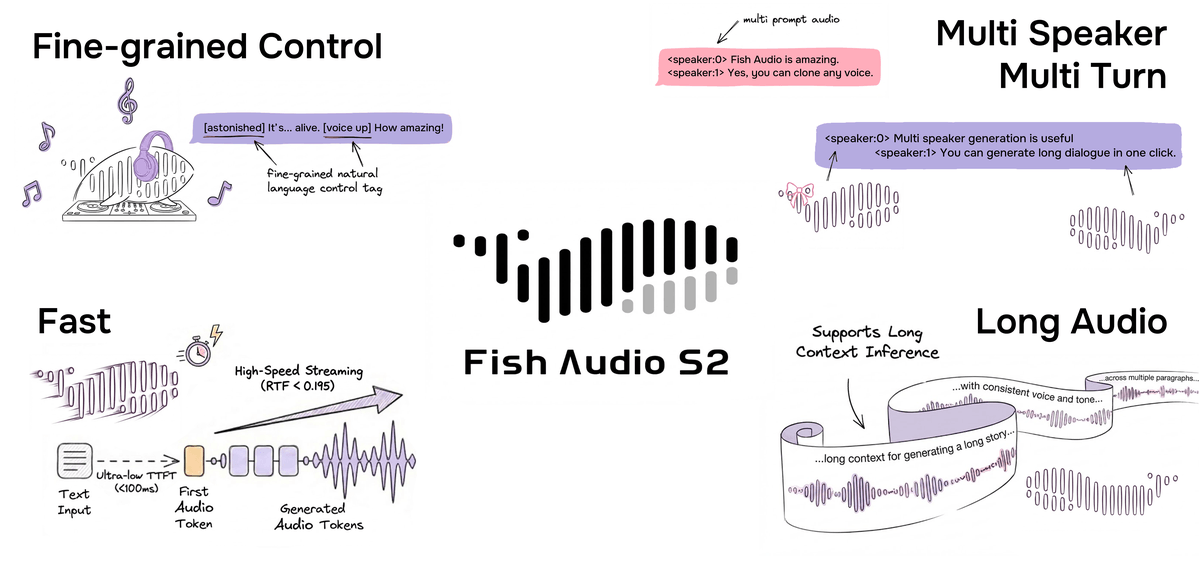
Voice cloning and TTS platform competing with ElevenLabs. Their open-source Fish Speech S2 Pro model uses a Dual-Autoregressive architecture on a Qwen3 backbone, trained on 10M+ hours across 80+ languages with GRPO reinforcement learning alignment. On Seed-TTS Eval, S2 posts the lowest WER of any evaluated system, open or closed source.
Fish Audio's new streaming speech-to-text claims the top spot on Cekura's leaderboard with 2.21% WER and conversation-aware turn-taking for voice agents.
Fish Audio's new 35B mixture-of-experts text-to-speech model ships open weights, with plain-language direction, mid-sentence voice shifts, and word-level audio inpainting.
Fish Audio's transcribe-1-pro adds inline speaker markers and emotion cues like [laughter] to transcripts across 83 languages, at $0.36 per audio hour.
Fish Audio's Drama 3 preview brings natural-language voice direction, mid-sentence tone shifts, multi-character scenes, and single-word regeneration to text-to-speech.
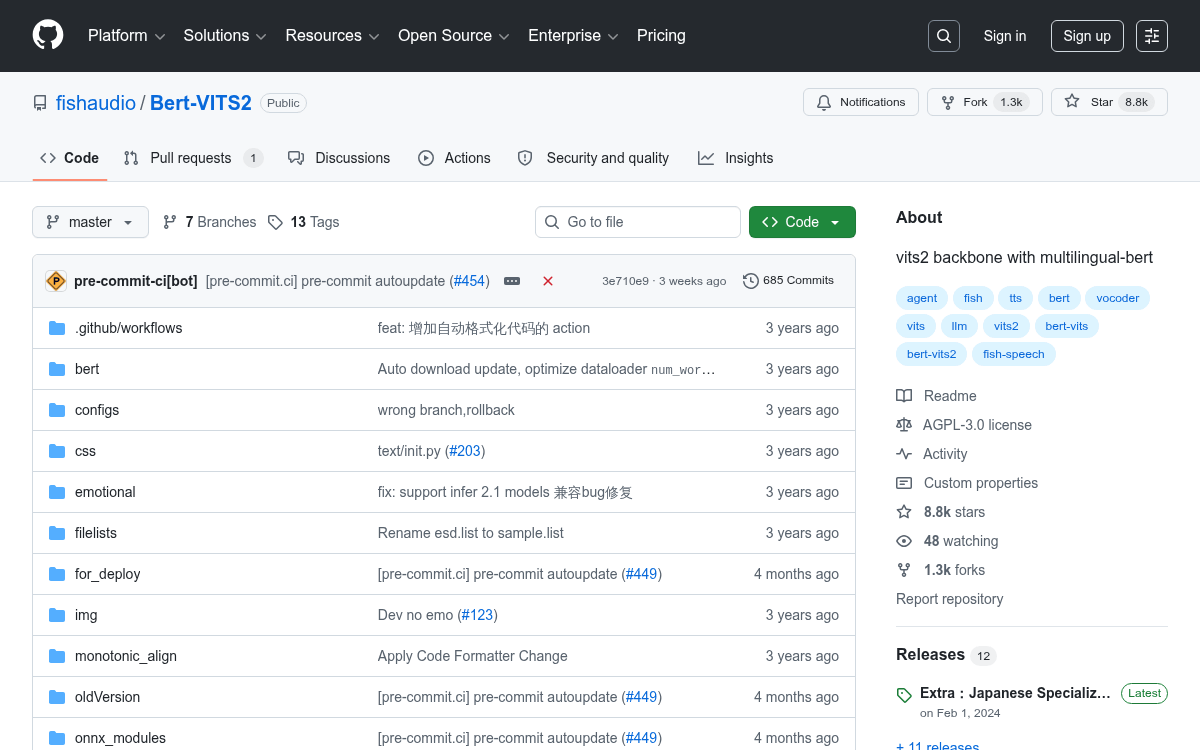
Fish Audio officially retires Bert-VITS2, pointing its 8,800-star community to Fish-Speech, a new autoregressive TTS that outperforms closed-source rivals.
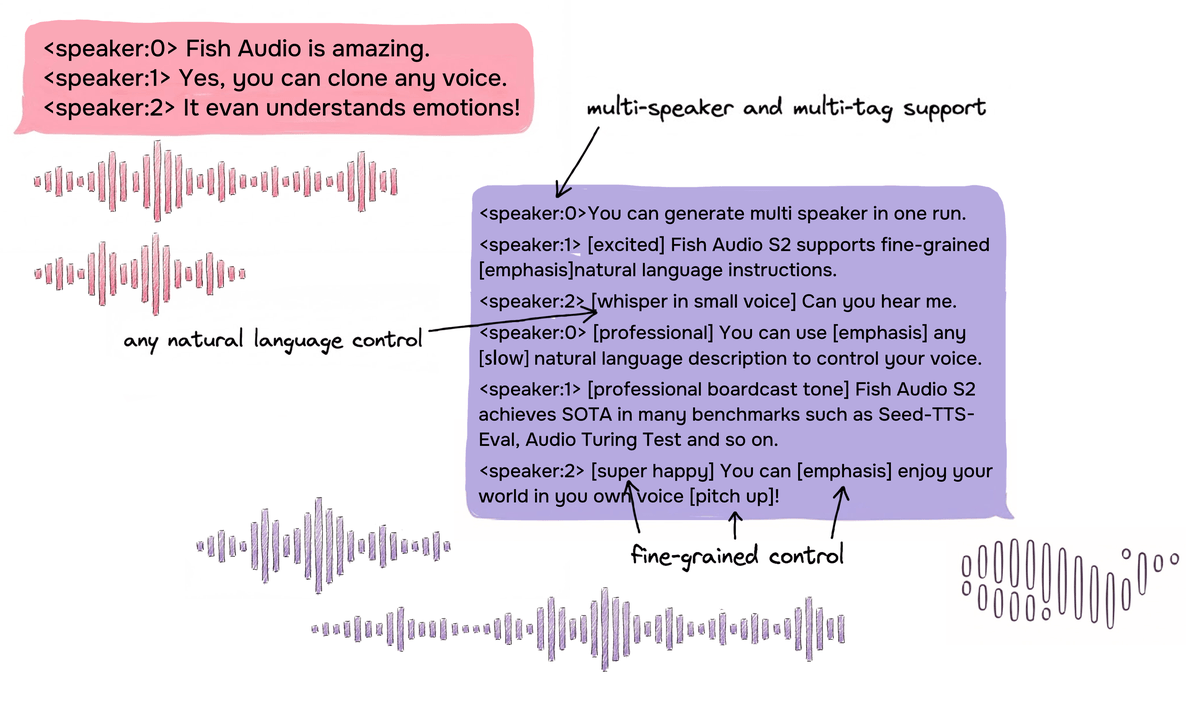
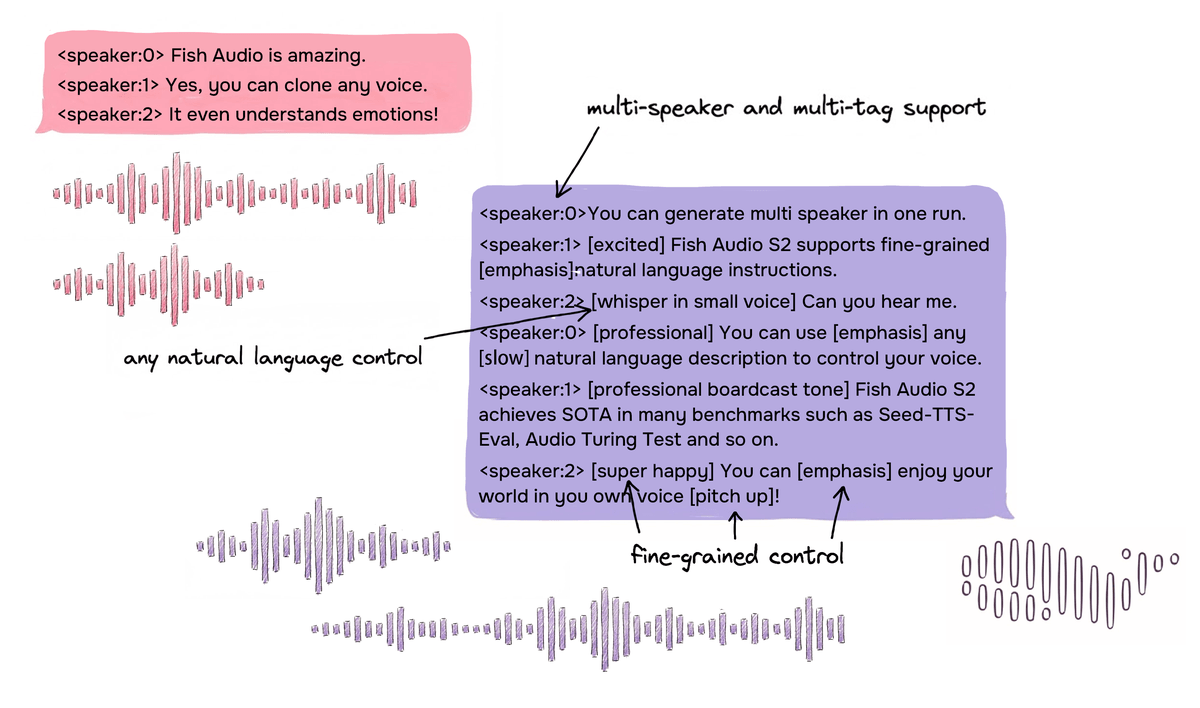
Fish Audio S2 is a fully open-source TTS system that follows plain-English vocal instructions, generates multi-speaker dialogues, and streams audio in under 100ms