
NVIDIA's GPU Operator Brings Pod-Level Visibility to Kubernetes GPU Clusters
NVIDIA GPU Operator v26.3.2 brings Kubernetes 1.36 support, richer GPU metrics with pod-level labels, and a new NRI plugin that simplifies GPU injection across non-standard Kubernetes distributions.
Takeaways
- v26.3.2 released: Latest GPU Operator adds Kubernetes 1.36 support and pod-level GPU metric labels via DCGM Exporter.
- Pod metadata in metrics: New
enablePodLabelsandenablePodUIDfields let Prometheus track GPU usage per pod without manual RBAC setup. - NRI Plugin support: CRI-O v1.34+ now supported via the Node Resource Interface, removing the need to modify container runtime config files.
- Driver recovery in seconds: v26.3.0 introduced kernel module reuse on driver container restart, cutting recovery time from minutes to seconds.
- Blackwell & RHEL 10: v26.3.0 added support for GB200 NVL4, RTX Pro 4500 Blackwell, K3s, and RHEL 10.0/10.1.
- Free & open source: Install via Helm from GitHub; Apache 2.0 licensed operator, NVIDIA terms apply to bundled images.
Running GPUs on Kubernetes has never been simple. Before tools like the GPU Operator existed, every node needed manual driver installs, custom container runtime configs, and hand-crafted device plugin setups. One bad kernel update and your entire GPU fleet could go dark. NVIDIA's GPU Operator was built to solve exactly that, and its latest release, v26.3.2, continues pushing that vision forward with better observability, broader platform support, and a smarter way to inject GPUs into containers.
What the GPU Operator Actually Does
Kubernetes provides access to special hardware resources like NVIDIA GPUs through the device plugin framework, but configuring and managing nodes with these hardware resources requires configuration of multiple software components such as drivers, container runtimes, and other libraries, which are difficult and prone to errors. The NVIDIA GPU Operator uses the operator framework within Kubernetes to automate the management of all NVIDIA software components needed to provision GPUs.
The components it manages include:
- NVIDIA drivers (to enable CUDA)
- The Kubernetes device plugin for GPU resource scheduling
- The NVIDIA Container Toolkit (runtime hooks)
- Automatic node labeling using GPU Feature Discovery (GFD)
- DCGM-based GPU monitoring and metrics export
- MIG (Multi-Instance GPU) manager for partitioning large GPUs
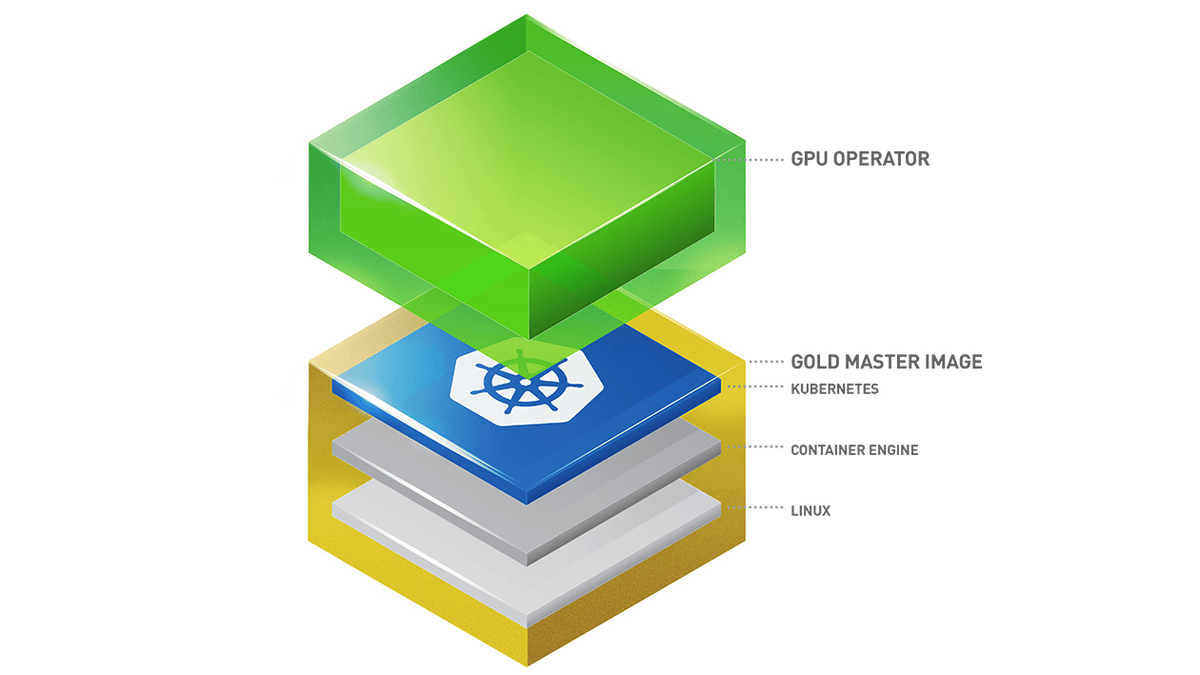
The GPU Operator allows administrators of Kubernetes clusters to manage GPU nodes just like CPU nodes. Instead of provisioning a special OS image for GPU nodes, administrators can rely on a standard OS image for both CPU and GPU nodes and then rely on the GPU Operator to provision the required software components for GPUs.
What's New in v26.3.2
Version 26.3.2 adds support for Kubernetes 1.36 , keeping the Operator current with the latest upstream Kubernetes releases. The headline feature for platform teams is a significant upgrade to GPU metrics observability.