Distributed training
Subtopic of Training infra
About
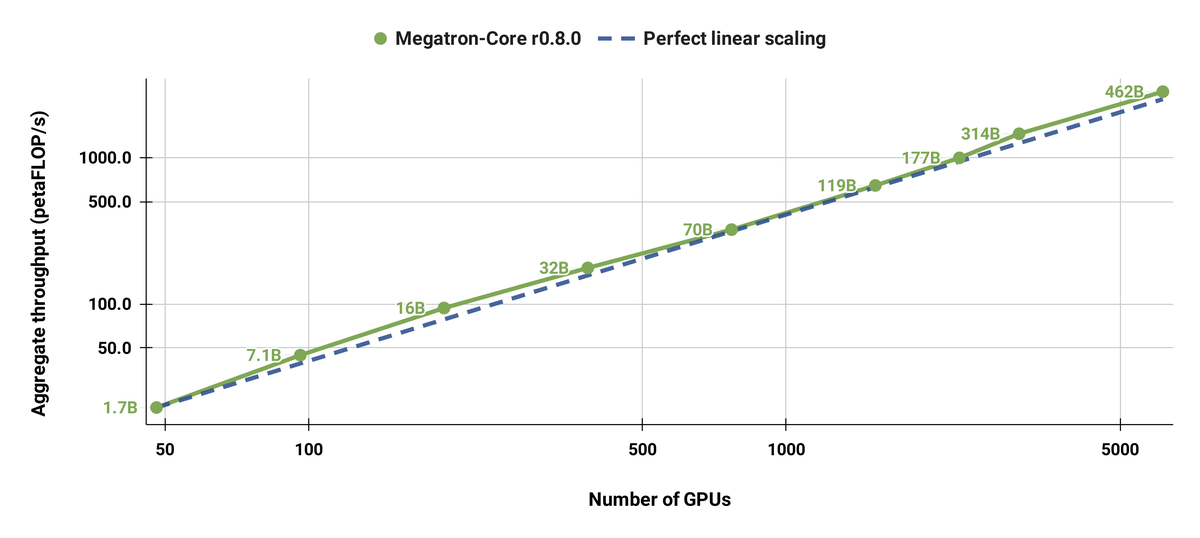
Splitting a training run across many GPUs and machines so a huge model can be trained in reasonable time. It means coordinating thousands of chips, keeping them busy and recovering when one fails. It's a large part of what lets labs train ever-bigger models.
Activity
2026
94 stories so far in 2026
| Month | Stories |
|---|---|
| January | 0 |
| February | 0 |
| March | 4 |
| April | 3 |
| May | 1 |
| June | 22 |
| July | 11 |
| August | 6 |
| September | 15 |
| October | 24 |
| November | 8 |
| December | 0 |
Part of
Top companies
94 stories