Moonshot AI's Kimi platform serves the K2 model family: sparse MoE architecture, 1T total parameters, 32B active per token, trained on 15.5T tokens using the MuonClip optimizer. Models support 256K token contexts, native multimodal input, and agentic tool-calling. Open weights (Modified MIT) deployable via vLLM or SGLang; OpenAI/Anthropic-compatible API available.
Moonshot AI drops the open weights for its 2.8T-parameter flagship, a post-training overhaul of Kimi K3 that nearly ties Claude Opus 5.5 on agentic coding.
Moonshot AI's PerceptionBench reveals no frontier model clears 60% accuracy on pure visual perception tasks, exposing a critical gap in how we evaluate multimodal AI.
Moonshot AI releases Kimi K3, a 2.8T open-weight MoE model with a 1M-token context window that beats frontier models on sustained coding and agentic tasks
Moonshot AI open-sources Kimi-Audio-7B-Instruct, a single model that handles speech recognition, emotion detection, audio Q&A, and live voice chat — beating GPT-4o-mini on conversation quality.
Moonshot AI's Moonlight proves the Muon optimizer scales to 16B-parameter MoE models, cutting training compute in half while beating Llama and Qwen at the same scale.
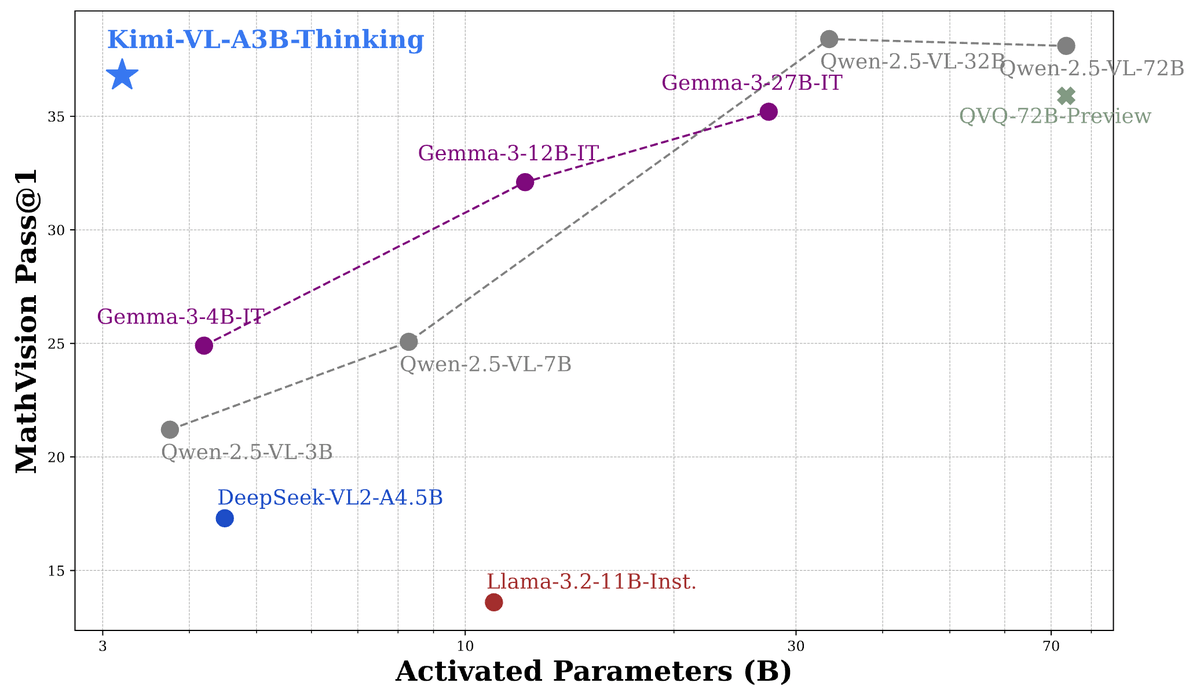
Moonshot AI's Kimi-VL-A3B-Thinking packs 16B total parameters into a 2.8B-active MoE model that rivals 70B-scale VLMs on math and visual reasoning benchmarks
Moonshot AI's 1-trillion-parameter open-weight model tops the LMSYS leaderboard for open-source models, rivaling Claude and GPT on coding and agentic tasks
Moonshot AI's Kimi K2.7 Code lands on AWS Marketplace with EDP billing support, giving enterprise AWS teams a frontier-grade open-weight coding model without a new vendor contract
Kimi Work's new Goal Mode lets a local desktop agent pursue multi-step objectives autonomously, running round after round until the task is done -- no re-prompting required.
Moonshot AI's open-source 1T-parameter coding model gets a 6x speed boost, raising the bar for agentic coding workflows at a fraction of closed-model prices
Moonshot AI's open-weight 1T-parameter model tops SWE-Bench Pro, runs 13-hour autonomous coding sessions, and deploys on 4x H100s at a fraction of Claude's price